By maxaeo.ai | Published 2026-10-29 | Updated 2026-10-29
If your site returns 403, 429, or a challenge page to OAI-SearchBot, the crawler may be blocked by AWS WAF, a managed bot rule, rate limiting, or an upstream CDN. To unblock OAI-SearchBot AWS WAF rule behavior safely, allow the crawler only after verifying both its user-agent and its source IP, then place the exception before blocking rules.
What is OAI-SearchBot, and why does AWS WAF block it?
OAI-SearchBot is OpenAI’s crawler for discovering websites that may appear in ChatGPT search results. It is separate from GPTBot, which OpenAI describes as a crawler used for training-related purposes, and from ChatGPT-User, which represents user-triggered fetches. OpenAI recommends allowing OAI-SearchBot in robots.txt and allowing requests from its published IP ranges. (developers.openai.com)
AWS WAF can still block the request even when robots.txt permits it. Common causes include:
- AWS Managed Rules detecting an unfamiliar automated client
- A custom rule blocking non-browser user-agents
- AWS WAF Bot Control labeling the request as a search or content-fetching bot
- A rate-based rule returning
429 - CAPTCHA, challenge, or JavaScript checks that a crawler cannot complete
- An allow rule placed below a terminating block rule
The key distinction is important: robots.txt expresses crawl permission, while AWS WAF controls whether the HTTP request reaches your application.
Before changing AWS WAF, separate the four failure points
A reliable diagnosis checks the request path in order rather than adding a broad “allow OpenAI” exception.
| Layer | What to inspect | Typical failure |
|---|---|---|
| DNS/CDN | Which service receives the request first | A different WAF blocks traffic |
robots.txt |
User-agent: OAI-SearchBot rules |
The crawler is disallowed |
| AWS WAF | Rule labels, action, priority, sampled request | 403, CAPTCHA, or rate limit |
| Origin/server | Access logs and response headers | 5xx, redirect loop, or auth block |
A practical four-request test is more useful than checking only the browser. Send the same public URL with a normal browser user-agent, the OAI-SearchBot user-agent, the OAI-SearchBot user-agent from a verified source IP, and the bot user-agent from an unverified IP. Record the HTTP status, response length, redirect chain, and WAF rule ID.
Expected interpretation:
- Browser
200, bot403: likely WAF or bot mitigation - Both browser and bot
403: application, authentication, origin, or CDN issue - Bot
429: rate-based rule or upstream throttling - Bot
200with a challenge body: technically allowed by one rule but unusable to a crawler
This test also exposes a common security mistake: trusting the user-agent alone. A malicious client can send OAI-SearchBot in a header without being operated by OpenAI.
How to create a safer OAI-SearchBot allow rule in AWS WAF
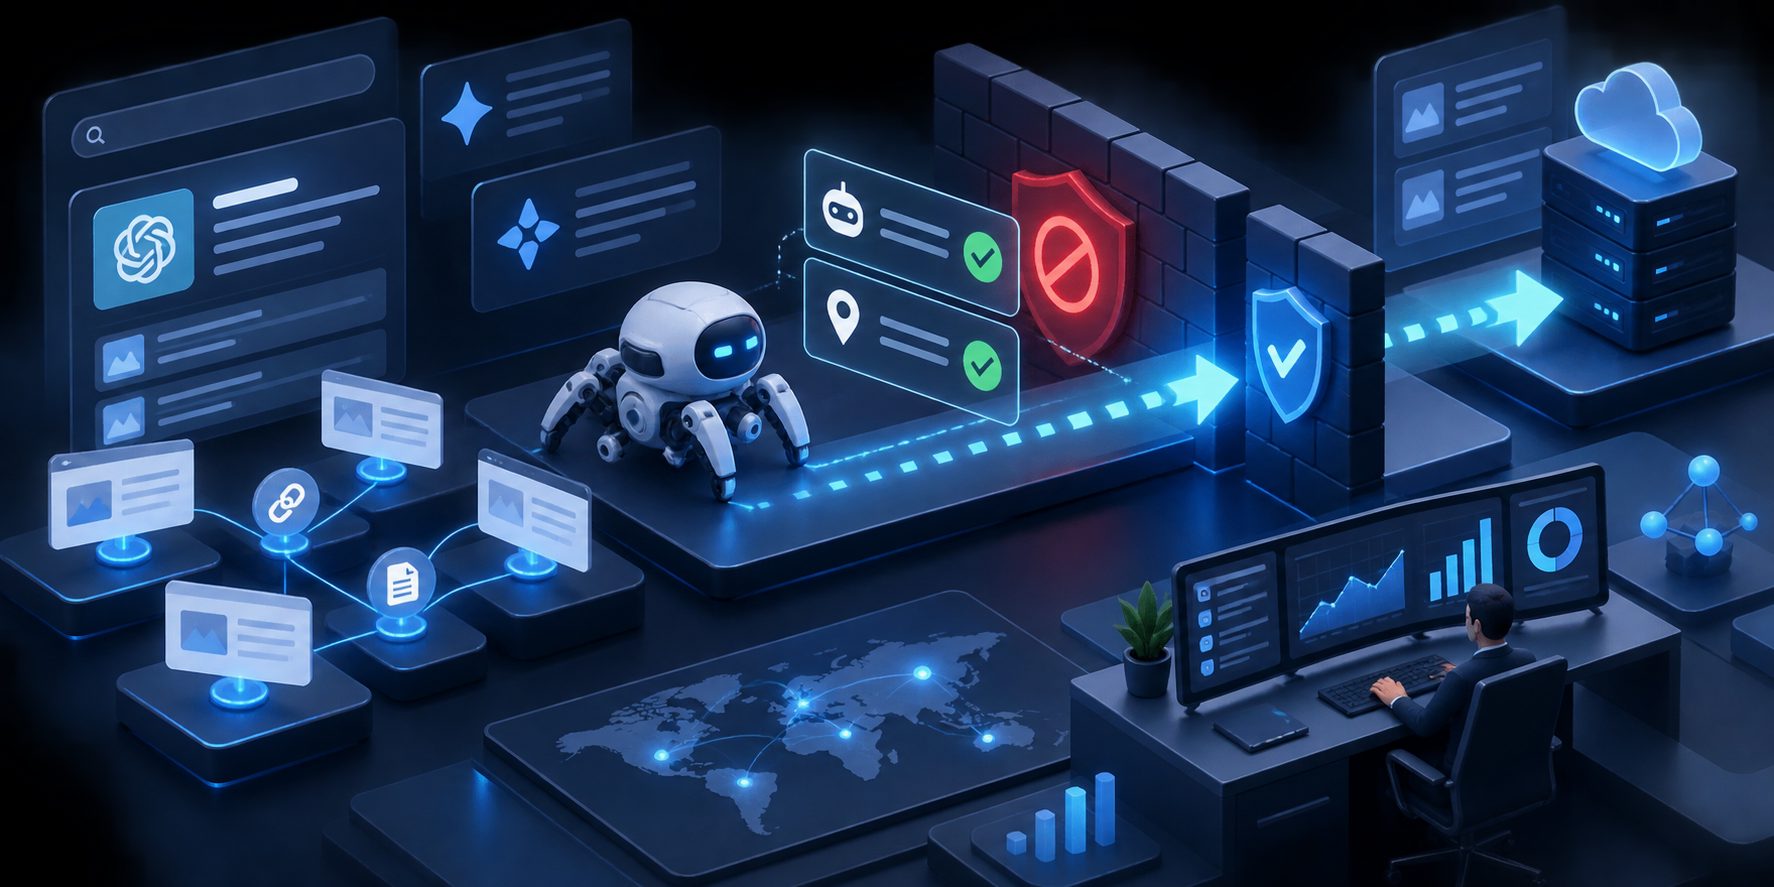
The safest AWS WAF design uses a two-factor match:
- The request user-agent contains
OAI-SearchBot. - The source address belongs to OpenAI’s published OAI-SearchBot ranges.
OpenAI publishes crawler IP addresses separately for its bots, including searchbot.json. Do not copy a third-party list into a permanent rule; use OpenAI’s official range source and establish a review process when the list changes. (developers.openai.com)
Step 1: Create an IP set
In AWS WAF:
- Open the Web ACL attached to CloudFront, an Application Load Balancer, or API Gateway.
- Create an IP set for IPv4 addresses.
- Add the current CIDR ranges published for OAI-SearchBot.
- Create a separate IPv6 IP set only if OpenAI publishes applicable IPv6 ranges for your deployment.
- Name it clearly, such as
openai-oai-searchbot-ipset.
Avoid combining OAI-SearchBot, GPTBot, and ChatGPT-User into one IP set. Their purposes differ, and a single exception can unintentionally broaden access.
Step 2: Match the user-agent token
Create a custom statement that matches the User-Agent header for the token:
OAI-SearchBot
Use a case-insensitive contains match or a regex match that targets the token rather than the entire user-agent string. OpenAI notes that the version number and surrounding browser text may change, so matching the full example string is brittle. (developers.openai.com)
Conceptually, the rule should be:
(User-Agent contains "OAI-SearchBot")
AND
(source IP is in the OAI-SearchBot IP set)
In AWS WAF JSON-style logic, the structure is equivalent to:
{
  "AndStatement": {
    "Statements": [
      {
        "ByteMatchStatement": {
          "FieldToMatch": { "SingleHeader": { "Name": "user-agent" } },
          "PositionalConstraint": "CONTAINS",
          "SearchString": "OAI-SearchBot",
          "TextTransformations": [
            { "Priority": 0, "Type": "LOWERCASE" }
          ]
        }
      },
      {
        "IPSetReferenceStatement": {
          "ARN": "arn:aws:wafv2:REGION:ACCOUNT:regional/ipset/openai-oai-searchbot-ipset/ID"
        }
      }
    ]
  }
}
The ARN, scope, and IP version must match your actual Web ACL. CloudFront Web ACLs use the global scope in us-east-1; regional resources use their regional scope.
Step 3: Put the rule before terminating blocks
Set the allow rule priority above:
- AWS Managed Rules that block automated traffic
- Bot Control rules
- Custom “block unknown bots” rules
- Rate-based rules that would terminate the request
- CAPTCHA or challenge actions
AWS WAF evaluates rules in priority order. An allow action can stop later rules from inspecting the request, but it cannot undo a block that has already terminated evaluation.
AWS WAF Bot Control also exposes labels for bot categories such as search engines and content fetchers. If you use Bot Control, inspect the labels in sampled requests before deciding whether to exempt or allow a category. (docs.aws.amazon.com)
Should you allow by user-agent only?
No, not for a production WAF exception.
A user-agent-only rule is easy to impersonate. It may solve a 403 quickly, but it weakens the purpose of your bot protection and can expose endpoints that should remain private. The IP-plus-user-agent rule is narrower and easier to audit.
You can use a temporary user-agent-only rule in a controlled test environment, but log it, limit its path scope, and remove it after verification. Never apply the exception to login, checkout, admin, upload, or API mutation routes unless there is a separate business requirement.
Validate the fix at the edge, not only at the origin
After publishing the rule, repeat the four-request test. Check:
- AWS WAF sampled requests show the intended rule action.
- CloudFront or load balancer logs show the expected status.
- The response body is the actual HTML, not a CAPTCHA or JavaScript challenge.
- Redirects do not send the crawler to a blocked hostname.
robots.txtpermits OAI-SearchBot for the paths you want discovered.
A successful 200 response is necessary but not sufficient. The returned page should contain readable server-rendered content, a canonical URL, and no authentication barrier. If the page depends on client-side JavaScript to reveal its main content, the crawler may receive a technically successful response with little useful text.
For related failure modes, see this guide to debugging WAF 403 errors for OpenAI crawlers and the broader AWS WAF allowlist guide for AI search agents.
What to do if OAI-SearchBot still receives 403 or 429
Use this troubleshooting sequence:
- Check the actual source IP. Confirm it belongs to OpenAI’s published OAI-SearchBot ranges.
- Inspect WAF logs. Identify the terminating rule, not merely the first matching rule.
- Review rule priority. Move the narrowly scoped allow rule above the blocker.
- Check the CDN layer. CloudFront, a third-party CDN, or an origin firewall may apply a separate policy.
- Inspect redirects. A permitted homepage can redirect to a protected regional or language URL.
- Review rate limits. Exempt only verified crawler traffic, and avoid broad IP-based exemptions.
- Test
robots.txt. WAF access does not override a disallow directive. - Compare response bodies. A 200 status containing a challenge page is not a successful crawl.
Do not assume that allowing OAI-SearchBot will automatically increase citations or recommendations. It removes one technical access barrier; content quality, source authority, relevance, and how AI systems evaluate your pages still matter.
How to monitor whether the unblock improved AI visibility
Server logs tell you whether a crawler requested a page. They do not tell you whether your brand is mentioned, recommended, or cited in AI answers.
A separate visibility workflow should track:
- Brand mention rate
- Average recommendation position
- Competitor visibility
- Sentiment and factual accuracy
- Cited domains and specific source pages
- Trends by AI engine and prompt
MaxAEO monitors brand visibility across eight AI engines, including ChatGPT, Perplexity, Gemini, Claude, Copilot, Grok, Google AI Mode, and Google AI Overview. Its daily monitoring and citation tracking can help distinguish “the crawler can access my site” from “AI systems actually use my content.” A free AI visibility diagnostic provides a starting audit using your brand and website information.
Frequently asked questions
Does allowing OAI-SearchBot also allow GPTBot?
No. OpenAI documents these as separate user agents with different purposes. Create separate robots.txt, IP, and WAF decisions for each crawler. (developers.openai.com)
Can I allow OAI-SearchBot with only robots.txt?
Only if your WAF and other infrastructure already permit the request. robots.txt does not override AWS WAF blocks, rate limits, authentication, or CDN challenges.
Why does the user-agent match but the rule still block?
The request may come from an unverified IP, or a higher-priority rule may terminate evaluation first. Check the terminating rule ID and source address in AWS WAF logs.
Should the rule cover the whole site?
Prefer a narrow public-content scope where practical. Exclude administrative, transactional, private, and mutation endpoints from crawler exceptions.
Does a successful crawl guarantee ChatGPT visibility?
No. It only confirms that the crawler can retrieve the response. AI visibility also depends on whether the content is relevant, trustworthy, accessible, and selected for a particular answer.