By maxaeo.ai | Published 2026-10-25 | Updated 2026-10-25
Allowlisting AI search agents in AWS WAF means permitting verified, identifiable crawler traffic without weakening protection for unknown bots, scrapers, or automated browser sessions. The safest approach combines AWS WAF Bot Control labels, narrowly scoped custom rules, request logging, and post-change validation.
For SaaS companies, this matters because an AI search crawler may need to retrieve public documentation, pricing explanations, comparison pages, or product pages before an answer engine can cite or recommend the brand. A WAF that returns a 403, CAPTCHA, challenge, or rate-limit response can make otherwise public content difficult for AI systems to access.
What should an AWS WAF allowlist actually permit?
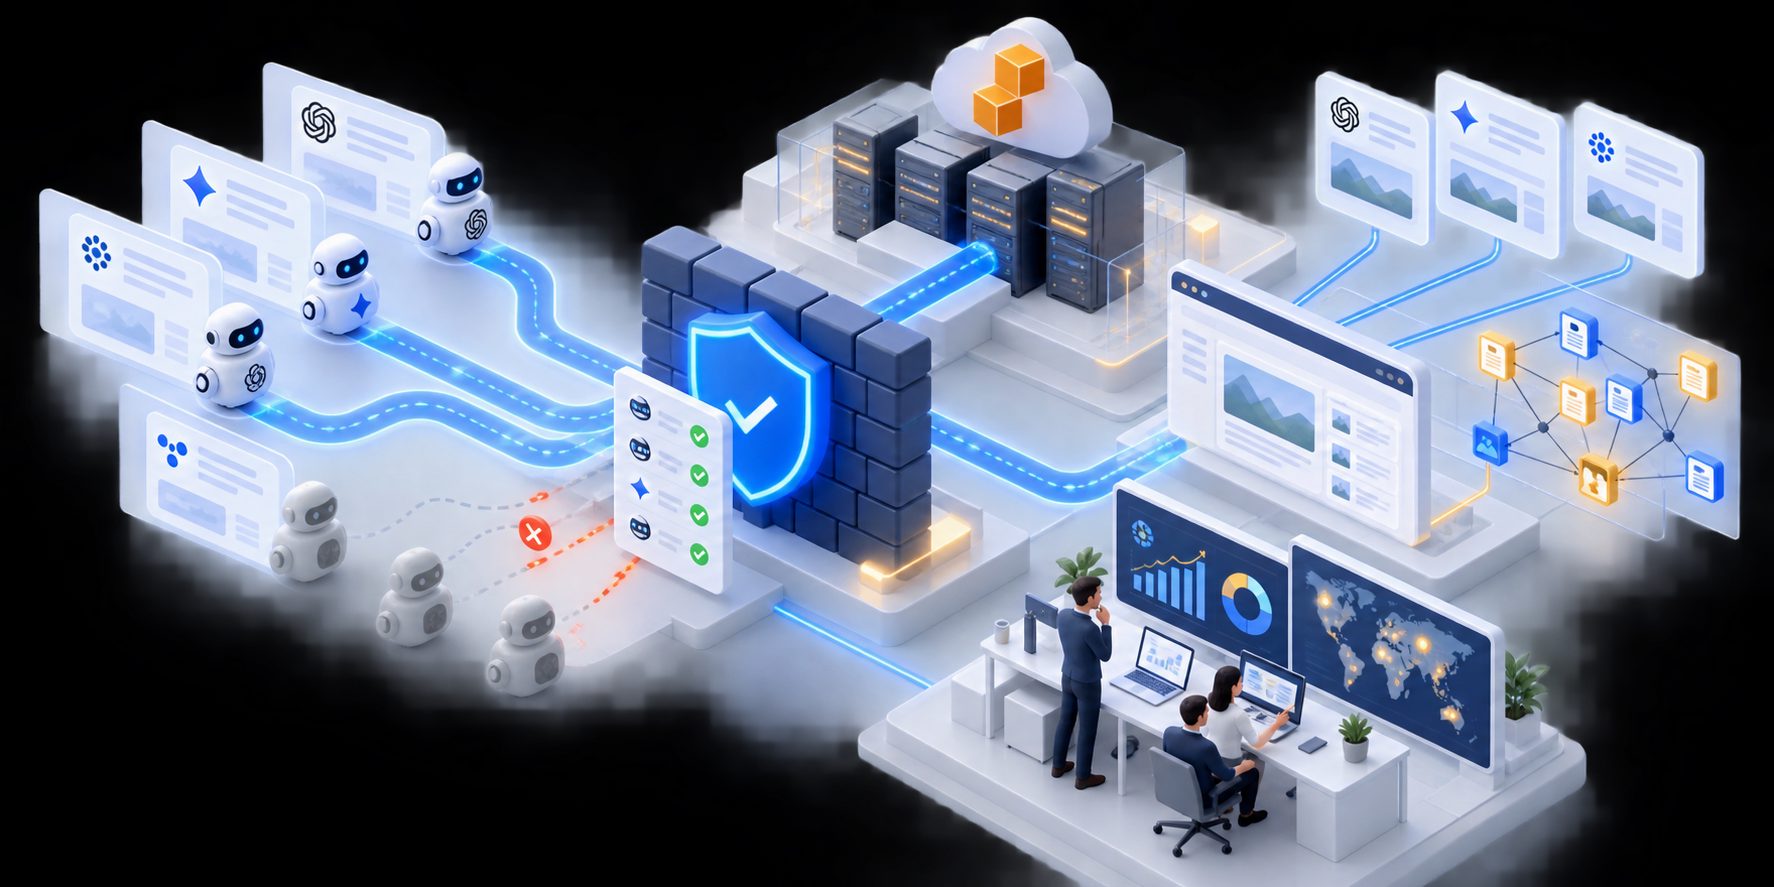
An AWS WAF allowlist should permit a verified identity or tightly defined exception, not every request that contains an AI-related user-agent string. User-agent values are easy to copy, while verified bot labels provide a stronger basis for access decisions.
AWS WAF Bot Control classifies bot traffic and can apply labels for bot name, category, organization, and verification status. AWS recommends using custom rules with these labels when you want to allow specific bots, block others, or apply different controls to different categories. See the AWS WAF Bot Control use-case guidance.
A practical policy separates traffic into four groups:
| Traffic group | Recommended action | Reason |
|---|---|---|
| Verified search or AI crawler | Allow or monitor | Identity has passed AWS detection |
| Known but unverified AI crawler | Rate-limit or monitor | User-agent alone is insufficient |
| Browser-automation agent | Challenge or restrict | May behave like a real browser |
| Unknown scraper | Block or rate-limit | No trusted identity signal |
This distinction is important because AI search agents are not all simple crawlers. Some retrieve HTML directly, while others use browser automation, JavaScript execution, or user-triggered browsing flows.
How AWS WAF Bot Control fits into the configuration
AWS WAF Bot Control is a managed rule group that can be attached to a Web ACL protecting CloudFront, Application Load Balancer, API Gateway, or other supported AWS resources. It evaluates bot behavior and creates labels that later custom rules can match.
The rule order matters:
- Add the AWS Managed Rules Bot Control rule group.
- Place custom allow, rate-limit, or block rules after Bot Control.
- Match the labels generated by Bot Control.
- Confirm the final rule action in WAF logs and CloudWatch metrics.
AWS’s own example for explicitly allowing verified bots uses the label:
awswaf:managed:aws:bot-control:bot:verified
The corresponding custom rule can use a LabelMatchStatement with an Allow action. The official AWS WAF Bot Control examples show the JSON structure and rule-placement requirement.
Do not place a label-based allow rule before Bot Control. At that point, the label does not exist yet, so the rule cannot match the request.
A safer three-signal allowlist model
A useful operational model is to evaluate AI crawler traffic through three signals:
Signal 1: Bot Control verification
Use AWS-generated labels whenever possible. A verified label is stronger than a raw User-Agent header because it is based on AWS’s bot-detection and verification logic.
For example, a policy may allow verified bots while applying separate controls to traffic that AWS identifies as automated but not verified.
Signal 2: Request scope
Limit the exception to content that should be publicly retrievable. Most AI search access should not require access to:
/admin//login//account/- Internal APIs
- Checkout and billing paths
- Private documentation
- User-specific endpoints
A narrowly scoped rule can allow a verified crawler on public GET and HEAD requests while leaving sensitive paths under the normal security policy.
Signal 3: Behavioral evidence
Review request volume, response codes, requested paths, and geographic or network patterns. Even a legitimate crawler can create operational problems if it requests expensive pages too frequently.
This three-signal model is more resilient than a single rule such as:
IF User-Agent contains "GPTBot"
THEN Allow
A user-agent-only rule can be spoofed and may accidentally bypass protections intended for unknown automation.
Example AWS WAF rule design
A conservative Web ACL might use the following sequence:
Priority 10: AWSManagedRulesBotControlRuleSet
Priority 20: Allow verified bot labels on public content
Priority 30: Rate-limit unverified AI-like traffic
Priority 40: Block known malicious bot categories
Priority 50: Apply general application security rules
For a label-based allow rule, the conceptual JSON is:
{
  "Name": "AllowVerifiedBotsOnPublicContent",
  "Priority": 20,
  "Statement": {
    "AndStatement": {
      "Statements": [
        {
          "LabelMatchStatement": {
            "Scope": "LABEL",
            "Key": "awswaf:managed:aws:bot-control:bot:verified"
          }
        },
        {
          "ByteMatchStatement": {
            "FieldToMatch": {
              "Method": {}
            },
            "PositionalConstraint": "EXACTLY",
            "SearchString": "GET",
            "TextTransformations": [
              {
                "Priority": 0,
                "Type": "NONE"
              }
            ]
          }
        }
      ]
    }
  },
  "Action": {
    "Allow": {}
  }
}
This is a design example rather than a universal production rule. You should adapt the statement to your Web ACL, protected resource, path structure, and security requirements.
If the request passes through a proxy or load balancer, verify which client IP AWS WAF evaluates. AWS documentation notes that Bot Control verification uses the originating request IP, while forwarded-IP logic may require a separate rule before Bot Control. That detail can affect verification results.
How to handle OpenAI and other AI crawler identities
AI platforms may use separate crawler identities for different purposes. OpenAI, for example, distinguishes OAI-SearchBot for search visibility from GPTBot, which relates to model training controls. The identities should not be treated as interchangeable. OpenAI explains the distinction in its crawler documentation.
The same principle applies to other AI platforms:
- Confirm the crawler’s official identity documentation.
- Separate search retrieval from training or dataset collection where the provider supports that distinction.
- Prefer verified detection over a static user-agent match.
- Review robots.txt, WAF, CDN, authentication, and rate-limit behavior together.
Allowing a crawler through AWS WAF does not override robots.txt. Conversely, allowing a bot in robots.txt does not help if the WAF returns an error before the page is delivered.
For a broader troubleshooting workflow, see GPTBot, OAI-SearchBot, and ChatGPT-User: what each robots.txt rule means.
Validation checklist after deployment
A WAF exception is not complete when the rule is saved. Validate the full retrieval path:
- Check WAF sampled requests and logs. Confirm the intended crawler receives an
Allowaction. - Inspect origin responses. A WAF allow does not prevent the origin, CDN, authentication layer, or application from returning 403, 401, 429, or 5xx responses.
- Test public and restricted paths. The crawler should reach public content but remain blocked from private routes.
- Review response latency. Slow pages may still be difficult for retrieval systems to process.
- Monitor volume after deployment. Use CloudWatch metrics and WAF logs to identify unexpected spikes.
- Recheck after rule updates. Bot signatures and managed rule versions can change over time.
AWS also documents Web Bot Authentication for cryptographic verification of supported AI agent traffic. Where applicable, this provides a stronger identity signal than IP addresses or user-agent strings. The AWS Security Blog guide to authenticating legitimate AI agent traffic describes verification labels such as verified, invalid, and expired.
WAF access is only one part of AI search visibility
A crawler reaching your page does not guarantee that an AI answer engine will mention or cite the brand. Retrieval depends on page clarity, factual consistency, source authority, content structure, and competitive relevance.
After fixing WAF access, track whether AI systems actually retrieve and represent your content. MaxAEO monitors brand mentions, rankings, sentiment, and citation sources across eight AI engines, including ChatGPT, Gemini, Perplexity, Claude, Copilot, Grok, Google AI Mode, and Google AI Overviews. Its citation tracking can identify domains and pages appearing in AI answers, while competitor comparisons show differences in mentions and source coverage.
Use the Cloudflare and WAF troubleshooting guide for AI crawlers to compare firewall failures with broader AI retrieval problems, then run a free AI visibility audit to establish a baseline.
Common questions
Should every AI crawler be allowlisted?
No. Allow only identities and traffic patterns that match your business policy. Verified search crawlers may deserve access to public content, while unknown scrapers, training crawlers, or automated browsers may require rate limits or blocking.
Is a user-agent rule enough?
Usually not. User-agent strings can be spoofed. Use AWS WAF Bot Control labels or another reliable verification signal, then add path, method, and rate controls.
Should the allow rule run before Bot Control?
No. Label-based rules must run after the Bot Control managed rule group so AWS has time to generate the labels that the custom rule evaluates.
Can AWS WAF allow access to only documentation pages?
Yes. Combine the bot identity condition with URI path and HTTP method conditions. This lets verified agents retrieve public documentation while keeping administrative, transactional, and private routes protected.
How can a team confirm that the change improved AI visibility?
Compare WAF logs and origin status codes with AI visibility metrics. A successful fix should reduce retrieval errors, but mention rate, recommendation position, sentiment, and citations should be measured separately.