By maxaeo.ai | Published 2026-10-31 | Updated 2026-10-31
If you need to fix ChatGPT Search crawler timeout error messages, start with your website infrastructure rather than your page copy. The most common causes are slow DNS resolution, delayed server responses, robots.txt failures, WAF challenges, rate limits, and bot protection that treats OpenAI traffic as suspicious.
A timeout does not always mean that ChatGPT is unavailable. It can mean that ChatGPT Search, a crawler, or a user-triggered fetch could not complete the request within its permitted time.
What does a ChatGPT Search crawler timeout mean?
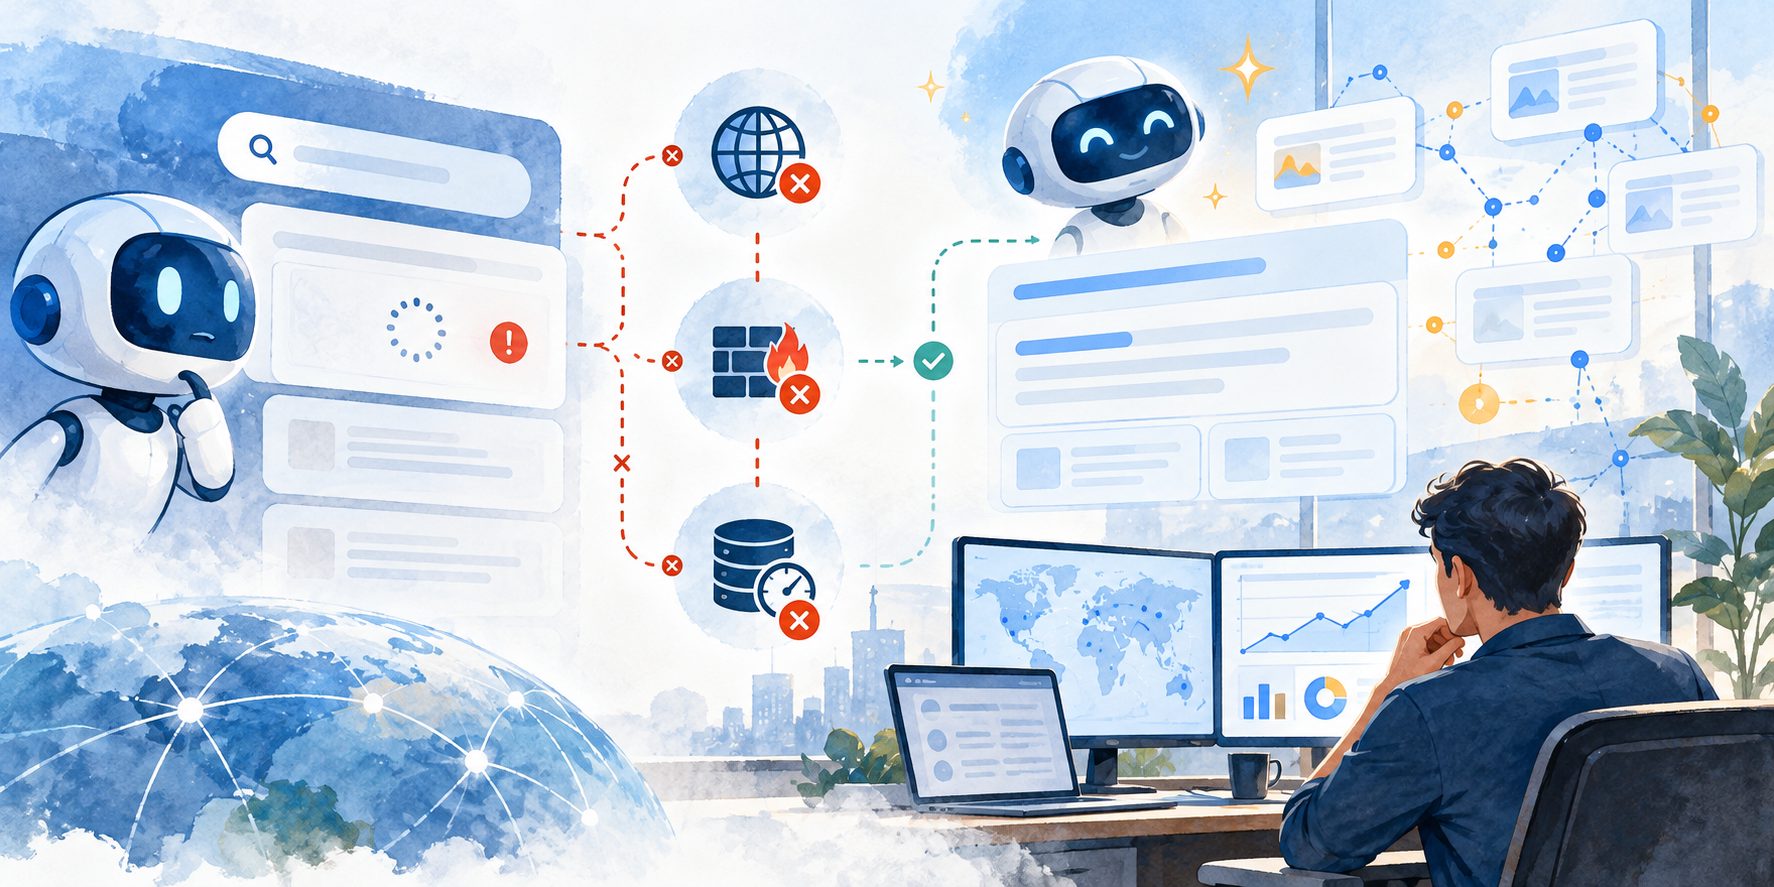
A ChatGPT Search crawler timeout means the request did not receive a usable response quickly enough. The failure can occur before the request reaches your origin server, while fetching robots.txt, during TLS negotiation, or when your application is generating the page.
OpenAI identifies OAI-SearchBot as the crawler used to help surface websites in ChatGPT Search. OpenAI also distinguishes it from other agents, including GPTBot and ChatGPT-User. Allowing one does not automatically mean that every OpenAI user agent is allowed. (developers.openai.com)
This distinction is important because a site may work normally in Chrome while still timing out for an automated request.
How to identify the failing layer
Before changing firewall rules, determine where the delay occurs. Use this four-layer model:
| Layer | Typical symptom | What to inspect |
|---|---|---|
| DNS | Hostname resolution takes too long | DNS provider, nameservers, propagation |
| Edge security | 403, 429, challenge page, or connection reset | CDN, WAF, bot rules, rate limits |
| Origin server | Connection succeeds but response is slow | TTFB, application logs, database queries |
| Page rendering | HTML arrives but content is incomplete | JavaScript dependencies, redirects, APIs |
A useful original diagnostic rule is “same URL, three vantage points.” Test the URL from a normal browser, a server outside your hosting network, and a request that uses the documented crawler user agent. If only the crawler-style request fails, the problem is probably access control rather than page availability.
How to fix ChatGPT Search crawler timeout error
1. Test DNS and connection timing
Start by checking whether the hostname resolves consistently. Test both the apex domain and the www version if both exist.
dig example.com
dig www.example.com

curl -I -L --max-time 20 https://example.com/
curl -sS -o /dev/null \
  -w "dns:%{time_namelookup} connect:%{time_connect} tls:%{time_appconnect} start:%{time_starttransfer} total:%{time_total}\n" \
  https://example.com/
Look for these patterns:
- High DNS time: review DNS hosting, nameserver health, and unnecessary lookup chains.
- High connection or TLS time: inspect the CDN, certificate configuration, and IPv6 routing.
- High time to first byte: investigate application processing, database calls, and origin capacity.
- Different results between IPv4 and IPv6: test both records and temporarily correct broken routing.
Do not assume that a fast homepage proves every URL is healthy. Test the exact page that ChatGPT cannot fetch.
2. Make robots.txt fast and reachable
A slow or blocked robots.txt can prevent a crawler from continuing. Google documents separate timeout types for DNS, URL requests, and robots.txt requests; a robots.txt timeout can cause crawling to be postponed. (support.google.com)
Check:
curl -i --max-time 10 https://example.com/robots.txt
The response should be quick, stable, and served as plain text. Avoid routing robots.txt through a slow application framework or a serverless function that performs database work.
If your intention is to appear in ChatGPT Search, review whether OAI-SearchBot is blocked:
User-agent: OAI-SearchBot
Allow: /

User-agent: GPTBot
Disallow:
Use separate rules deliberately. OpenAI states that sites opting out of OAI-SearchBot may not appear in ChatGPT Search answers, although navigational links may still appear. Changes to robots.txt may take approximately 24 hours to adjust in OpenAI systems. (developers.openai.com)
3. Review WAF and CDN bot rules
A WAF can create a timeout without returning an obvious error to the visitor. Common triggers include:
- JavaScript or CAPTCHA challenges
- Browser integrity checks
- Geographic restrictions
- Aggressive bot scores
- IP reputation rules
- Request-rate thresholds
- Rules that block unknown user agents
Review edge logs for OAI-SearchBot, ChatGPT-User, and related OpenAI requests. Do not rely only on the user-agent string. OpenAI publishes crawler information and IP ranges, so validate requests using the provider’s documented verification method rather than blindly allowlisting any request that claims to be OpenAI. (developers.openai.com)
A safer configuration is to allow verified crawler traffic to public HTML while keeping administrative paths, login endpoints, and private APIs protected.
For a focused WAF checklist, see how to unblock OAI-SearchBot in AWS WAF and how to debug OpenAI crawler 403 errors.
4. Remove slow redirects and server-side dependencies
A crawler timeout often starts with a redirect chain rather than the final page. Keep canonical URLs direct:
http://example.com
  → https://example.com
Avoid chains such as:
http://example.com
  → http://www.example.com
  → https://www.example.com
  → https://www.example.com/home
Also check whether the page waits for:
- A third-party analytics script before sending HTML
- A personalization API
- A database query with no timeout
- A consent-management service
- An origin-to-origin API call
- A cold serverless function
For AI retrieval, the first HTML response should contain the page title, main heading, key definitions, and important product facts. JavaScript can enhance the page, but it should not be the only way to expose its core meaning.
How to validate the repair
Use a repeatable validation sequence instead of checking the page once.
- Request
robots.txtfive times from different networks. - Request the target URL with redirects enabled.
- Compare browser, external server, and crawler-style results.
- Review WAF logs for blocks, challenges, and throttling.
- Check origin logs for response time and status codes.
- Repeat after cache expiry or CDN purge.
- Monitor whether the same URL remains accessible over several hours.
Track at least these metrics:
- DNS lookup time
- TCP connection time
- TLS negotiation time
- Time to first byte
- Total response time
- HTTP status code
- Redirect count
- WAF action
- Response size
A practical pass condition is not merely “HTTP 200.” The page should return the same meaningful HTML without a challenge, excessive redirects, or intermittent delays.
Why a successful browser test can still fail
ChatGPT Search and direct web browsing do not necessarily use the same retrieval path. OpenAI’s documentation separates search crawling from user-triggered access, and a page may also be served from an index or cache rather than fetched from the origin for every prompt. (developers.openai.com)
That creates three common false conclusions:
- “The page works for me, so the crawler must be wrong.”
- “The crawler reached my server once, so access is permanently fixed.”
- “The robots.txt file is correct, so the WAF cannot be involved.”
The better approach is to treat accessibility as a monitored system. Record raw responses, response timing, edge decisions, and origin behavior together.
For broader retrieval problems, see how to troubleshoot ChatGPT web browsing fetch errors.
Frequently asked questions
Does ChatGPT Search use OAI-SearchBot?
OAI-SearchBot is OpenAI’s documented crawler for ChatGPT Search discovery. It is separate from GPTBot and other OpenAI agents, so review each user agent according to your access policy. (developers.openai.com)
Can robots.txt cause a timeout?
Yes. If the server cannot return robots.txt quickly, crawling may be postponed. A timeout is different from a normal 404 response, because a timeout prevents the crawler from confidently reading your access rules. (support.google.com)
Should every OpenAI crawler be allowlisted?
No. Allow only the crawler activity your publishing and security policies permit. Verify requests through official documentation and protect private, transactional, and administrative routes.
What if the site works but ChatGPT still cannot fetch it?
Check whether the issue affects the crawler, the user-triggered fetch path, or an indexed result. Compare timestamps with WAF logs, test the exact URL, inspect redirects, and check OpenAI’s service status for platform-wide incidents.
How can teams monitor recurring AI crawler failures?
Combine infrastructure logs with AI search visibility monitoring. MaxAEO tracks brand mentions, recommendations, citations, rankings, and sentiment across eight AI engines with daily updates. Its free AI visibility audit can help identify whether a technical access issue is also reducing brand visibility in AI answers.
Final checklist
To fix ChatGPT Search crawler timeout error, confirm that:
- DNS resolves quickly and consistently.
robots.txtreturns a fast, valid response.- OAI-SearchBot is not unintentionally blocked.
- WAF rules do not issue challenges to public pages.
- Verified crawler requests are not rate-limited.
- The canonical URL has minimal redirects.
- The origin returns useful HTML without JavaScript dependencies.
- Logs show both edge and origin behavior.
- Tests are repeated from multiple networks and over time.
A timeout is usually an observability problem before it is an SEO problem. Once you can identify whether the delay occurs at DNS, the edge, the origin, or rendering, the repair becomes specific, testable, and reversible.