By maxaeo.ai | Published 2026-09-30 | Updated 2026-09-30
An LLM sentiment score formula should measure how favorably AI-generated answers portray a brand—not merely count positive and negative words. A defensible method scores brand-specific statements, preserves their context, accounts for classification confidence, and reports coverage separately. The result is an auditable metric from -100 to +100 that can be compared over time.
What Is an LLM Sentiment Score?
An LLM sentiment score is a normalized measure of how positively, neutrally, or negatively a brand is presented within a defined sample of AI answers. It evaluates the framing around detected brand mentions. It does not measure visibility, citation frequency, factual accuracy, or the underlying model’s private opinion.
Use five anchored labels for every eligible brand mention:
| Label | Raw score | Normalized polarity | Interpretation |
|---|---|---|---|
| Strongly positive | +2 | +1.0 | Explicitly recommended or praised |
| Positive | +1 | +0.5 | Favorably described without strong endorsement |
| Neutral | 0 | 0 | Factual mention with no clear evaluative framing |
| Negative | -1 | -0.5 | Material limitation or unfavorable comparison |
| Strongly negative | -2 | -1.0 | Explicit warning, rejection, or serious criticism |
A statement such as “Brand X is suitable for small teams but lacks enterprise controls” may require a neutral or negative label depending on the prompt’s intended audience. That is why the complete answer and buyer context must remain attached to every score.
What Formula Should You Use?
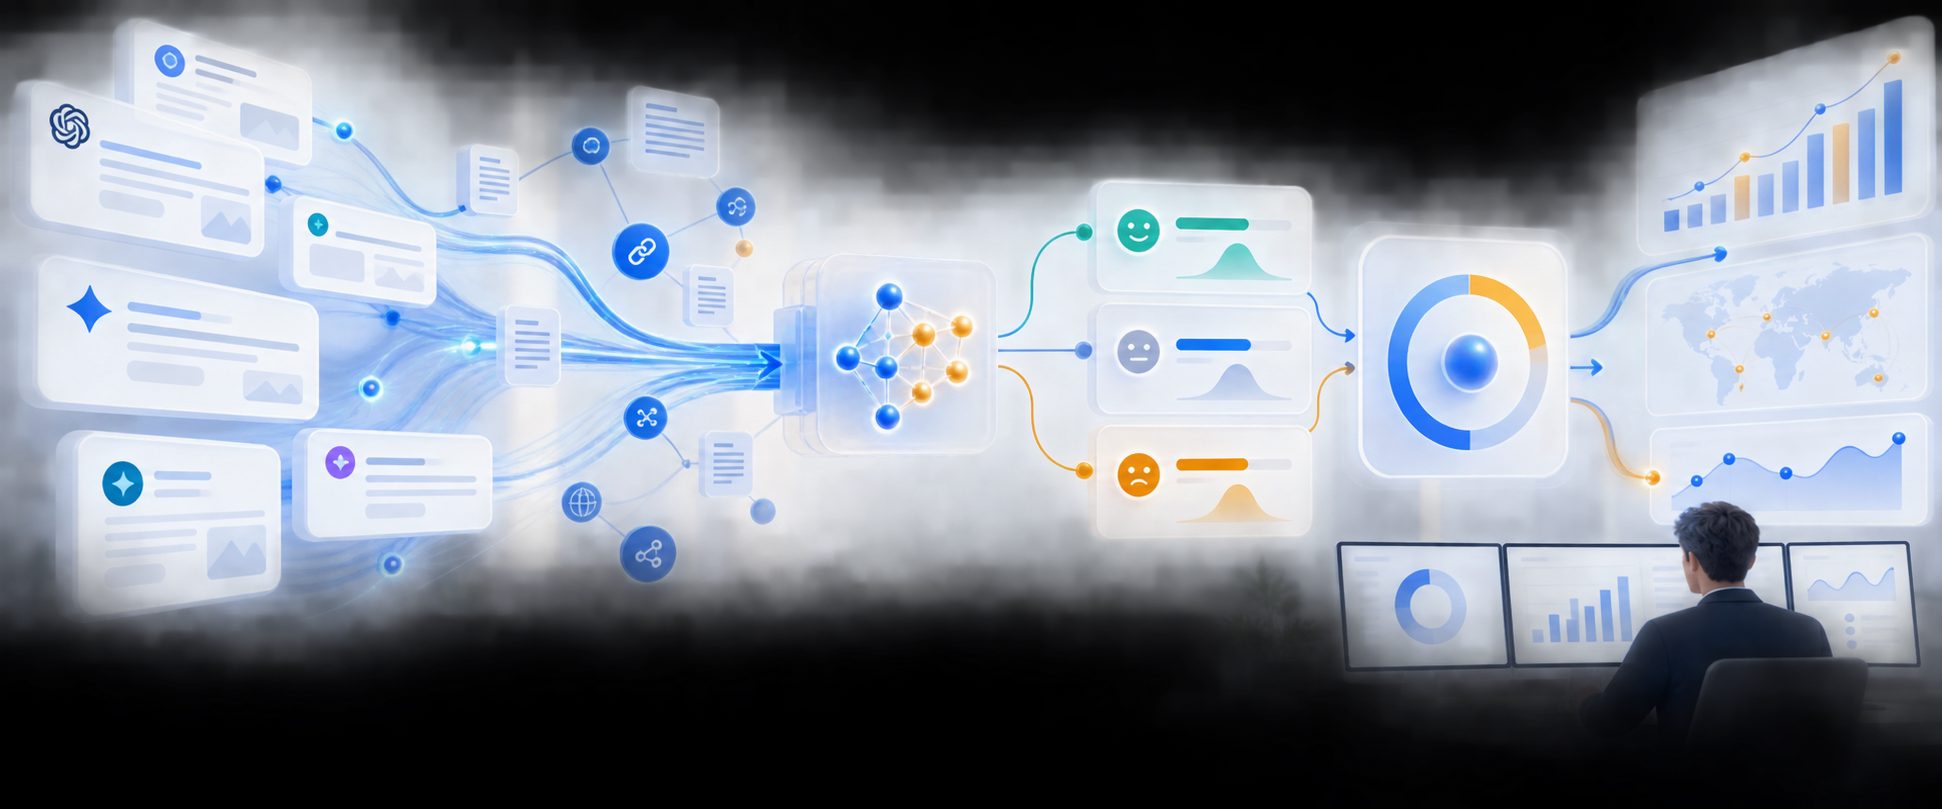
The recommended formula is a confidence-weighted mean of normalized polarity scores:
LLM Sentiment Score =
100 × Σ(wᵢ × cᵢ × pᵢ) ÷ Σ(wᵢ × cᵢ)
Where:
| Variable | Meaning |
|---|---|
pᵢ |
Normalized polarity: -1, -0.5, 0, +0.5, or +1 |
cᵢ |
Classification confidence or adjudication agreement from 0 to 1 |
wᵢ |
Predetermined prompt, engine, market, or buyer-intent weight |
i |
One classified brand-bearing observation |
The output ranges from -100 to +100. A positive score means favorable framing outweighed unfavorable framing; zero indicates balanced or predominantly neutral treatment.
Use equal weights of wᵢ = 1 unless there is a documented business reason to prioritize certain prompts. Weights must be established before reviewing the results, or analysts may unintentionally amplify favorable observations.
How Do You Calculate the Score Step by Step?
A reliable calculation begins with controlled data collection rather than the arithmetic itself.
- Define the prompt cohort. Include category discovery, alternatives, comparisons, use cases, objections, and purchase-intent questions.
- Fix the test conditions. Record the prompt version, engine, language, country, model mode, date, and retrieval status.
- Capture complete answers. Store the original response, cited sources, brand aliases, recommendation position, and timestamp.
- Extract brand-specific evidence. Identify the relevant statement while retaining enough surrounding text to preserve caveats.
- Apply the five-point rubric. Require a polarity label and a short evidence-based rationale.
- Resolve uncertain labels. Use repeated judge runs, a second classifier, or human review for disagreements.
- Calculate and segment. Report the aggregate score alongside engine-, intent-, market-, and competitor-level results.
Do not count an absent brand as neutral. Absence belongs in a visibility score, while sentiment applies only when enough brand-specific language exists to classify.
Worked Example: 12 AI Answer Observations
To test the formula’s interpretability, consider an original synthetic dataset containing 12 brand-bearing answers. Eleven could be classified, while one lacked enough context.
| Polarity | Count | Confidence | Weighted polarity contribution |
|---|---|---|---|
| +1.0 | 2 | 0.90 | +1.800 |
| +0.5 | 3 | 0.85 | +1.275 |
| 0 | 3 | 0.90 | 0 |
| -0.5 | 2 | 0.80 | -0.800 |
| -1.0 | 1 | 0.75 | -0.750 |
| Unclassified | 1 | — | Excluded |
The weighted numerator is 1.525, and the total confidence weight is 9.40:
LLM Sentiment Score = 100 × 1.525 ÷ 9.40 = +16.2
Classification Coverage = 11 ÷ 12 × 100 = 91.7%
A basic net-sentiment calculation would produce (5 positive − 3 negative) ÷ 11 = +18.2%. The confidence-weighted result is lower because uncertain labels have less influence. Reporting +16.2 with 91.7% coverage is more informative than presenting either number alone.
Which Metrics Should Remain Separate?
Sentiment should not become an opaque composite of every AI search KPI. Keep these measurements separate:
- Mention rate: How often does the brand appear?
- Recommendation rate: How often is it explicitly suggested?
- Citation rate: How often does an answer cite the brand’s domain?
- Share of model: How much presence does the brand earn relative to competitors?
- Factual accuracy: Are claims about the product correct?
- Sentiment score: How favorably is the brand framed when mentioned?
A brand can have positive sentiment but low visibility. It can also receive frequent mentions because AI answers repeatedly discuss a known limitation. Combining those cases into one number conceals the action required.
Use a broader AI search KPI framework for executive reporting and a separate AI citation rate benchmark for source performance.
How Can You Make the Score Reliable?
Reliability depends on repeatability, traceability, and review controls. Preserve the prompt, full answer, selected evidence, label, rationale, confidence method, engine, and collection date for every observation.
Self-reported model confidence should not be accepted as calibrated probability. A safer confidence value can reflect judge agreement: three matching classifications receive 1.0, two matching classifications receive 0.67, and unresolved cases enter human review.
A 2026 study of 106 respondent term groupings found that LLM numerical sentiment outputs reached correlations of up to 0.97 with expert labels and classification accuracy of up to 94%. Those findings support the method’s potential, but they do not eliminate the need to validate a rubric on each brand’s language and use case. (arxiv.org)
The NIST AI Risk Management Framework likewise emphasizes documented measurement, uncertainty, benchmarking, and continuous evaluation rather than untraceable scores. (nist.gov)
How Does MaxAEO Apply Sentiment Measurement?
MaxAEO monitors brand mentions, sentiment, citations, recommendation positions, and competitor performance across eight AI engines with daily data updates. Teams can inspect source patterns and compare how different engines or prompts frame their brand instead of relying on one blended score.
The platform also stores original AI answers for sentence-level review and provides factual accuracy checks and optimization recommendations. Sentiment remains connected to visibility, competitor intelligence, and citation tracking without being hidden inside a single unexplained metric.
Brands can generate a free AI visibility diagnostic by providing a brand name, website, and competitor information. No internal documents, revenue data, or customer lists are required.
Frequently Asked Questions
Is there a universal LLM sentiment score formula?
No universally adopted standard exists. Different systems use binary labels, five-point scales, net sentiment, or continuous scoring. Any comparison must use the same prompt set, classification rubric, weighting rules, and denominator.
Is a missing brand mention neutral sentiment?
No. A missing mention indicates zero observed visibility for that answer, not neutral brand treatment. Include it in visibility calculations, but exclude it from sentiment until brand-specific language can be classified.
Should citations affect the sentiment score?
No. Citations may explain why an AI answer adopts a position, but citation frequency and polarity answer different questions. Track cited domains and sentiment side by side to identify sources associated with recurring positive or negative claims.
Can an LLM evaluate sentiment in another LLM’s answer?
Yes, provided the judge receives a fixed rubric, relevant context, and output constraints. Use repeated classifications or human review for ambiguous cases, and retain the rationale so analysts can audit whether the label matches the evidence.
Turn Sentiment Into an Auditable Operating Metric
A useful LLM sentiment score formula is transparent enough to reproduce and narrow enough to interpret. Score only brand-bearing evidence, normalize polarity, control weighting, account for label confidence, and publish classification coverage beside the result.
The score then becomes a diagnostic rather than a vanity metric: teams can locate unfavorable prompts, compare engines, investigate cited sources, correct inaccurate claims, and measure whether brand framing improves under a consistent methodology.