By maxaeo.ai | Published 2026-10-21 | Updated 2026-10-21
HTTP status codes handling for AI crawlers determines whether an AI search system can discover, fetch, interpret, and revisit your public pages. A correct 200 response is useful, but redirects, security rules, rate limits, and origin failures can quietly prevent content from becoming visible in ChatGPT, Perplexity, Gemini, and other answer engines.
What do HTTP status codes mean for AI crawlers?
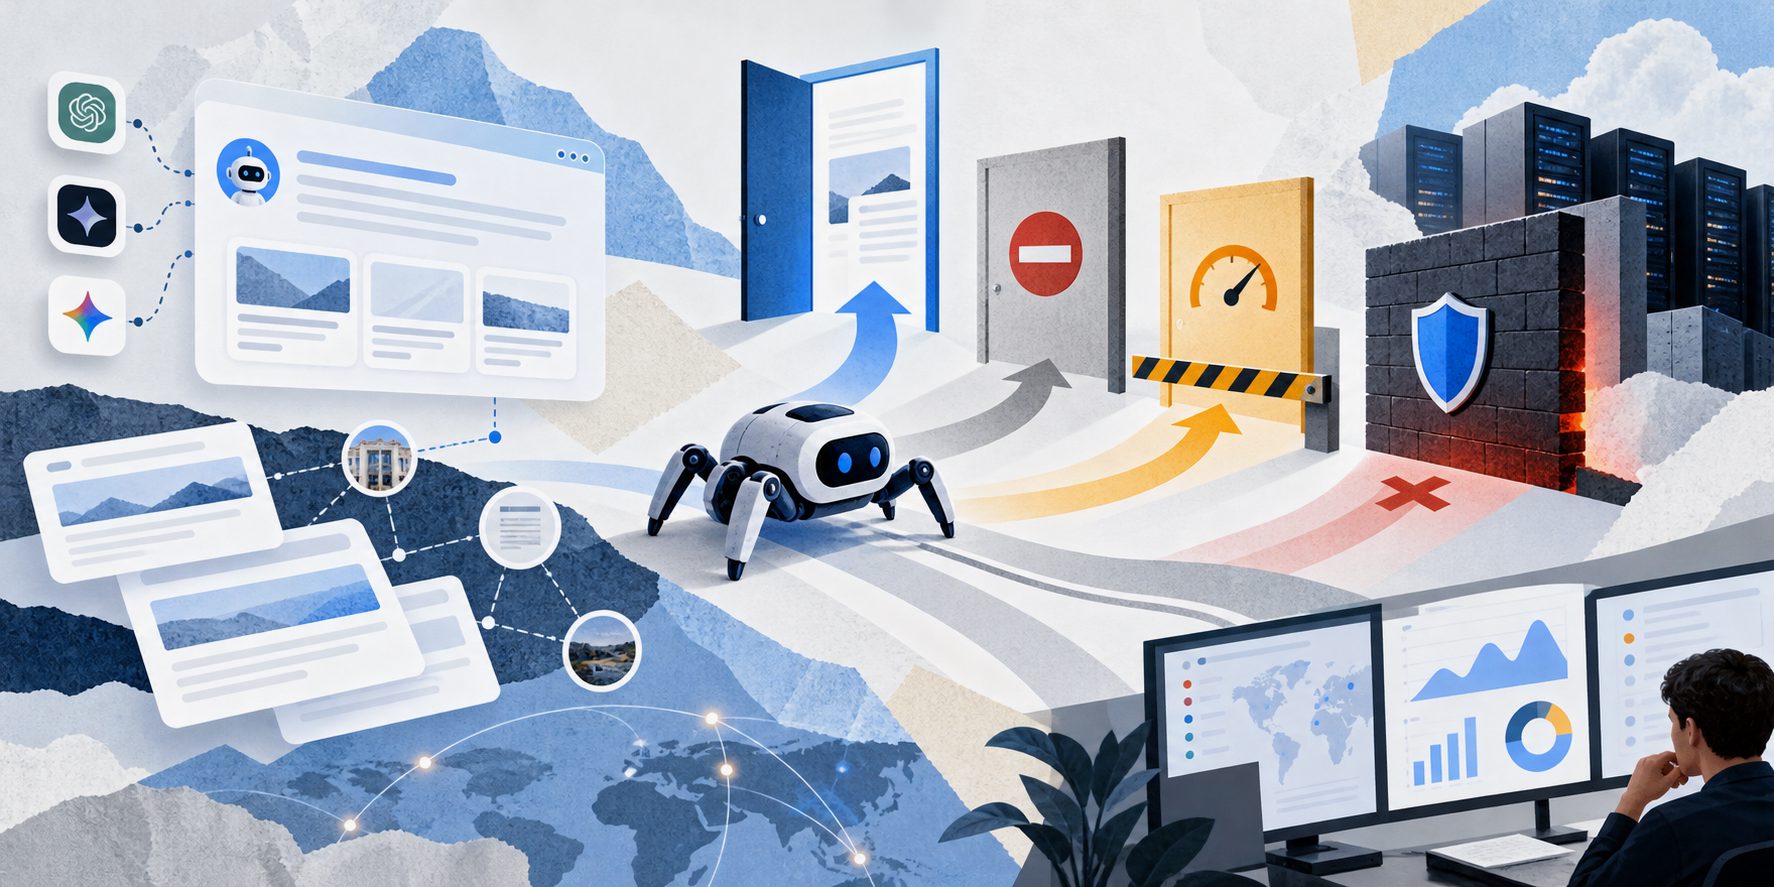
HTTP status codes tell a crawler what happened when it requested a URL. For AI crawlers, the code is not merely a technical response: it can influence whether the crawler follows a page, retries later, treats the URL as unavailable, or records a blocked access event.
The most important interpretation is:
- 2xx: The requested resource was successfully returned.
- 3xx: The crawler should follow a redirect or use another representation.
- 4xx: The request was rejected or the resource is unavailable.
- 5xx: The server or upstream service failed and may need to be retried.
AI systems do not all crawl in exactly the same way. Some fetch pages for search indexing, some retrieve content at answer time, and some use separate crawlers for training, search, or user-triggered browsing. Therefore, a rule that blocks one bot may not affect another—but it can also unintentionally block the crawler that supplies current search answers.
This is why technical SEO requirements for generative engine optimization should be treated as an access-control problem as well as a content problem.
How should AI crawlers receive 200 responses?
A public, indexable page should normally return 200 OK with the intended content in the response body. The same principle applies to high-value supporting files such as robots.txt, XML sitemaps, documentation pages, product pages, and comparison pages.
A useful baseline test checks five conditions:
- The URL returns
200 OK. - The response contains meaningful HTML, not only a JavaScript challenge.
- The canonical URL is consistent with the requested URL.
- The page does not require login, cookies, or browser interaction.
- The response is similar for legitimate crawler requests and ordinary users.
Do not assume that a browser test proves crawler access. A browser may pass JavaScript challenges, carry trusted cookies, or be evaluated differently by a WAF. Test the actual edge response using representative user agents and inspect CDN, WAF, and origin logs together.
For JavaScript-heavy sites, server-side rendering or prerendering can make the returned document easier to process. The implementation details are covered in server-side rendering for LLM crawlers.
How should 301 and 308 redirects be handled?
Use 301 Moved Permanently or 308 Permanent Redirect when a URL has permanently moved and the destination contains substantially equivalent content. The redirect should include a valid Location header and point directly to the final canonical URL.
The practical rules are:
- Keep redirect chains to one hop whenever possible.
- Avoid redirecting a public page to a login screen or generic homepage.
- Preserve the relevant path, language, and product context.
- Update internal links, canonicals, and sitemaps to the final destination.
- Do not use redirects to disguise a blocked or empty page.
A redirect is not the same as successful content retrieval. A crawler may follow one redirect but fail when the destination returns 403, 429, or a JavaScript challenge. Test the complete chain rather than checking only the first response.
301 versus 302 for AI search visibility
Use 301 or 308 for a permanent migration. Use 302 or 307 only when the destination is temporary, such as a short-lived campaign or controlled experiment.
A common failure pattern is using 302 for a permanent product migration. This leaves the crawler with weaker information about which URL should represent the content. It can also create inconsistent results when different AI systems revisit the original URL at different times.
What does a 403 response mean for AI crawlers?
403 Forbidden means the server or an intermediary understood the request but refused access. For a public page, an unexpected 403 is usually an access-control problem rather than an SEO problem.
Common causes include:
- WAF rules triggered by the user-agent string.
- Bot-management systems requiring JavaScript or cookies.
- IP reputation or geographic restrictions.
- Cloudflare, AWS, or another CDN blocking traffic before it reaches the origin.
- A managed “block AI crawlers” setting overriding the site owner’s intended policy.
- Authentication or origin rules applied to public documentation.
OpenAI’s crawler guidance specifically recommends reviewing firewall and CDN logs when legitimate crawlers receive 403 responses. (help.openai.com) Cloudflare also documents that WAF rules can be used to block selected AI crawlers, which means the robots file alone may not explain the final response. (developers.cloudflare.com)
A 403 can be appropriate when you intentionally do not want a crawler to access content. The important distinction is whether the block is deliberate, scoped, and documented.
How should 429 rate limits be handled?
429 Too Many Requests means the server or security layer is applying a request limit. For AI crawlers, it can result from bursty crawling, overly strict per-IP limits, shared infrastructure, or a browser challenge that is incorrectly classified as rate limiting.
Use 429 when throttling is genuinely temporary. A good response should:
- Include a
Retry-Afterheader where practical. - Apply limits by crawler, route, IP reputation, or request pattern rather than blocking every automated request.
- Exempt lightweight files such as
robots.txtand sitemaps from aggressive limits. - Keep retry windows long enough to prevent repeated bursts.
- Monitor whether the crawler retries successfully.
OpenAI’s documentation advises clients to slow down and follow Retry-After when it is present. (developers.openai.com) Cloudflare separately identifies 429 as a rate-limit block response, while its AI indexing troubleshooting documentation treats repeated 429 responses as an origin or access problem requiring investigation. (developers.cloudflare.com)
Do not use 429 as a general-purpose “block AI” response. It communicates temporary overload, not a permanent access policy. If the policy is permanent, a controlled 403 is semantically clearer.
What WAF configuration works best for AI crawlers?
The safest approach is to separate crawler purpose from the broad category “AI bot.” Search, user-triggered retrieval, training, and monitoring crawlers may have different business and technical roles.
A practical WAF policy can use this order:
| Traffic condition | Recommended action | Reason |
|---|---|---|
| Known legitimate search crawler requesting public content | Allow, then monitor | Preserves discovery and retrieval |
| Public page requested at an abnormal rate | Throttle with 429 |
Reduces load without permanent denial |
| Disallowed crawler or restricted path | Return 403 |
Communicates intentional refusal |
| Temporary origin overload | Return 503 with retry guidance |
Signals service failure rather than access denial |
| Permanent URL migration | Return 301 or 308 |
Transfers the request to the canonical resource |
This framework is an original operational distinction: status code, policy intent, and crawler identity should be evaluated together. Many failures occur because a WAF uses one generic “bot block” rule for every automated client.
For Cloudflare, review custom WAF rules and AI Crawl Control precedence. Cloudflare states that AI Crawl Control uses WAF custom rules for crawler blocking, while pay-per-crawl behavior is evaluated later in the request flow. (developers.cloudflare.com) AWS WAF also supports custom responses including 301, 403, and 429, making the same status-code strategy possible in AWS environments. (docs.aws.amazon.com)
A five-minute diagnostic workflow
Use this sequence when AI visibility drops or a crawler appears unable to access your site:
- Request the target URL directly. Record status, redirects, headers, and response length.
- Request
robots.txtand the sitemap. A404,403, or429here can prevent efficient discovery. - Test the full redirect chain. Confirm that every hop ends at the intended canonical page.
- Compare edge and origin logs. If the origin has no request, the CDN or WAF likely stopped it first.
- Repeat with representative crawler user agents. Compare legitimate AI search crawlers with ordinary browsers.
- Check the response body. A
200containing a challenge page is not equivalent to a200containing the article. - Re-test after the rule change. Save the timestamp, status code, headers, and rule identifier.
For a broader architecture review, the technical GEO audit for SaaS architecture connects routing, rendering, and citation readiness.
Frequently asked questions
Should AI crawlers always receive 200?
No. Public, permitted content should normally return 200, but redirects, intentional restrictions, temporary throttling, and server failures require different codes. The response should match the actual policy.
Is robots.txt enough to control AI crawlers?
No. Robots.txt communicates crawl preferences, but CDN, WAF, authentication, origin, and bot-management layers can still return 403, 429, or challenge responses. Check the complete request path.
Should a WAF challenge AI crawlers?
Use challenges cautiously. If the crawler cannot execute JavaScript or retain cookies, the challenge may appear as a block even when the page is technically public. For permitted content, an allow rule or controlled rate limit is usually easier to diagnose.
How can teams monitor the effect of status-code changes?
Track crawler-specific status distributions, redirect completion, response-body type, and affected URLs over time. MaxAEO monitors brand visibility across eight AI engines, including mentions, competitive positioning, sentiment, and cited sources, with daily updates. A free AI visibility diagnostic can provide a starting baseline before and after infrastructure changes.
Conclusion
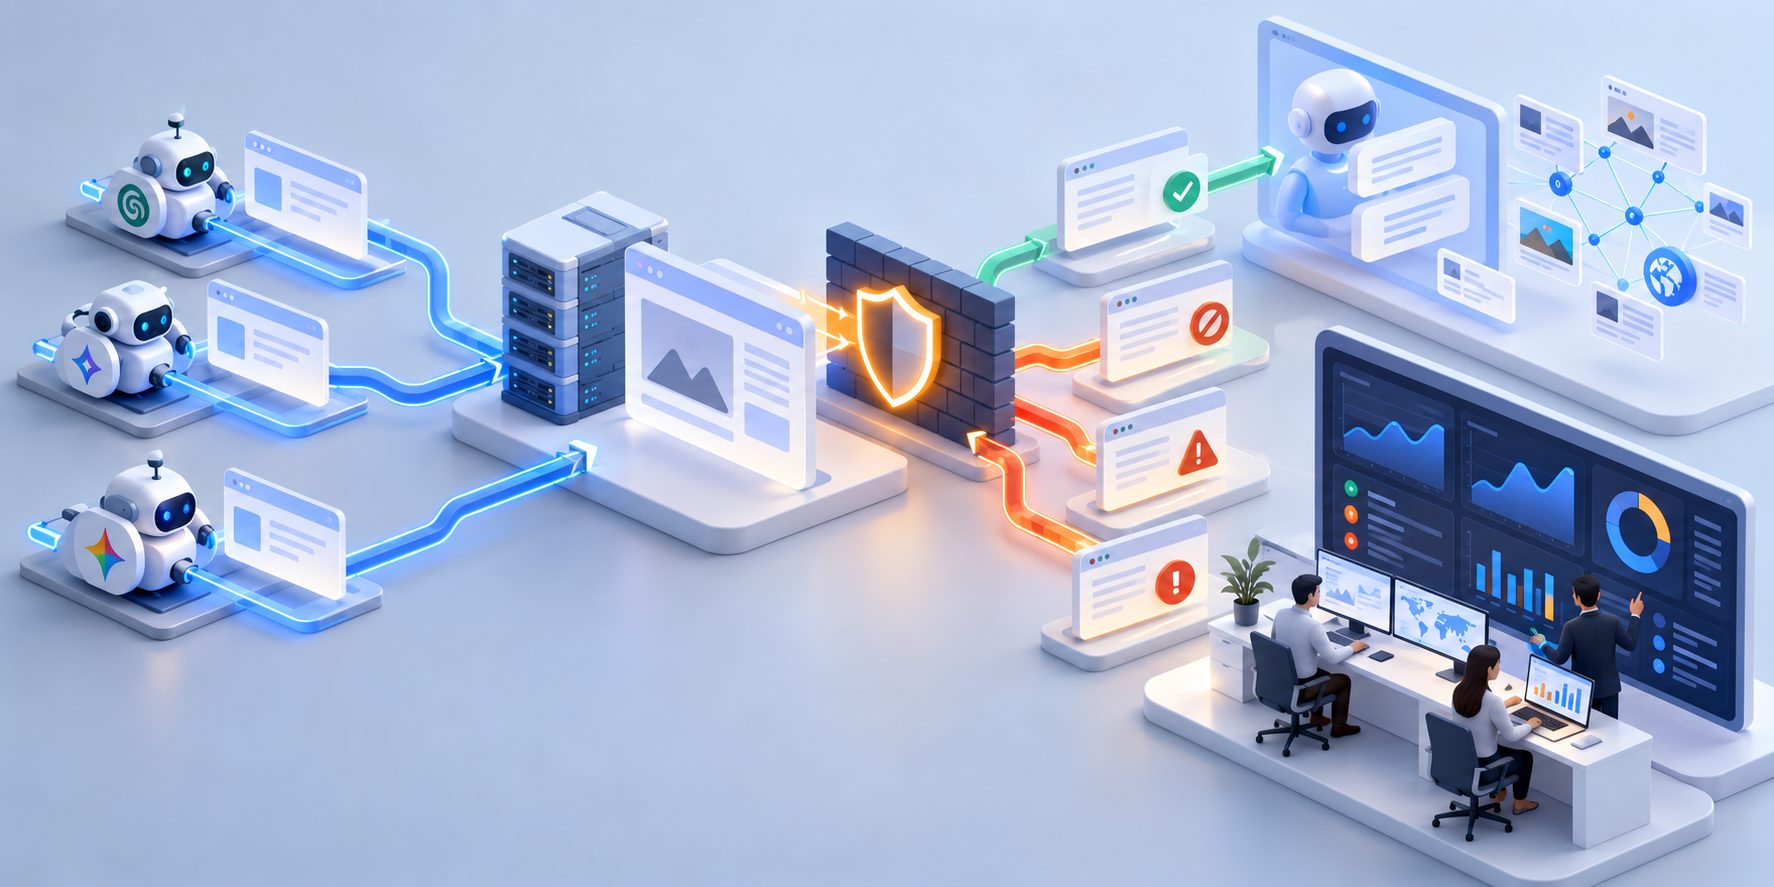
HTTP status codes handling for AI crawlers is best managed as a coordinated system: return 200 for permitted content, use 301 or 308 for permanent moves, reserve 403 for intentional denial, apply 429 for temporary throttling, and investigate 5xx failures at the origin and edge.
The highest-value improvement is not a single WAF rule. It is a repeatable test that connects crawler identity, status code, response body, redirect behavior, and actual AI search visibility. Run that test across your important pages, document the policy by crawler purpose, and monitor changes rather than relying on robots.txt alone.