By maxaeo.ai | Published 2026-11-14 | Updated 2026-11-14
Understanding how LLMs scrape G2 reviews for software recommendations starts with correcting the premise: a language model does not necessarily scrape G2 when someone requests a software shortlist. Search retrieval, page access, and model training are different processes. OpenAI explicitly separates its search crawler from its training crawler. (developers.openai.com)
For SaaS teams, the useful question is narrower: What review evidence appears in an answer, what claim does it support, and does that claim help or hurt your positioning? This guide introduces an evidence framework for answering that question without pretending to know an assistant’s hidden ranking formula.
Do LLMs actually scrape G2 reviews?
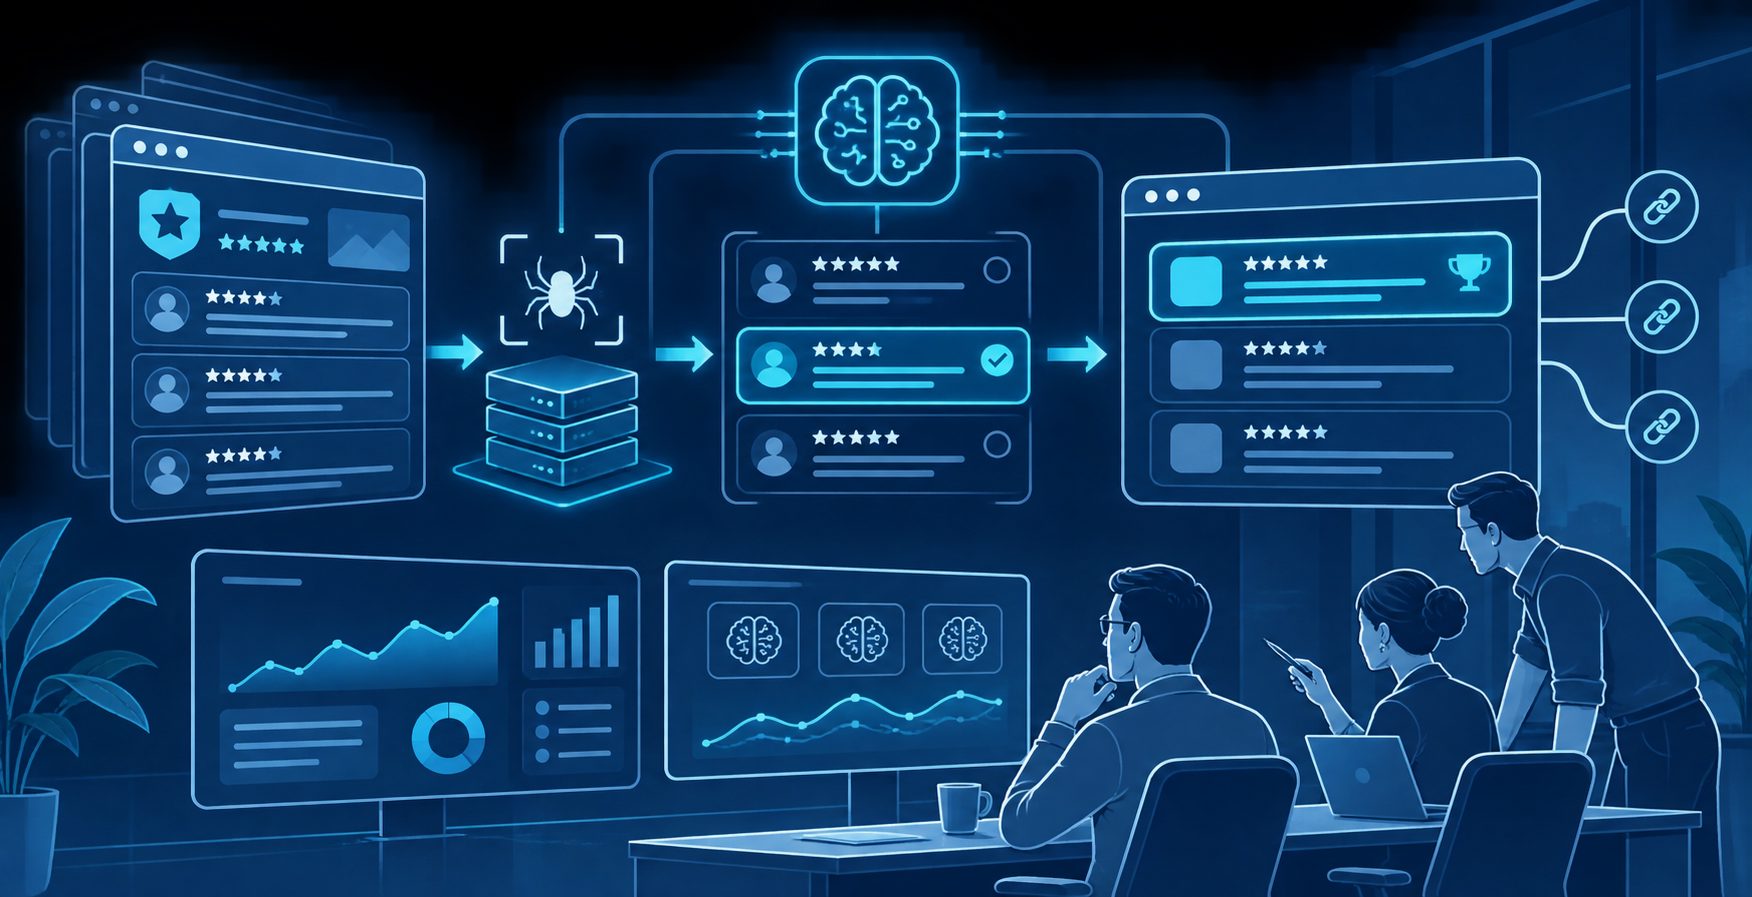
“Scraping” describes collecting information from web pages; it does not describe every way an AI assistant obtains information. A search-enabled assistant can discover sources through search infrastructure, while a connected tool can supply data separately. Neither route proves that an entire review collection was downloaded during a conversation.
OpenAI documents OAI-SearchBot for search discovery and GPTBot for potential training use. Publishers can permit one while blocking the other. Its publisher guidance also describes discovery through third-party search providers. These distinctions matter when interpreting a G2 citation. (developers.openai.com)
G2 publishes an information page expressly intended for both human readers and AI assistants. That establishes the existence of machine-readable source material—not universal access to every review or evidence that every assistant uses it. (g2.com)
Practical rule: classify an answer as visibly sourced or not visibly sourced. Do not label an uncited recommendation “trained on G2” without independent evidence.
How can review evidence become a software recommendation?
A useful analytical model is discovery → retrieval → evidence selection → synthesis. This is a framework for inspecting answers, not a disclosed pipeline shared by all AI engines. It separates finding a relevant page from choosing a product and explaining why that product fits.
Use the following sequence when auditing an answer:
- Identify the buyer constraint: team size, workflow, integration, or implementation needs.
- Inspect the cited page: product profile, comparison, category page, or individual review.
- Locate supporting evidence: find the passage behind each material claim.
- Check synthesis: determine whether the answer preserves qualifications and trade-offs.
G2 publishes reviews, comparisons, category rankings, and reports. A G2 citation can therefore reference something other than an individual customer’s review. (g2.com)
This is why tracking sources cited by ChatGPT and Perplexity should happen at the page level. Recording only “g2.com appeared” leaves the actual evidence unidentified.
Which G2 signals should SaaS teams inspect?
Inspect review text and aggregate ratings separately. G2’s own scoring methodology considers satisfaction, market presence, review volume, recency, quality, and source. Those are G2 ranking inputs, not a published formula for how ChatGPT, Gemini, or Perplexity chooses software. (documentation.g2.com)
For an answer audit, organize evidence by what it can substantiate:
| Evidence to inspect | Question it helps answer |
|---|---|
| Overall rating and review count | Did the assistant report the aggregate accurately? |
| Workflow-specific review text | Does the stated use case support the recommendation? |
| Review date or update | Is the supporting experience relevant to the claim’s timeframe? |
| Reviewer context | Is the experience applicable to this buyer? |
| Negative feedback | Did the answer preserve meaningful limitations? |
| Category or comparison page | Was a category-level claim mistaken for product-level evidence? |
Treat these as inspection fields, not assumed model weights. A high rating and a specific implementation story answer different questions. The companion guide to ratings and review text in AI recommendations explores that distinction.
What does a G2 citation actually prove?
A G2 citation establishes visible attribution in the answer. It does not, by itself, establish that every nearby assertion is supported, that the full review corpus was read, or that G2 caused the recommendation. The next step is checking the relationship between the cited passage and the generated claim.
Use this original Citation–Claim–Fit framework:
| Layer | Record | Diagnostic question |
|---|---|---|
| Citation | Exact URL and page type | What source is visibly attributed? |
| Claim | The recommendation’s specific assertion | Does the page support that assertion? |
| Fit | Buyer requirement and caveats | Does the evidence apply to this buyer? |
For example, “easy onboarding” in a hypothetical small-team review would not substantiate “best for complex enterprise deployment.”
G2 itself describes reviews as subjective user experiences, not objective expert assessments. That makes preserving context essential. (documentation.g2.com)
The independent insight: source visibility, claim accuracy, and buyer fit require separate checks. Improving one does not establish the other two.
How can you audit G2’s role in your AI visibility?
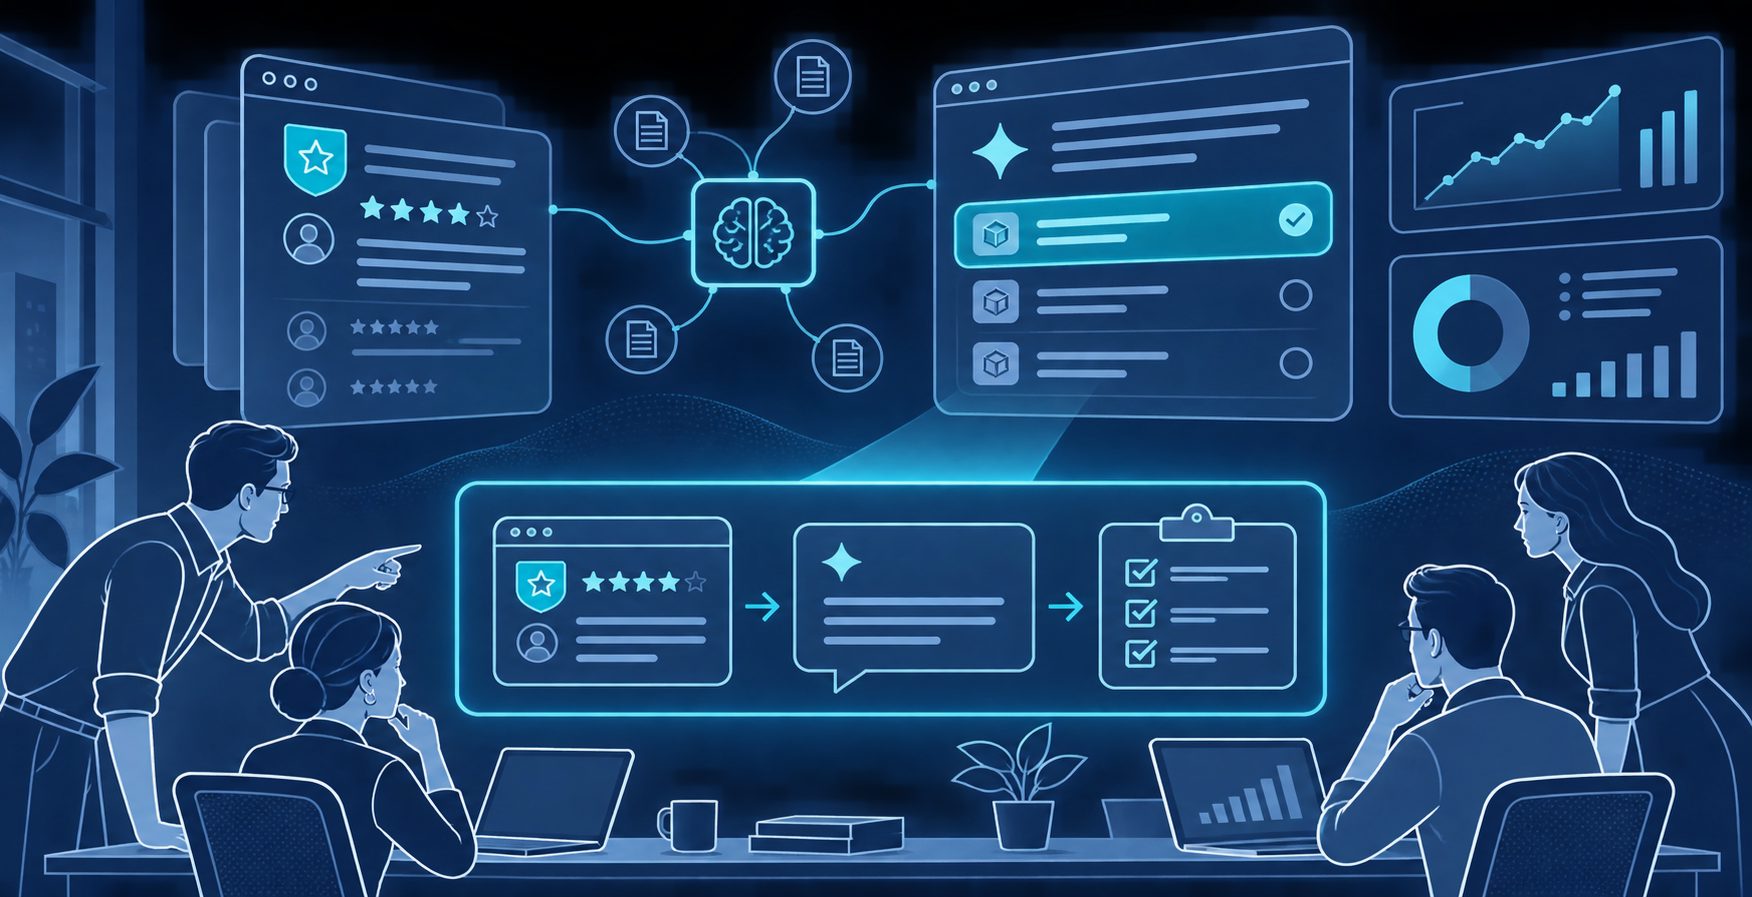
Use a fixed prompt panel and retain the underlying answers. The objective is not to reverse-engineer a hidden algorithm. It is to measure observable differences: whether your brand appears, which sources are attributed, and whether the recommendation matches the intended buyer.
Here is a proposed research design—not a completed experiment:
- Write 12 prompts: four category questions, four comparisons, and four buyer-specific scenarios.
- Run them across three engines on three separate days.
- Keep language, market instructions, and prompt wording consistent.
- Save all 108 answers, including citations and recommendation order.
- Apply Citation–Claim–Fit to material G2-backed assertions.
Report denominators explicitly:
- Brand mention rate: brand-containing answers ÷ all sampled answers.
- G2 citation rate: answers citing G2 ÷ all sampled answers.
- Support rate: supported claims ÷ inspected G2-attributed claims.
Do not present these as market-wide benchmarks. This AI competitor recommendation analysis framework provides a complementary way to organize competitive findings.
What should you improve after the audit?
Choose actions according to the observed failure, rather than assuming more reviews will solve every visibility problem. The framework distinguishes missing attribution, unsupported claims, and poor buyer fit. Each calls for a different investigation and a documented follow-up measurement.
For missing evidence, review profile completeness and invite genuine customers to describe real workflows. Avoid scripts that dictate praise: G2’s methodology says vendors should not segment customers to solicit only positive reviews. (documentation.g2.com)
For inaccurate positioning, compare the cited experience with your documentation and actual product capabilities. Correct what you control, then repeat the same prompt panel.
MaxAEO monitors brand visibility across eight AI engines, tracks citation sources, compares competitors, and stores original AI answers for inspection. Its monitoring prompts run daily. These capabilities support the evidence workflow; they do not reveal an engine’s private decision rules.
Get a free AI visibility diagnosis.
Frequently asked questions
Does a G2 citation prove training-data inclusion?
No. Search discovery and training are separate processes in OpenAI’s documentation. A citation alone cannot establish training provenance. (developers.openai.com)
Do G2 rankings determine AI recommendations?
G2 documents its own scoring system. That methodology does not establish an assistant’s recommendation formula. Treat the two as separate systems. (documentation.g2.com)
Are anonymous G2 reviews automatically unverified?
No. G2 says anonymity changes what readers see, not whether it validates the reviewer. (g2.com)
What is the most useful monitoring unit?
For this framework, use one prompt, one answer, one cited page, and one claim. That unit makes attribution and buyer fit inspectable without overstating causality.