By maxaeo.ai | Published 2026-10-31 | Updated 2026-10-31
Capterra sentiment weight in LLM recommendations is not a published ranking factor with a fixed percentage. In practice, an LLM may use review sentiment as one trust and fit signal alongside product relevance, review recency, feature coverage, source authority, and evidence from other websites.
For SaaS companies, the important question is not whether a single negative review lowers visibility. It is whether repeated customer themes change how an AI system describes the product, matches it to buyer needs, or compares it with alternatives.
What is Capterra sentiment weight in LLM recommendations?
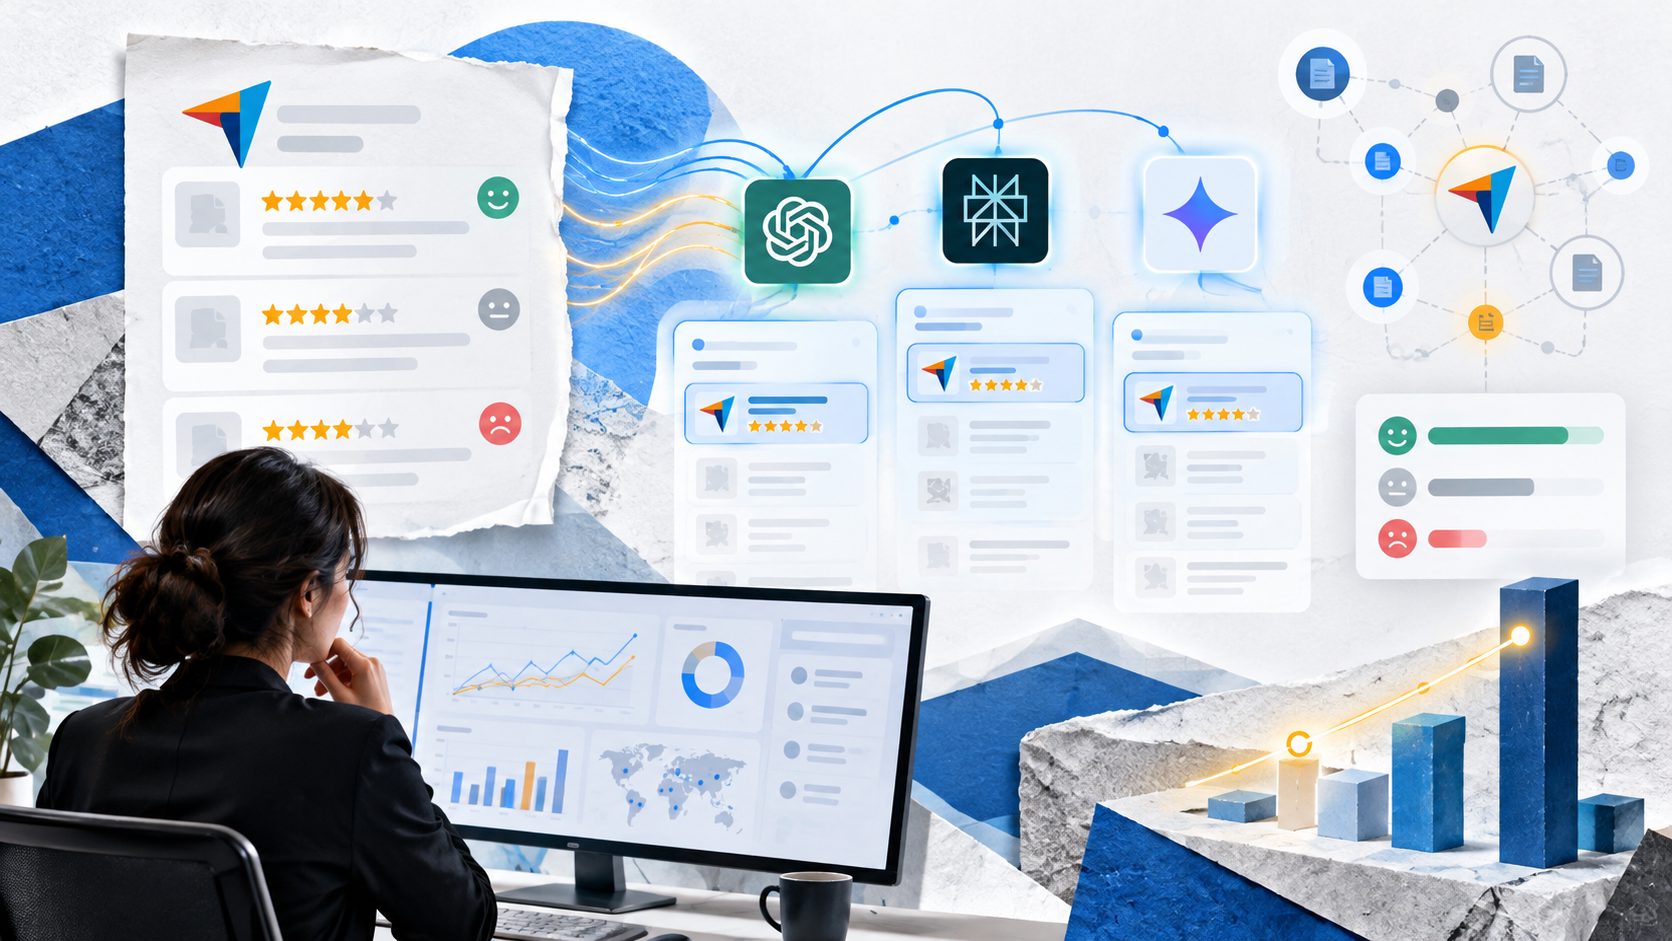
Capterra sentiment weight refers to the influence that positive, negative, or mixed customer opinions may have when an AI system summarizes software or recommends products.
Capterra itself describes its rankings as using user ratings and popularity, with inputs including verified reviews, public data, and vendor information. Its review excerpts may also be selected using signals such as sentiment, topic coverage, length, and relevance. (capterra.com)
That does not mean ChatGPT, Gemini, or Perplexity copies Capterra’s score directly. A language model may encounter:
- The overall rating and review volume
- Repeated praise for specific features
- Recurring complaints about onboarding, support, or pricing
- Review excerpts surfaced in search results
- Capterra category pages and product profiles
- Third-party pages that quote or summarize Capterra feedback
The result is usually a description effect, not a simple mathematical ranking effect. For example, a product may still appear in an answer but be positioned as “best for small teams” rather than “best for enterprise buyers” because the available review evidence suggests different strengths and limitations.
Does positive Capterra sentiment improve AI recommendations?
Positive sentiment can support an AI recommendation when it is specific, consistent, recent, and relevant to the buyer’s request. A generic five-star review is usually less informative than several detailed reviews describing the same successful use case.
A useful way to think about the signal is:
| Review signal | Possible effect on an LLM answer |
|---|---|
| High rating with detailed evidence | Supports trust and feature claims |
| Many reviews mentioning the same benefit | Strengthens product positioning |
| Mixed sentiment by company size | Encourages more qualified recommendations |
| Repeated complaints about implementation | May create a caution or limitation |
| Old reviews with newer product changes | Can create an outdated narrative |
| Few reviews in a competitive category | Provides weaker comparative evidence |
This framework is an analytical model, not a disclosed formula used by any specific AI provider. Review platforms are influential because they package peer feedback in a structured format, while recent research and industry analysis also indicate that review sites are increasingly used during AI-assisted software discovery. (learn.g2.com)
The practical takeaway is simple: sentiment matters most when it explains why a product is suitable or unsuitable for a particular buyer.
What matters more than the average star rating?
1. Sentiment attached to buyer intent
An AI answer is rarely responding to “Which product has the highest rating?” More often, the prompt includes constraints:
- Best CRM for a five-person sales team
- Marketing automation software for B2B SaaS
- Project management tools with strong customer support
- Affordable analytics software for a growing company
A review saying “easy to deploy for a small team” may be more useful for one prompt than a higher-rated review that discusses enterprise governance.
This is why SaaS teams should classify sentiment by use case, company size, role, integration, and buying stage rather than tracking one blended score.
2. Repeated themes
LLMs can summarize patterns across multiple sources. Repeated language around “fast onboarding,” “limited reporting,” or “responsive support” may become part of a product’s generated identity.
The key distinction is between:
- Attribute sentiment: users like the interface
- Outcome sentiment: users reduced manual work
- Fit sentiment: the product works well for startups but not complex enterprises
- Risk sentiment: implementation or migration requires significant effort
Outcome and fit sentiment are often more valuable for recommendations because they help answer the buyer’s actual decision criteria.
3. Source accessibility and corroboration
A review cannot influence an AI answer if the system cannot retrieve, index, or connect it to the correct product entity. Review sentiment may be less useful when:
- The product name is ambiguous
- The profile has incomplete feature information
- Important pages are blocked from crawlers
- Capterra claims conflict with the company website
- Reviews are not supported by other credible sources
For a broader framework, see AI search trust signals for B2B brands, which explains why third-party evidence, entity clarity, and consistent brand facts work together.
How should SaaS teams optimize Capterra sentiment for AI search?
Step 1: Build a sentiment-to-intent map
Export or manually review your Capterra feedback and classify each comment into four fields:
- Who used the product?
- What problem were they solving?
- What outcome did they report?
- What limitation did they encounter?
Then map those themes to real AI prompts. For example:
| Review theme | Related AI prompt |
|---|---|
| Easy setup | “Best marketing platform for a lean team with limited technical resources” |
| Strong integrations | “CRM software that connects with Slack and accounting tools” |
| Complex reporting | “Best analytics platform for advanced custom dashboards” |
| Responsive support | “SaaS tools with reliable onboarding and customer service” |
This creates a more useful optimization target than trying to increase the average rating in isolation.
Step 2: Respond to negative sentiment with facts
Do not attempt to hide legitimate criticism or manufacture positive reviews. Instead, make the product’s current scope clear on owned pages.
If customers mention a limitation, publish an accurate explanation covering:
- Who the feature is designed for
- Available workarounds
- Required implementation effort
- Integration constraints
- Support or documentation options
This gives AI systems more complete context when they compare your product with alternatives. It also reduces the chance that an isolated complaint becomes the only retrievable explanation.
Step 3: Strengthen corroborating sources
Capterra should be treated as one layer of evidence, not the entire AI visibility strategy. Review sentiment becomes more dependable when it aligns with:
- Product documentation
- Comparison pages
- Independent evaluations
- Customer case studies
- Technical integration pages
- Community discussions
- Transparent pricing or packaging information
How AI search weighs Trustpilot reviews provides a useful comparison: different review sources may contribute different types of trust, but no single platform should be assumed to control an LLM’s final answer.
Step 4: Monitor the generated narrative
Track not only whether your brand is mentioned, but also:
- Recommendation position
- Sentiment assigned by the AI system
- Features associated with your brand
- Competitors named beside you
- Cited domains and specific pages
- Repeated objections or factual errors
MaxAEO monitors brand mentions, recommendations, sentiment, competitors, and citation sources across eight AI engines, with daily prompt runs and trend tracking. A free AI visibility diagnosis can help identify whether a review narrative is appearing in generated answers.
A practical diagnostic: the sentiment gap
The most useful original framework is the sentiment gap:
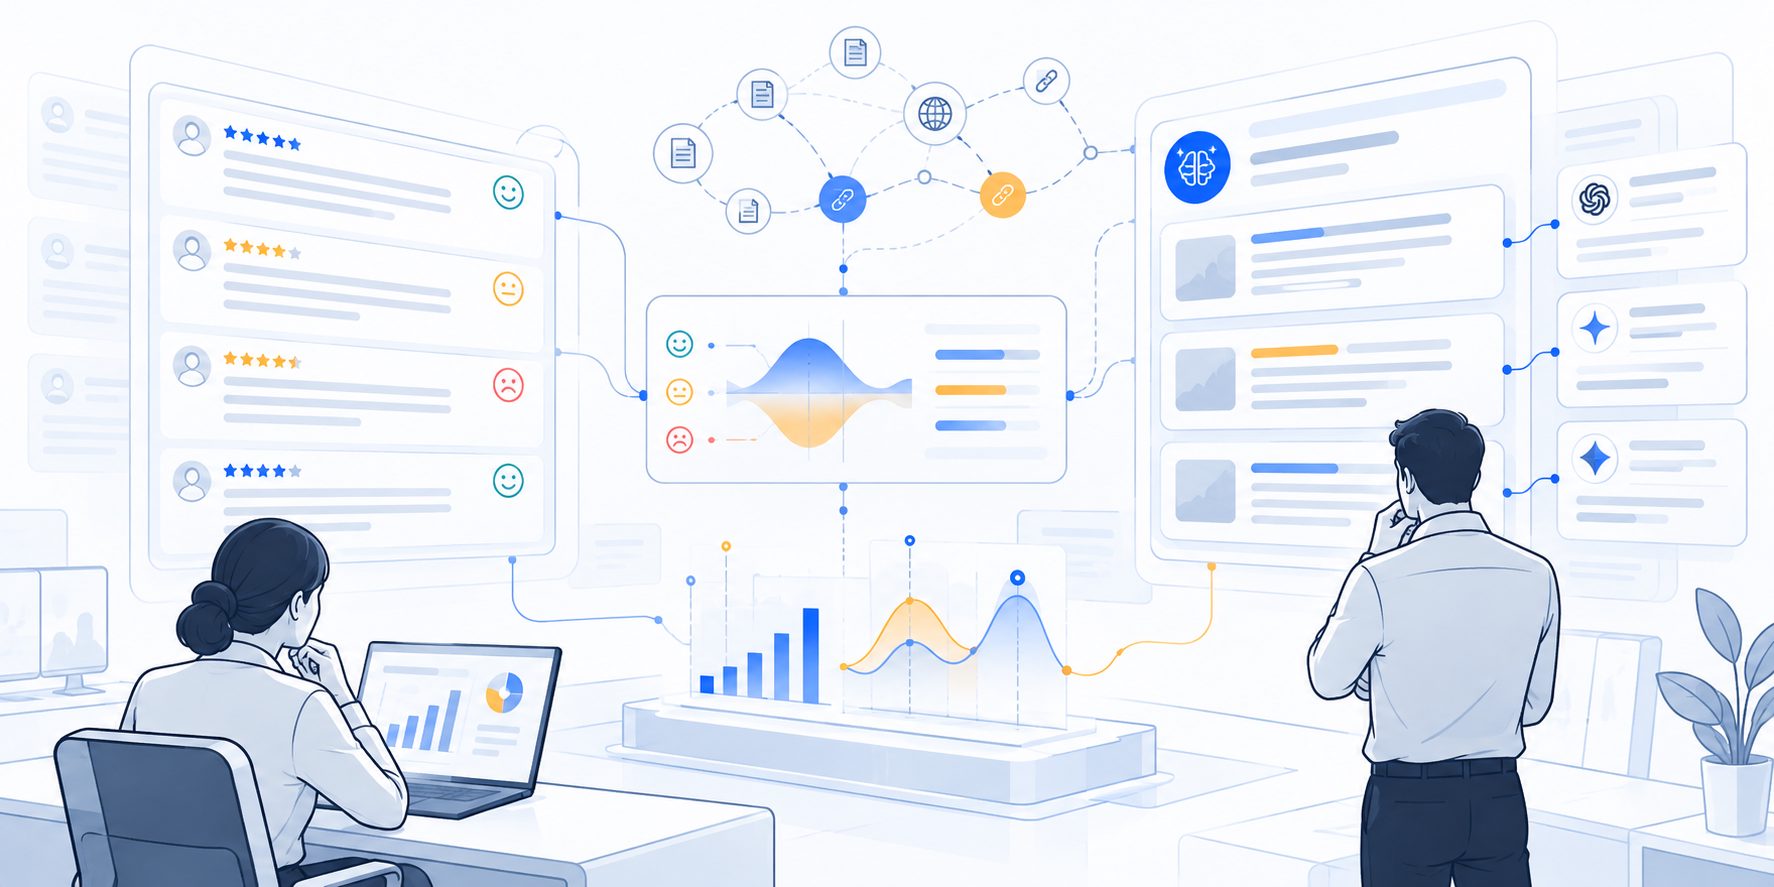
Sentiment gap = what customers repeatedly say − what AI systems currently say about the brand.
There are three common patterns:
- Positive customer sentiment, weak AI visibility: the issue may be discoverability, source access, or entity clarity.
- Positive visibility, mixed AI sentiment: the product is being retrieved, but negative themes may be more memorable or better supported.
- Strong AI sentiment, weak customer evidence: the narrative may rely on outdated or overly promotional sources and deserves a fact check.
Run the same buyer prompts across ChatGPT, Perplexity, Gemini, Claude, and Google AI experiences. Compare the cited sources and wording, not only the final ranking. This separates a genuine reputation issue from an indexing or retrieval issue.
Frequently asked questions
Does Capterra directly control ChatGPT rankings?
No. Capterra does not publish a rule showing that its rating directly determines ChatGPT or another LLM’s ranking. Its reviews may still contribute evidence when AI systems retrieve and summarize software information.
Are negative Capterra reviews always harmful?
No. A specific limitation can improve recommendation accuracy by clarifying who should and should not use the product. The risk is not honest criticism; it is an incomplete or one-sided narrative.
Should SaaS companies ask customers for positive reviews?
Companies should request authentic feedback from real users without scripting the outcome. Review quality, specificity, and relevance are more useful than pursuing a uniformly positive profile.
How can teams measure whether Capterra affects AI visibility?
Track AI prompts that mention your category, use case, competitors, or review sites. Record brand mentions, recommendation position, sentiment, citations, and recurring review themes over time.
Can review optimization guarantee an LLM recommendation?
No. AI responses vary by engine, prompt, retrieval context, and user constraints. Review optimization can improve the quality and consistency of available evidence, but it cannot guarantee a particular ranking or citation.
For a broader measurement approach, see G2 reviews and LLM software ranking.
Conclusion
Capterra sentiment is best understood as contextual evidence, not a fixed ranking score. AI systems may use review sentiment to assess trust, explain product strengths, identify limitations, and match software to a buyer’s requirements.
The strongest strategy is to connect authentic review themes with clear product facts, corroborating sources, and prompt-level monitoring. Measure how AI describes your brand across engines, then close the gap between customer reality and generated recommendations.