By maxaeo.ai | Published 2026-10-21 | Updated 2026-10-21
Canonical tags for generative search engines identify a preferred URL for duplicate or substantially similar content. Their documented role is clearest in Google Search. For other AI search platforms, crawler access documentation does not establish how canonical preferences affect deduplication or citation selection. Treat canonicalization as URL hygiene, not a citation-selection instruction. (developers.google.com)
The practical challenge is separating three questions: Can a system fetch the page? Which URL represents its content? Which source appears in an answer? This guide provides a framework for checking each without confusing technical correctness with visibility gains.
What does a canonical tag actually control?
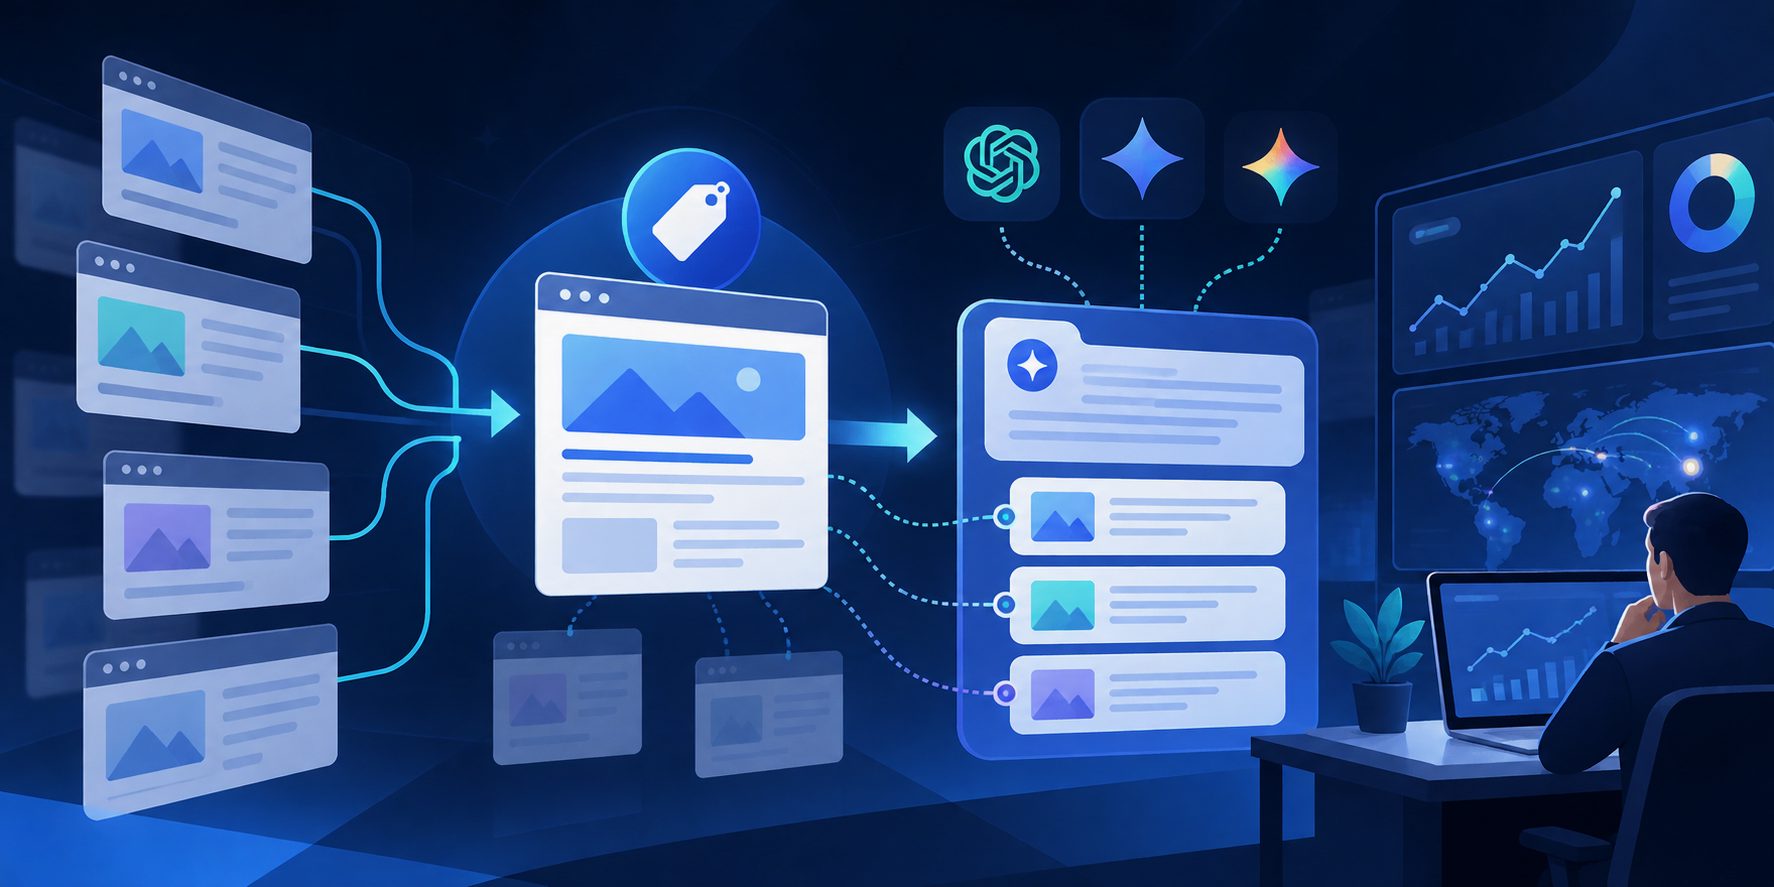
A canonical tag declares the preferred URL for duplicate or very similar pages. Google treats rel="canonical" as a strong canonicalization signal, alongside redirects; sitemap inclusion is weaker. It remains a preference rather than an instruction that Google must follow. Google can select a different representative URL. (developers.google.com)
For example, a SaaS documentation page might be accessible at:
/docs/sso//docs/sso/?utm_source=newsletter/docs/sso/?view=print
If their primary content is equivalent, the clean documentation URL is a reasonable preferred version. The canonical annotation expresses that relationship; it does not redirect visitors or determine which passages an AI answer uses. Google’s documented process groups similar pages and chooses a representative during indexing. (developers.google.com)
The important distinction: canonicalization selects a representative document URL. Citation selection concerns which source supports a particular answer. Google’s AI documentation describes supporting links, but it does not make a canonical annotation a direct citation-selection control. (developers.google.com)
Do ChatGPT and Perplexity follow canonical tags?
The official crawler documents reviewed here explain access controls, not a published canonical-selection algorithm. OpenAI distinguishes its search crawler from its training crawler. Perplexity similarly documents search crawling and user-triggered fetching. Neither document establishes that every cited URL must match a publisher’s canonical declaration. (developers.openai.com)
| System | Documented behavior | Practical implication |
|---|---|---|
| Google AI Overviews and AI Mode | Supporting pages must be indexed and eligible for a Search snippet. | Check Google indexing and canonical selection. |
| ChatGPT search | OAI-SearchBot serves search; GPTBot has a separate training purpose. | Audit search access independently of training preferences. |
| Perplexity | PerplexityBot surfaces websites in results; Perplexity-User supports user actions. | Distinguish automated crawling from requested fetches. |
These distinctions come from the platforms’ own documentation. (developers.google.com)
The defensible inference is limited: consistent URLs are sensible technical hygiene, but Google’s selected canonical does not prove what another platform will retrieve or cite. Keep AI crawler access and crawl-budget checks separate from canonical debugging.
How should canonical annotations be implemented?
Use an absolute preferred URL in the HTML head, keep canonical signals consistent, and consolidate only genuinely equivalent content. Google also supports an HTTP Link response header for non-HTML documents such as PDFs. Avoid making HTML annotations and HTTP headers point to different destinations. (developers.google.com)
<head>
  <link rel="canonical" href="https://example.com/docs/sso/">
</head>
An illustrative PDF response header is:
Link: <https://example.com/docs/sso/>; rel="canonical"
For a release review:
- Choose the intended representative URL.
- Check that variants contain equivalent primary content.
- Inspect the delivered HTML and response headers.
- Align internal links and sitemap entries with the preference.
- Use redirects when an obsolete duplicate no longer needs a separate address.
These checks operationalize Google’s canonical guidance; they are not a universal AI-platform specification. Google advises consistent signals, absolute URLs, and canonical annotations in the HTML head. (developers.google.com)
For JavaScript-heavy sites, pair this review with server-side rendering implementation checks rather than assuming a browser screenshot proves what a crawler received.
Which pages should not be consolidated?
Do not canonicalize pages merely because they share a template, product, or keyword. Canonicalization is intended for duplicate or very similar primary content. An SSO setup guide and an SSO troubleshooting guide can serve distinct needs even when their navigation and introductions overlap. (developers.google.com)
A useful editorial test is: Would replacing one page with the other remove information the reader needs? If yes, investigate before consolidating.
Examples worth preserving separately include:
- Product comparisons with materially different alternatives.
- Documentation versions with different commands or behavior.
- Regional pages with meaningful differences in service terms.
- Translations serving different-language readers.
Google recommends a canonical in the same language when using hreflang, where one exists. It also advises against using noindex as a way to force canonical selection within a site. (developers.google.com)
For canonical tags for generative search engines, the priority is therefore content equivalence—not reducing the URL count at any cost.
How can an evidence ladder isolate the real problem?
Use an evidence ladder to separate configuration, indexing, and answer outcomes. This proposed diagnostic framework prevents a common reasoning error: treating a correctly deployed tag as proof that a search system accepted it, or treating a changed citation as proof that the tag caused the change.
| Evidence layer | Record | What it establishes |
|---|---|---|
| Delivery | Status, HTML canonical, HTTP header, destination | What the server supplied |
| Google indexing | User-declared and Google-selected canonical | Google’s representative URL |
| Answer outcome | Prompt, engine, answer, cited URL, timestamp | What appeared in that observation |
Google’s canonicalization documentation distinguishes the declared preference from the URL its systems select. Its AI documentation separately describes supporting links in answers. (developers.google.com)
Diagnostic rule: if delivery passes but indexing differs, investigate consolidation. If indexing matches but citations remain absent, investigate answer relevance and source selection rather than repeatedly changing the tag.
This is a troubleshooting framework, not a measured experiment or a claim about undisclosed retrieval architecture.
How should citation changes be measured?
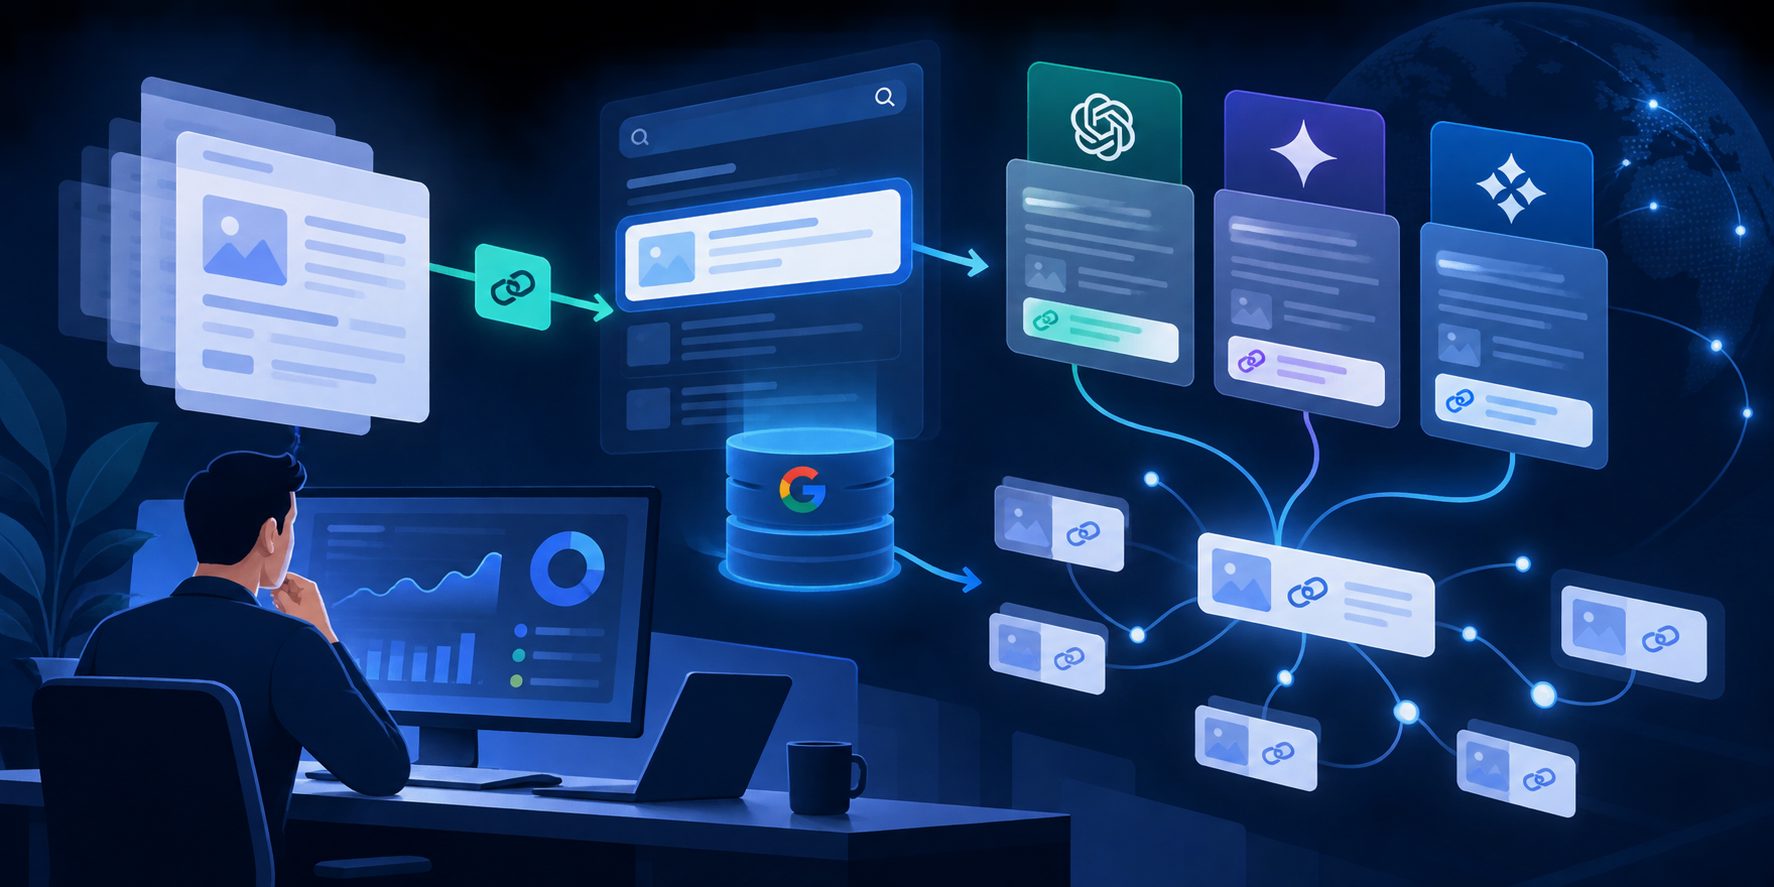
Measure URL consistency separately from overall visibility. A canonical project can have a clear consolidation objective even when total citations do not increase. The following proposed metric makes that objective explicit without presenting an invented ranking factor:
Preferred-URL citation share = citations to the intended URL ÷ citations to all mapped variants.
For an illustrative calculation—not customer data—suppose 12 observed citations reference a document family: nine point to the preferred URL and three to parameter variants. Preferred-URL citation share is 75%.
For a repeatable observation protocol:
- Map each duplicate family before deployment.
- Save a fixed prompt set and baseline answers.
- Record deployment and subsequent crawl evidence.
- Repeat observations under comparable language and engine conditions.
- Report citation counts, URL share, and concurrent site changes.
MaxAEO stores raw AI answers and tracks citation sources, supporting this evidence collection. Use its AI visibility diagnostic alongside technical inspection; neither a citation dashboard nor a canonical audit alone establishes causation.
Frequently asked questions
Is there a special canonical tag for AI search?
The official documents cited here do not define a separate AI-only canonical annotation. Google says its AI Search features require no special technical optimization beyond Search eligibility and established SEO practices. (developers.google.com)
Can robots.txt replace a canonical tag?
No. Robots rules govern crawler access; canonical annotations express a preferred URL among equivalent pages. Google specifically advises against using robots.txt for canonicalization. (developers.google.com)
Does a self-referencing canonical prove indexing?
No. It records the publisher’s preference, not an indexing outcome. Google can choose another representative URL, so verify the selected canonical separately. (developers.google.com)
What is the priority when citations show duplicate URLs?
Audit the duplicate family, verify delivered signals, and record exact citation destinations before changing templates. The useful goal for canonical tags for generative search engines is consistent, verifiable URL identity—not attributing every visibility change to one HTML element.