By maxaeo.ai | Published 2026-10-20 | Updated 2026-10-20
Understanding how to make website readable by ChatGPT requires shifting from traditional search indexing to Retrieval-Augmented Generation (RAG) optimization. ChatGPT processes content by stripping visual presentation and parsing raw textual tokens against user intent. If your architecture hides critical copy behind client-side JavaScript, throttles automated user agents, or drowns core facts in nested DOM elements, your pages become functionally invisible to generative AI answers.
Making a site readable involves unblocking OpenAI crawlers, serving clean HTML payloads, structuring data hierarchically, and delivering concise, quotable answers that language models can digest efficiently.
How ChatGPT Parses Web Content
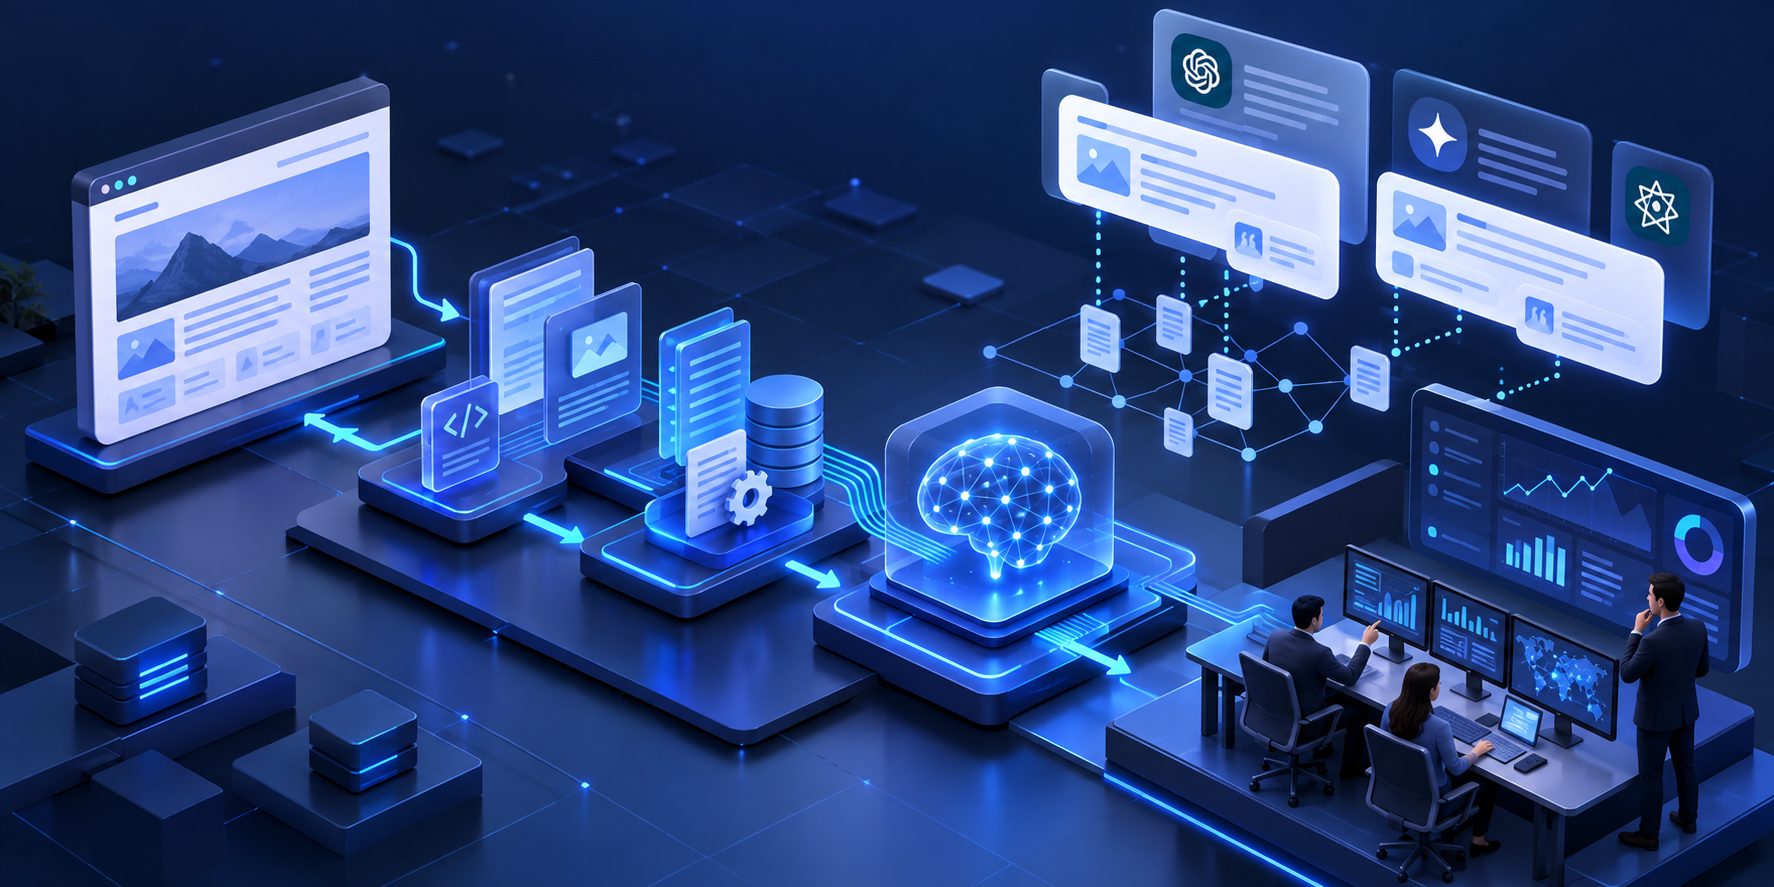
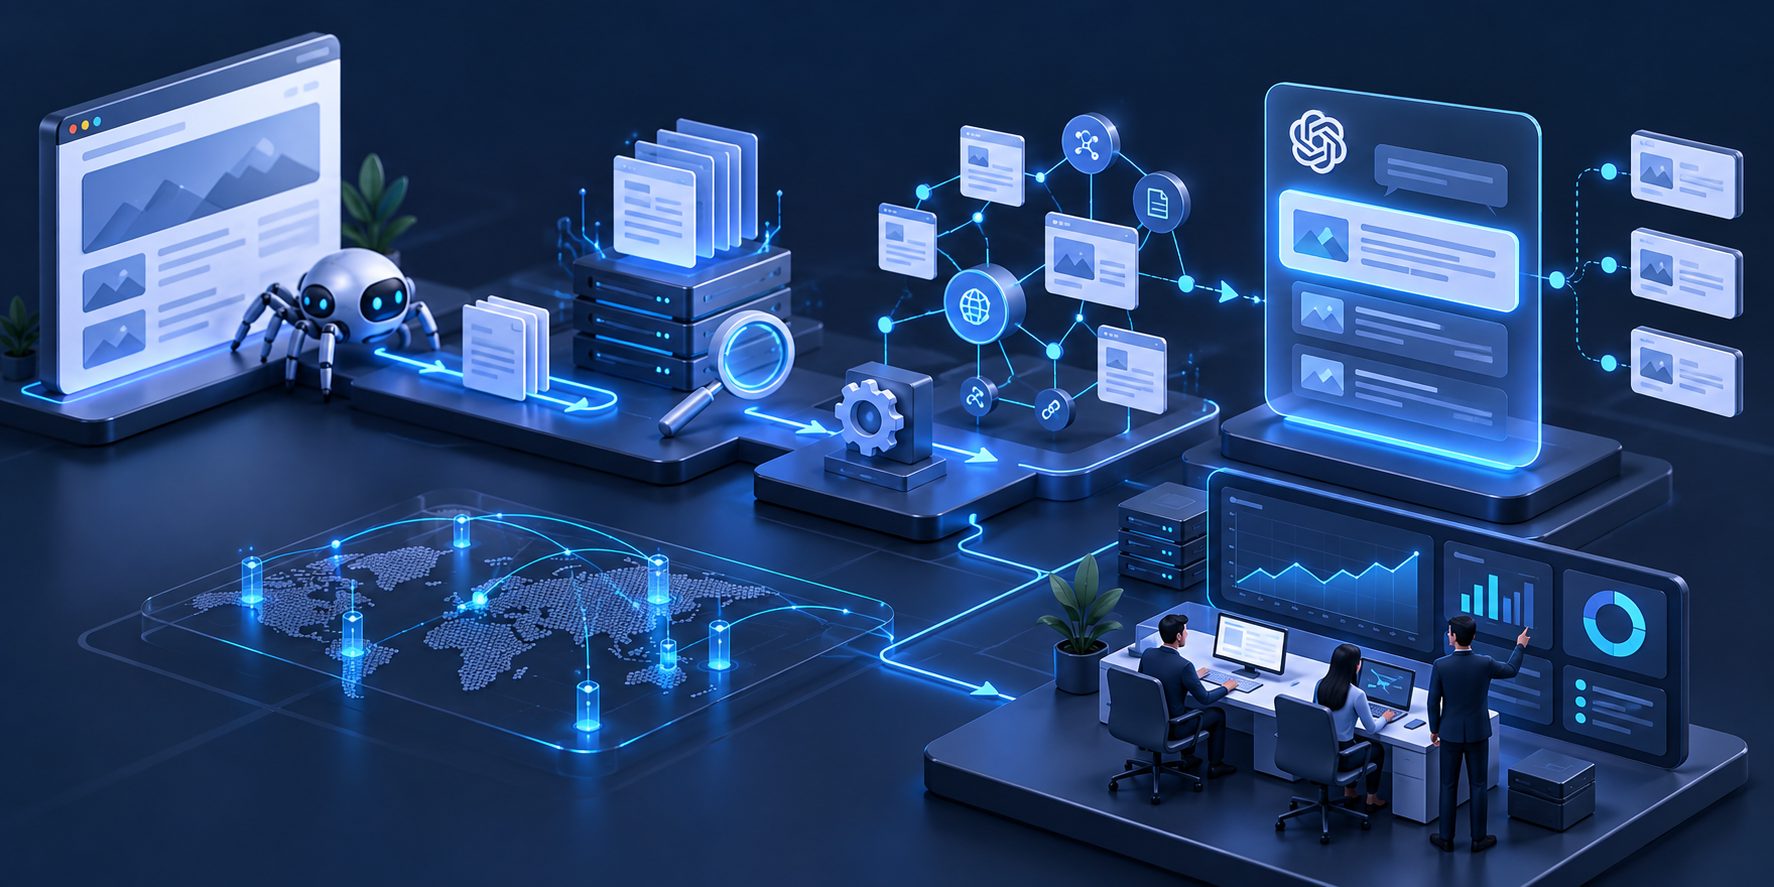
ChatGPT accesses the live web through an automated retrieval pipeline rather than a human-style browser session. When a prompt triggers a search, the model evaluates live web documents through specific retrieval agents, extracts the relevant text nodes, chunks the information into token windows, and evaluates semantic relevance.
Understanding this mechanism starts with distinguishing the three separate OpenAI user agents:
OAI-SearchBot: Dedicated to live retrieval for search features within ChatGPT. It crawls pages to index and surface them as clickable citations and grounded summaries.ChatGPT-User: Triggered dynamically when a user inputs a direct URL into a ChatGPT chat session.GPTBot: OpenAI’s foundational crawler used to collect broad training data for future model generations.
Many site operators inadvertently block OAI-SearchBot while intending only to restrict GPTBot. If search crawlers encounter a strict Disallow: / or an aggressive Web Application Firewall (WAF) challenge, retrieval fails instantly. For a deeper breakdown of permission boundaries, see our analysis on what ChatGPT can and cannot access.
5 Technical Steps to Make Your Website Readable by ChatGPT
To ensure ChatGPT can crawl, parse, and cite your pages, implement the following architectural adjustments.
1. Configure robots.txt and Firewall Permissions
The first gatekeeper is your root robots.txt file. You can grant live search indexing rights to ChatGPT while selectively managing model-training permissions.
# Allow live ChatGPT search retrieval
User-agent: OAI-SearchBot
Allow: /

# Allow on-demand user URL browsing
User-agent: ChatGPT-User
Allow: /

# Optional: Disallow general LLM model training crawl
User-agent: GPTBot
Disallow: /
Beyond robots.txt, inspect your CDN and WAF settings (such as Cloudflare Managed Challenges or Akamai bot protection). These services frequently issue CAPTCHAs or 403 Forbidden responses to headless user agents. Add OpenAI’s published IP ranges and verified user-agent strings to your WAF allowlist to prevent silent crawl failures.
2. Deliver Server-Rendered HTML
Single-page applications (SPAs) built exclusively with client-side React, Vue, or Angular often present blank HTML shells to retrieval bots. While traditional search engines eventually render JavaScript through delayed rendering queues, AI retrieval agents operate under strict latency budgets:
- If the payload does not contain rendered text within the initial HTTP response, retrieval bots often extract empty strings.
- Dynamic tabs, client-side accordions, and asynchronous pricing tables are routinely skipped.
Implementing pre-rendering or server-side rendering for LLM crawlers ensures that your mission-critical facts, tables, and product details are embedded directly in the initial DOM.
3. Minimize DOM Bloat to Optimize Token Usage
Language models ingest web documents through a context window measured in tokens. A bloated HTML document packed with inline SVG graphics, third-party tracking scripts, and twenty levels of nested <div> wrappers wastes substantial token capacity.
| Page Factor | Poor AI Readability | Optimized AI Readability |
|---|---|---|
| Rendering Format | Client-Side Hydration (CSR) | Server-Side Rendered (SSR) / Static HTML |
| Code-to-Content Ratio | < 10% (Inline CSS/SVGs, deep wrappers) | > 35% (Clean semantic tags, externalized styles) |
| Information Layout | Buried answers behind interactive tabs | Direct, answer-first paragraphs at section tops |
| Machine Context | Generic metadata, missing entities | Schema.org JSON-LD and clean llms.txt directories |
By isolating primary editorial text within standard <article>, <main>, and <section> tags, you allow text-extraction parsers (like Readability.js and Python Beautiful Soup pipelines) to discard navigation menus and extract pure signal.
4. Provide Semantic Structure and llms.txt
Clear hierarchical structure allows LLMs to reconstruct relationships between entities. Follow these structural rules:
- Use one distinct
<h1>per document that matches user search intent. - Frame
<h2>and<h3>tags as descriptive queries or explicit entity headers (e.g., "Core Features," "Pricing Tiers," "API Integration") rather than abstract marketing taglines. - Deploy an
llms.txtfile: Placing a plain-text Markdown summary file athttps://yourdomain.com/llms.txtoffers LLMs a clean index of your core pages, product documentation, and product summaries without HTML parsing overhead.
5. Validate Schema.org Structured Data
While Large Language Models rely primarily on textual comprehension, JSON-LD structured data provides explicit, machine-readable validation of entities, relationships, and product specifications. Use standard types such as Article, Product, SoftwareApplication, and Organization. Conduct a comprehensive technical GEO audit for SaaS architecture to ensure your structured data matches visible text on the page.
Content Architecture: Designing for LLM Extraction
Technical accessibility allows ChatGPT to fetch your page, but editorial architecture determines whether the model quotes your site in its generated answer.
Large language models prioritize text blocks that deliver definitive, factual answers with minimal ambiguity. Adopt an answer-first framework:
- Define entities within the first 50 words of each section using clear syntax (
[Topic] is [definition]). - Organize comparative data into markdown tables rather than dense paragraphs, especially when detailing specifications, compatibility, or pricing matrices.
- Include verifiable data points: Models are programmed to source specific benchmarks, percentages, and methodological steps over vague marketing assertions.
For multi-product or category landscapes, structuring clear tabular comparisons helps AI retrieval bots accurately synthesize your unique value proposition against competitors.
How to Test and Verify ChatGPT Accessibility
Once you configure your architecture, verify that ChatGPT can actually read and parse your pages:
- Verify Live Access in ChatGPT: Paste your target URL directly into ChatGPT Search. If the engine returns an error stating it cannot reach the page, check your server access logs for
403or401status codes triggered by bot-protection services. - Review Server Access Logs: Filter log files by the
OAI-SearchBotstring to confirm that OpenAI’s crawler fetches your pages with200 OKstatus codes. - Audit Token Parsing via Terminal: Run
curl -A "OAI-SearchBot" -L https://yourdomain.com/target-pageto view the exact HTML payload received by the crawler. If the returned body lacks your core text or returns an empty client container, fix your server-side rendering pipeline.
Configuring technical readability is only half the battle; knowing whether AI models actively cite your brand completes the loop. You can run a free AI visibility scan on maxaeo.ai to generate a diagnostic report that evaluates how your brand appears across 8 AI search engines—including ChatGPT, Perplexity, and Gemini—without requiring code installation.
Frequently Asked Questions
What is the difference between GPTBot and OAI-SearchBot?
GPTBot crawls web content to train OpenAI’s foundation models, while OAI-SearchBot crawls pages to display real-time answers, summaries, and clickable citations in ChatGPT search features. Blocking GPTBot prevents model training, but leaving OAI-SearchBot allowed enables your website to appear in live ChatGPT answers.
Can ChatGPT execute JavaScript like Googlebot?
ChatGPT’s search crawlers operate under stricter latency constraints than traditional web crawlers. While some headless rendering capabilities exist, complex client-side JavaScript, single-page frameworks, or text rendered behind dynamic clicks frequently result in incomplete indexing. Delivering server-side rendered (SSR) or static HTML ensures full readability.
Does having an llms.txt file guarantee ChatGPT citation?
No. An llms.txt file simplifies document discovery and provides a clean text hierarchy for language models, but citation depends on content relevance, factual authority, clear entity formatting, and whether your page directly answers the user’s specific prompt.
Why does ChatGPT return a "Cannot access site" error for my URL?
This error typically occurs when a website’s robots.txt disallows ChatGPT-User or OAI-SearchBot, or when a Web Application Firewall (WAF) such as Cloudflare flags the request as automated scraping and returns a 403 Forbidden challenge.