By maxaeo.ai | Published 2026-10-14 | Updated 2026-10-14
The technical SEO requirements for generative engine optimization start with accessible pages, readable content, and appropriate search permissions—not a separate AI ranking protocol. Google requires pages supporting its AI answers to be indexed and snippet-eligible. ChatGPT and Perplexity also publish their own crawler controls, which require separate checks. (developers.google.com)
For B2B SaaS teams, the useful distinction is permission, delivery, and evidence. Permission establishes whether retrieval is allowed. Delivery establishes what the requesting system receives. Evidence establishes whether the page actually appears in an answer. Treating these as separate gates makes technical fixes easier to prioritize.
What is required, and what is merely recommended?
Technical GEO readiness means meeting an engine’s documented access and eligibility conditions, then making important information reliably readable. It does not mean implementing every tactic labeled “AI optimization.” Distinguish requirements from resilience improvements and optional experiments before assigning engineering work.
For Google Search, the minimum technical conditions are an unblocked Googlebot, a working page returning HTTP 200, and indexable content. AI supporting-link eligibility also requires indexing and snippet eligibility. Google’s broader optimization guide additionally instructs owners to check inclusion in Search generative AI features within Search Console. (developers.google.com)
| Classification | Example | Engineering decision |
|---|---|---|
| Documented requirement | Google indexing and snippet eligibility | Verify before content experiments |
| Engine-specific access control | OAI-SearchBot permissions | Configure for the intended engine |
| Resilience improvement | Important facts in initial HTML | Evaluate against your rendering architecture |
| Optional experiment | llms.txt for a system that uses it |
Require an identified consumer |
Google does not require special AI schema or llms.txt; its guide says Google Search ignores these AI text files. (developers.google.com)
Which crawlers should a SaaS website allow?
Configure crawlers by purpose, not by whether their names contain “AI.” Search discovery, model training, and user-triggered retrieval are different activities. A training opt-out should therefore be reviewed separately from the permissions intended to support search visibility.
OpenAI’s crawler documentation distinguishes these agents:
- OAI-SearchBot: supports ChatGPT search discovery.
- GPTBot: crawls content that may be used for foundation-model training.
- ChatGPT-User: performs certain user-triggered requests; it is not the search crawler. (developers.openai.com)
This illustrative configuration allows OpenAI search crawling while declining its training crawler:
User-agent: OAI-SearchBot
Allow: /

User-agent: GPTBot
Disallow: /
Review it against existing groups and path restrictions before deployment. It is not a complete access-control policy.
Perplexity similarly distinguishes PerplexityBot from Perplexity-User. Googlebot controls crawling for Google Search; Google-Extended addresses other Google AI uses rather than Search crawling. Do not assume one permission controls all these experiences. (docs.perplexity.ai)
How do you verify access beyond robots.txt?
Verify the response delivered through the production CDN and firewall—not just the origin server. A permissive robots.txt file addresses crawler policy, but it does not prove that the infrastructure delivers the page. Keep policy checks and delivery checks in separate audit columns.
Perplexity’s crawler documentation recommends combining user-agent matching with published IP ranges when configuring firewall allowances. OpenAI also recommends permitting its published search-crawler IP ranges. (docs.perplexity.ai)
Use this diagnostic sequence:
- Check robots.txt for the intended agent and URL path.
- Request the public URL and record status, redirects, headers, and body.
- Compare the body with the expected article or product information.
- Inspect verified crawler requests in edge logs.
- Recheck after changing firewall rules.
A request using a copied bot user-agent is a simulation, not proof of access from that bot’s network. Likewise, treat a 200 response containing a challenge screen as a failed delivery test in your audit.
The GEO technical readiness checklist for SaaS websites provides a broader planning companion.
Must important content appear in initial HTML?
Initial HTML is a useful resilience target, not a universal GEO requirement. Google can render JavaScript, but its documentation describes crawling and rendering as separate processing stages. For critical SaaS facts, compare the initial response with the rendered page instead of assuming browser visibility proves retrieval readiness. (developers.google.com)
Select representative product, integration, comparison, and documentation pages. Check whether the response contains:
- Product identity and intended audience.
- Integration support and implementation constraints.
- Current limitations and qualification criteria.
- Descriptive links to supporting documentation.
Server-side rendering or static generation is worth considering when those facts exist only after client-side execution. Google explicitly notes that server-side rendering or prerendering can benefit users and crawlers, and that not all bots execute JavaScript. (developers.google.com)
Keep the substantive content consistent for users and crawlers. Put essential explanations in text rather than relying exclusively on screenshots. Google recommends textual availability, discoverable internal links, and a good page experience. (developers.google.com)
For architecture-specific diagnosis, use the technical GEO audit for SaaS rendering and routing.
How should canonicals, snippets, and schema be checked?
Check whether the intended evidence page is discoverable, correctly canonicalized, and permitted to appear in search previews. These controls solve different problems. Structured data should describe the visible page; it cannot substitute for access or eligibility.
Google treats redirects and canonical annotations as stronger canonicalization signals than sitemap inclusion. Align these signals around the preferred URL rather than letting internal links, sitemaps, and canonical tags point to conflicting versions. (developers.google.com)
Recommended checks include:
- Canonical targets resolve to the intended equivalent content.
- Important pages have descriptive internal links.
noindex,nosnippet, anddata-nosnippetmatch editorial intent.- JSON-LD agrees with visible authorship, dates, and page facts.
Google documents preview controls for its AI Search features and requires structured data to match visible content. It does not prescribe special GEO markup. (developers.google.com)
Prefer self-contained explanations that retain their conditions when quoted. For example, state whether an integration requires a particular plan or deployment method. This is an editorial recommendation for accuracy—not a claimed citation-ranking factor.
How can teams turn readiness into measurable evidence?
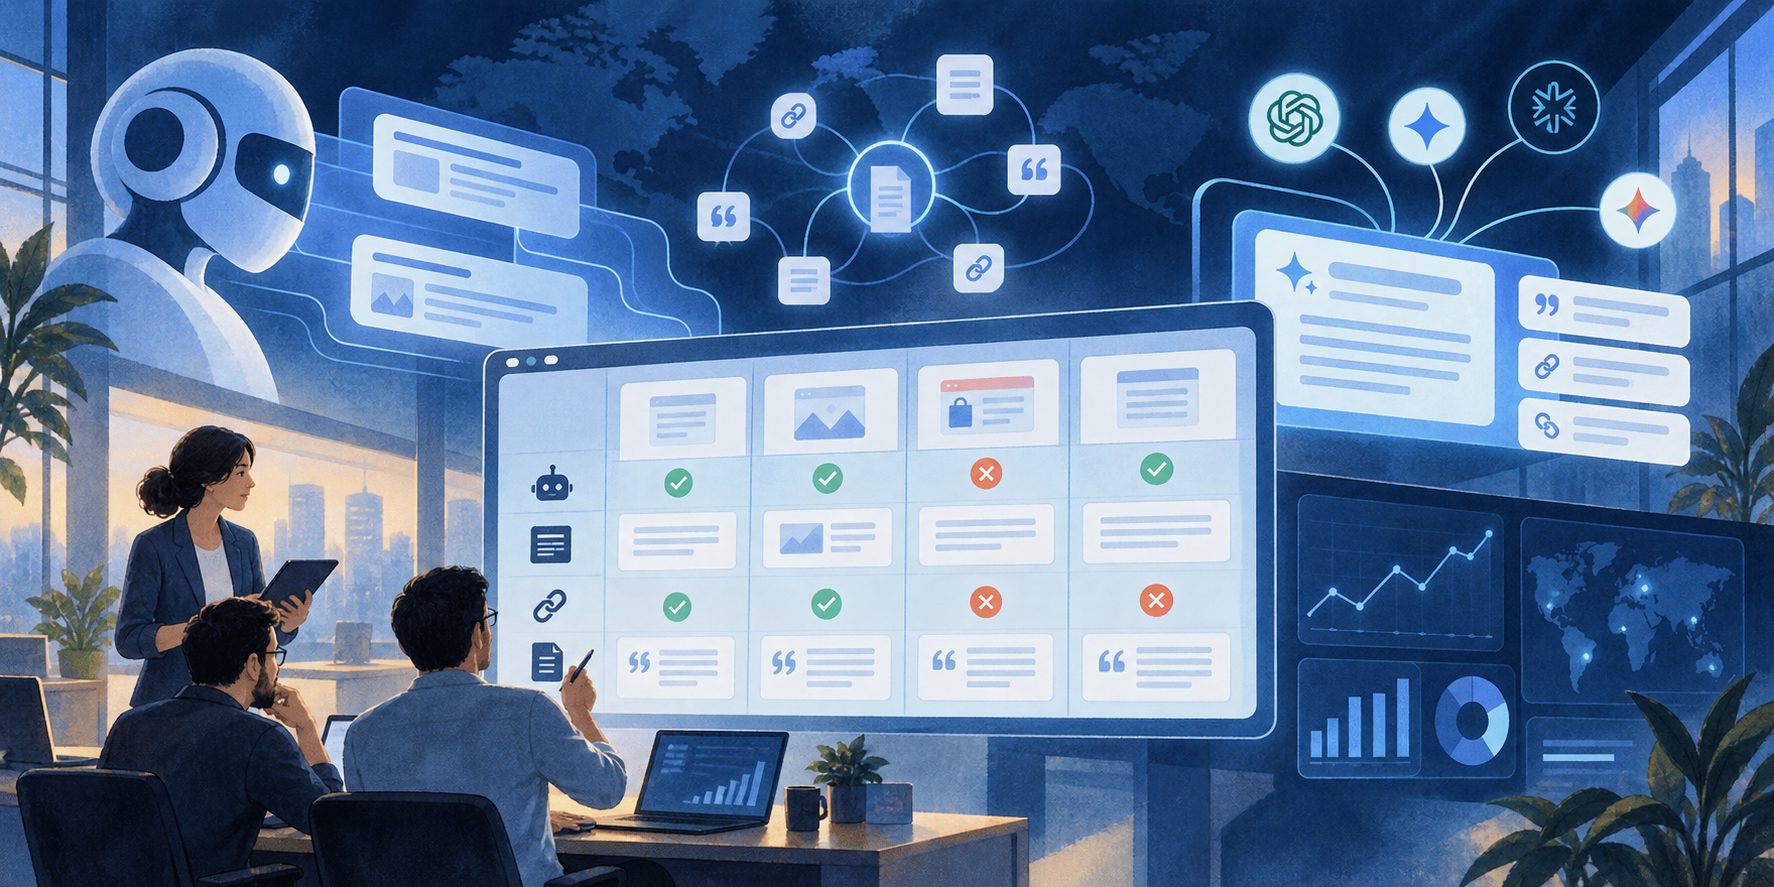
Use a three-gate evidence ledger, proposed here as an audit framework, rather than a single blended readiness score. Record permission, delivery, and answer evidence independently. This prevents an observed brand mention from being mistaken for proof that a particular website page was retrieved.
| Gate | Evidence to retain | Proposed acceptance test |
|---|---|---|
| Permission | Robots rules, preview settings, inclusion controls | Intended access is not excluded |
| Delivery | Response body, headers, rendered output, verified logs | Required facts reach the requester |
| Answer evidence | Prompt, engine, raw answer, cited URL | The answer demonstrably uses the target source |
Begin with a proposed five-page pilot: homepage, product page, integration page, comparison page, and documentation page. This is a testing design, not a reported experiment.
Keep prompts fixed during comparisons, record deployments, and separate brand mentions from target-page citations. MaxAEO monitors brand visibility across eight AI engines, runs monitoring prompts daily, tracks citation sources, and stores raw answers. Use those observations alongside infrastructure evidence, not instead of it.
The AI engine position-tracking methodology supports repeatable measurement design.
Frequently asked questions
Does passing a technical audit mean a page will appear in AI answers?
No. Technical checks establish access and eligibility, not source selection. Google states that meeting its requirements does not ensure crawling, indexing, or serving. (developers.google.com)
Is allowing GPTBot necessary for ChatGPT search visibility?
OpenAI documents GPTBot and OAI-SearchBot as independent controls. A website can allow its search crawler while disallowing its training crawler. (developers.openai.com)
Should schema come before rendering fixes?
Prioritize the blocker demonstrated by your evidence. If important content is missing from the delivered response, address that before optional markup improvements. Google does not require special schema for its generative AI Search features. (developers.google.com)
What is the best starting point for a SaaS team?
Apply the three-gate ledger to representative pages, fix demonstrated access failures, and establish an answer baseline.