By maxaeo.ai | Published 2026-10-08 | Updated 2026-10-08
Generative search prompt clusters for B2B are groups of related questions that represent the same software-buying decision. Unlike keyword clusters, they account for the buyer’s role, operational constraints, evidence requirements, and conversational context—not merely similar wording.
A useful cluster should reveal where a vendor enters or disappears from the decision chain. That makes the prompt library a measurement instrument for AI visibility, competitor positioning, and content planning.
What Makes a B2B Prompt Cluster Different From a Keyword Cluster?
A keyword cluster groups terms that can usually be answered by one search page. A generative search cluster groups prompts that require the same decision support, evidence, and vendor-selection logic. Two prompts may use different words yet belong together because they influence the same buying decision.
For example, these prompts form one shortlist cluster:
- “What customer data platforms work for a mid-market SaaS company?”
- “Which CDP can a five-person RevOps team implement without engineers?”
- “Recommend customer data tools that integrate with HubSpot and Snowflake.”
Traditional clustering may separate them by keyword. AI search research should connect them because all three ask: Which vendors deserve consideration under specific operating constraints?
This distinction matters because B2B decisions involve multiple participants. A user may prioritize workflow speed, an IT evaluator may require integration details, and procurement may ask for security or implementation evidence. Research also indicates that adding persona context can materially change the brands recommended by commercial AI systems. (arxiv.org)
Which Dimensions Should Define Each Cluster?
Reliable generative search prompt clusters for B2B should combine five dimensions: decision job, buying role, constraint, required evidence, and conversational state. This 5D Decision-Chain Matrix prevents teams from measuring a generic “average buyer” who does not exist.
| Dimension | Questions to capture | Example values |
|---|---|---|
| Decision job | What decision is being made? | Discover, shortlist, compare, validate |
| Buying role | Who needs the answer? | Champion, technical evaluator, executive, procurement |
| Constraint | What limits the choice? | Company size, industry, integrations, budget model |
| Evidence | What would make the answer credible? | Comparison table, documentation, reviews, case evidence |
| Conversational state | What does the buyer already know? | Cold question, informed follow-up, brand-aware validation |
Cluster prompts by the decision they support, not just semantic similarity. If two prompts would require different proof or content assets, they probably belong in separate clusters.
This framework extends standard buyer-stage mapping by recognizing that B2B research is often multi-person and iterative. A multi-turn prompt mapping framework can then connect initial discovery questions to later objections and validation requests.
How Do You Build the Prompt Clusters Step by Step?
Build the prompt set from evidence about real buying conversations, then expand it systematically. The objective is not to predict every sentence buyers might type. It is to create a representative, repeatable sample of the decisions that could add, remove, or reposition a vendor.
- Collect buyer language. Pull questions from sales calls, demos, support tickets, search queries, reviews, and request-for-proposal documents.
- Identify decision jobs. Label each question as problem definition, category discovery, shortlisting, comparison, or validation.
- Add buying roles. Rewrite the core question for users, technical evaluators, economic buyers, and procurement stakeholders.
- Introduce meaningful constraints. Rotate industry, team size, deployment, integration, security, and workflow requirements.
- Create conversational variants. Include cold prompts, follow-up questions, and brand-aware checks.
- Remove duplicates. Keep variants only when they could change the recommended vendors, cited sources, or answer framing.
- Assign business weights. Give more influence to clusters tied to qualified pipeline, competitive displacement, or purchase risk.
Use conversational search intent analysis to distinguish genuine decision changes from cosmetic wording variations.
What Does a Practical 32-Prompt Starter Model Look Like?
A manageable B2B baseline can use four decision jobs, four buying roles, and two conversational states: 4 × 4 × 2 = 32 prompts. This model, developed for this guide, captures decision-chain diversity without generating every possible combination of persona and constraint.
| Cluster | Cold prompt example | Informed follow-up example |
|---|---|---|
| Shortlist | “Which attribution tools suit a B2B SaaS team?” | “Which options support long sales cycles and multiple stakeholders?” |
| Technical fit | “What attribution platforms integrate with our CRM?” | “Which can preserve account-level data across those integrations?” |
| Commercial comparison | “Compare leading attribution platforms for mid-market SaaS.” | “Which option has the lowest implementation burden for our team?” |
| Risk validation | “What should procurement check before selecting a platform?” | “What evidence supports this vendor’s security and data claims?” |
Run each decision job for four roles: champion, technical evaluator, economic buyer, and procurement or risk owner. Rotate constraints within each cluster rather than multiplying every variable. This avoids a prompt library with hundreds of near-duplicates.
How Should Cluster Performance Be Measured?
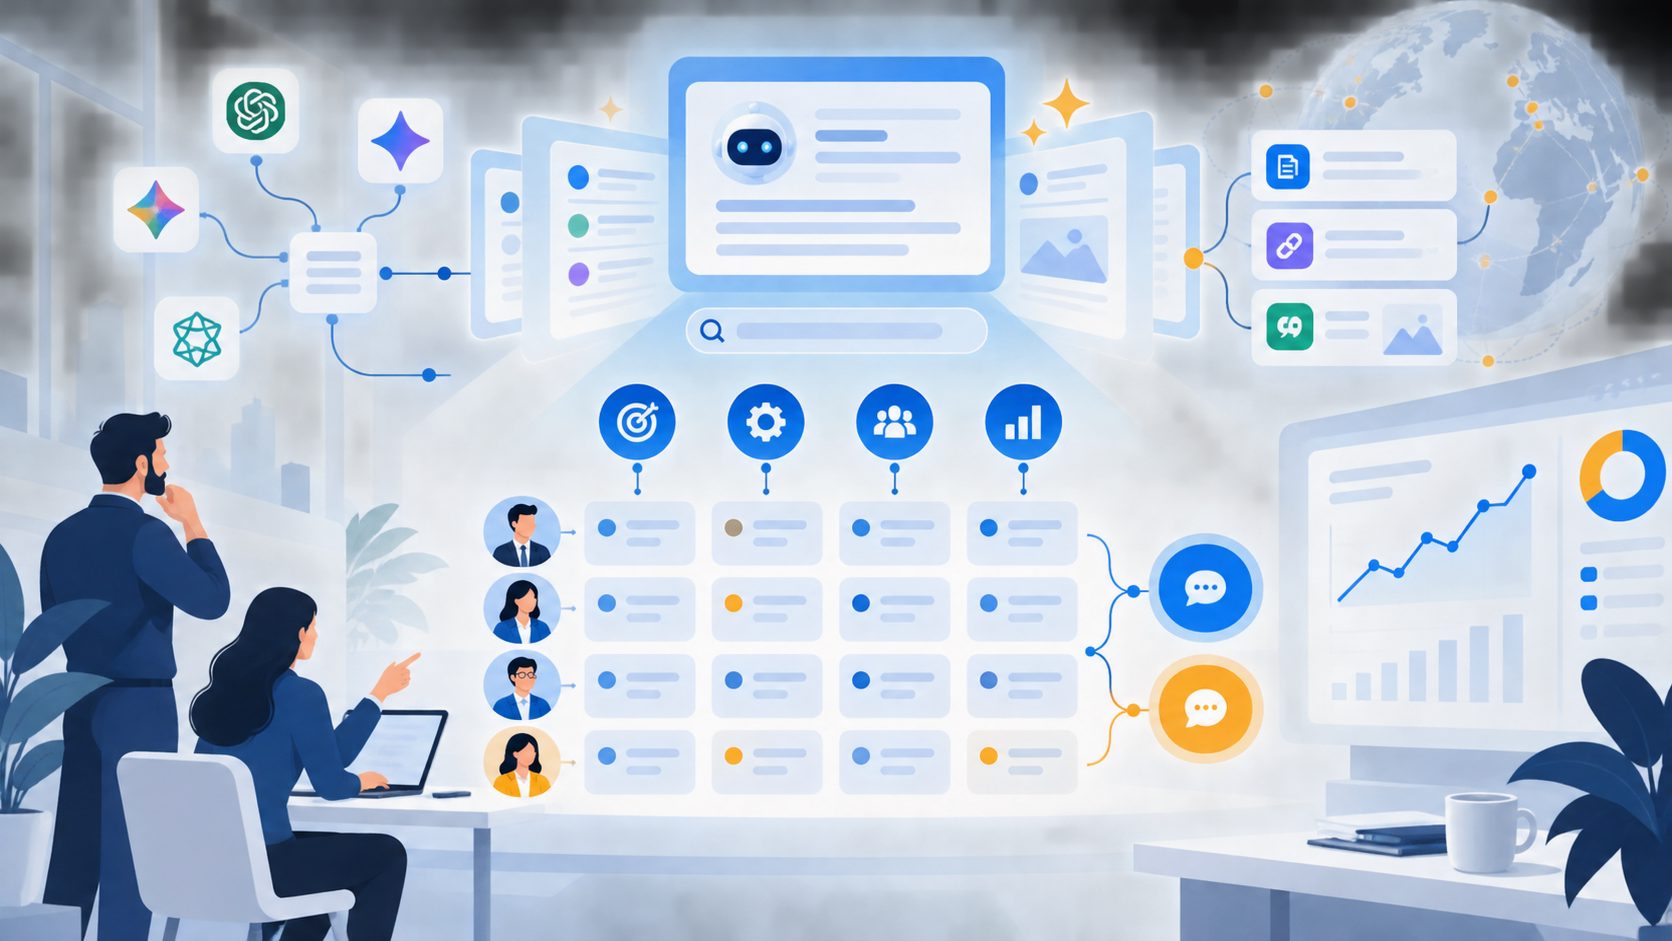
Measure performance at both prompt and cluster level. A single headline visibility score can hide a critical weakness—for example, strong brand recall but no inclusion in unbranded shortlists. Cluster-level reporting shows which decision moments require better content, evidence, or third-party coverage.
Track these signals for every cluster:
- Mention rate: percentage of answers that name the brand.
- Average recommendation position: where the brand appears among listed options.
- Competitor co-occurrence: which vendors repeatedly appear beside or instead of the brand.
- Citation-source mix: the domains, articles, reviews, documentation, and community pages supporting the answer.
- Sentiment and positioning: whether the answer frames the product accurately and favorably.
- Claim accuracy: whether product capabilities, audience, and limitations are described correctly.
A practical weighted score is:
Cluster score = Σ (cluster mention rate × business weight) ÷ Σ business weights
Run the same prompts on a consistent cadence. The daily AI search tracking workflow explains how to preserve raw answers, compare trends, and turn changes into actions rather than isolated screenshots.
Which Prompt-Clustering Mistakes Create Misleading Data?
The most damaging mistakes are importing SEO keywords unchanged, overproducing superficial variants, and averaging incompatible buyer situations. These practices make dashboards look comprehensive while reducing their ability to diagnose why a brand is—or is not—recommended.
Avoid these common errors:
- Tracking only branded prompts. They measure existing awareness, not discovery.
- Using only “best software” questions. This omits technical fit, objections, implementation, and procurement.
- Mixing personas in one score. Executive and technical prompts may produce different recommendation sets.
- Creating a page for every variation. Google advises publishers to prioritize helpful, non-commodity content instead of producing separate pages for every fan-out query. (developers.google.com)
- Changing prompts during an experiment. Keep a stable baseline set and place new prompts in a separate discovery pool.
- Ignoring source evidence. A missing mention may reflect weak third-party corroboration, not an on-page copy problem.
When competitor patterns emerge, a generative search competitor comparison matrix can connect prompt losses to positioning and evidence gaps.
Frequently Asked Questions
How many prompts should a B2B company track?
Start with 24–40 prompts covering the highest-value decision jobs, roles, and constraints. Add prompts only when they represent a distinct buying situation. A smaller balanced set is more actionable than hundreds of lightly modified questions.
How often should prompt clusters be updated?
Keep a stable measurement set for trend analysis and review its composition quarterly. Update the separate discovery pool whenever sales conversations reveal new objections, competitors, use cases, regulations, or integrations.
Can existing SEO keywords become AI search prompts?
Yes, but keywords need context. Convert each relevant keyword into a natural buyer question, then add role, use case, constraint, and desired evidence. The result should resemble a real request for decision support rather than a keyword inserted into a sentence.
How can MaxAEO support prompt-cluster measurement?
MaxAEO monitors brand mentions, citations, recommendations, sentiment, and competitor performance across eight AI engines with daily data updates. Teams can compare cluster-level visibility, inspect cited sources, and generate a free AI visibility diagnostic using a brand name, website, and competitor information.
Do generative search prompt clusters replace keyword research?
No. Keyword research remains valuable for understanding public search demand and planning discoverable pages. Generative search prompt clusters for B2B add the personas, constraints, follow-up context, and evidence needs required to analyze AI-assisted purchasing decisions.