By maxaeo.ai | Published 2026-10-08 | Updated 2026-10-08
A daily AI search tracking workflow is a repeatable process for checking how ChatGPT, Perplexity, and other answer engines mention, rank, cite, and describe your brand. The objective is not to collect random screenshots. It is to detect meaningful visibility changes, preserve evidence, and convert those changes into marketing actions.
This SOP gives marketing teams a practical system that can be completed in approximately 15–30 minutes per day once monitoring is configured.
What Should Daily AI Search Tracking Measure?
AI search tracking measures how a brand appears within answers generated for a controlled set of buyer prompts. Each observation should include the exact prompt, engine, date, answer, named competitors, cited sources, recommendation position, and surrounding sentiment.
Track these five core signals separately:
| Signal | What to record | Business question |
|---|---|---|
| Mention rate | Percentage of answers naming the brand | Are buyers likely to encounter us? |
| Recommendation position | First, second, third, later, or absent | Where do we sit on the shortlist? |
| Citation rate | Answers linking to the brand’s domain | Is our content being used as evidence? |
| Competitive share of voice | Brand mentions versus tracked competitors | Who owns the category conversation? |
| Sentiment and accuracy | Positive, neutral, negative, or factually wrong | How is the brand being positioned? |
Do not collapse these signals into one unexplained score. A brand can be mentioned frequently but rarely cited, or cited as a source without being recommended.
How Should the Prompt Panel Be Structured?
A reliable panel combines stable prompts with clear buyer intent. Start with 20–50 questions divided across category discovery, problem research, comparisons, alternatives, purchase requirements, and recommendations.
For a SaaS company, a balanced panel might contain:
- 20% category prompts: “What is the best software for managing X?”
- 20% problem prompts: “How can a distributed team solve Y?”
- 20% comparison prompts: “Product A vs Product B for mid-market teams”
- 20% alternatives prompts: “What are the leading alternatives to Product A?”
- 20% decision prompts: “Which platform is best for a regulated US company?”
Freeze the wording and assign each prompt an ID. If the wording changes, create a new version rather than overwriting historical data. The multi-turn prompt mapping framework can help extend the panel from initial discovery questions to evaluation and purchase-stage conversations.
What Is the Daily AI Search Tracking Workflow?
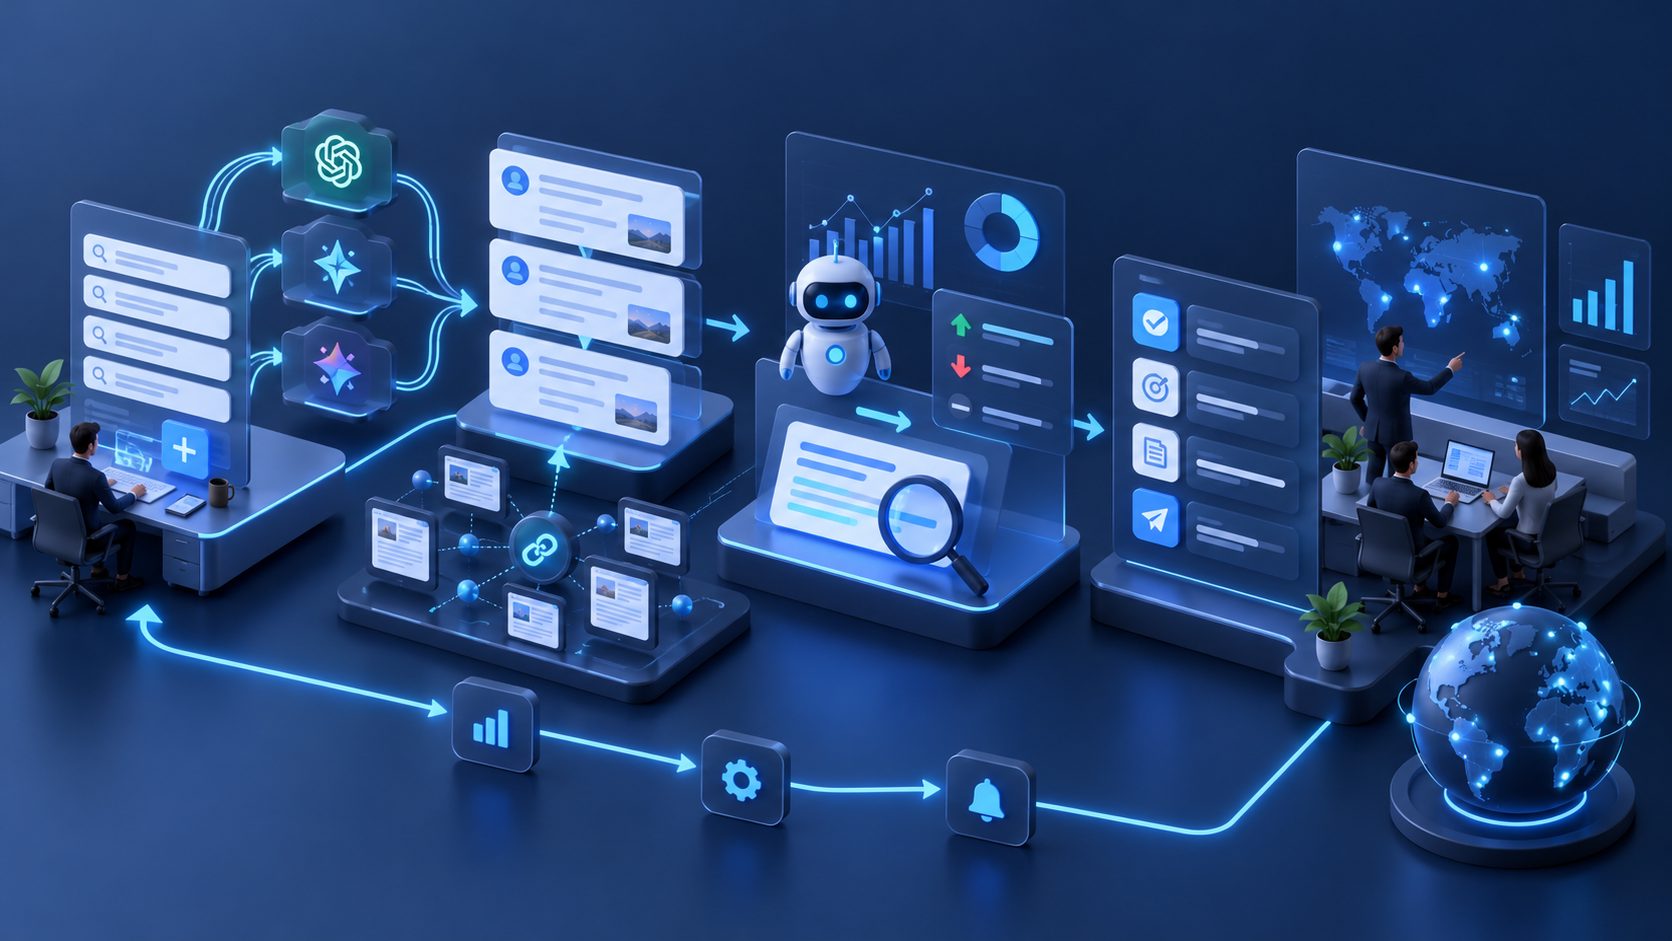
The workflow follows five ordered steps: run the fixed panel, validate collection quality, review exceptions, inspect source evidence, and assign actions. Most daily attention should go to changes—not unchanged responses.
-
Run the same prompts on schedule.
Execute each prompt against ChatGPT and Perplexity under consistent settings. Keep engine, locale, account state, retrieval mode, and prompt wording as stable as possible. Record failed requests separately rather than counting them as brand absences. -
Store the complete answer.
Save the raw response, timestamp, citations, named brands, recommendation order, and relevant sentences. Raw-answer retention allows reviewers to verify whether automated classification was correct. -
Compare results with the previous run.
Flag new mentions, lost mentions, position changes, new competitors, sentiment shifts, factual errors, and source-domain changes. An automated brand monitoring alert workflow can reduce manual review by surfacing only material exceptions. -
Inspect the evidence chain.
For every important change, identify which pages the engine cited and what claim each page supported. Separate first-party citations from review sites, communities, news publications, technical documentation, and competitor pages. -
Route one accountable action.
Assign the issue to content, SEO, digital PR, product marketing, customer advocacy, or legal review. Every ticket should contain the prompt, engine, evidence, suspected gap, owner, and review date.
How Can Teams Separate Signal From Daily Noise?
Generative answers are variable, so one changed response should not automatically trigger a campaign. Research based on repeated sampling across Perplexity, OpenAI search, and Gemini found that single-run citation measurements can appear more precise than they really are. (arxiv.org)
Use the 2×2 Evidence Gate, an operational framework for deciding whether a change deserves action:
- Repeatability: Did the change appear on two consecutive days or in two engines?
- Commercial relevance: Does it affect a high-intent comparison, alternative, or recommendation prompt?
Escalate immediately when both conditions are met. Watch the result when only one is met. Archive isolated changes on low-intent prompts unless they involve harmful misinformation.
The “two days or two engines” threshold is a practical starting rule, not an industry benchmark. Teams with larger prompt panels can add seven-day rolling averages and confidence intervals.
How Should Daily Findings Become Marketing Actions?
A monitoring program creates value only when observations lead to specific interventions. Match the detected gap to the smallest defensible action instead of responding with a generic request to “create more content.”
| Detected change | Recommended response |
|---|---|
| Competitor replaces your brand | Compare positioning, proof, and cited sources |
| Brand is mentioned but not cited | Strengthen first-party evidence and quotable passages |
| Outdated product claim appears | Update canonical pages and consistent third-party listings |
| Negative comparison language grows | Review product positioning and independent evidence |
| A new source domain appears repeatedly | Assess it for PR, review, partnership, or contribution opportunities |
| Visibility drops across every engine | Check prompt coverage, crawlability, recent content changes, and category shifts |
For deeper investigations, use a source-chain competitive evidence workflow rather than copying a competitor’s page format. The goal is to understand which claims and sources shaped the answer.
What Should Be Reviewed Weekly Instead of Daily?
Daily reviews detect exceptions; weekly reviews identify patterns. Once a week, calculate mention rate, citation rate, average recommendation position, sentiment distribution, and competitive share of voice by engine and prompt cluster.
The weekly meeting should answer four questions:
- Which buyer-intent cluster gained or lost visibility?
- Which competitors increased their presence?
- Which domains became recurring citation sources?
- Which completed actions should remain under observation?
Do not average ChatGPT and Perplexity before reviewing them separately. Engine-level reporting shows whether a problem is widespread or limited to one retrieval and answer environment. Teams focused heavily on Perplexity can apply a dedicated 30-prompt Perplexity tracking framework.
How Can MaxAEO Support This SOP?
MaxAEO automates daily monitoring across eight AI engines, including ChatGPT, Gemini, Perplexity, Claude, Copilot, Grok, Google AI Mode, and Google AI Overview. It tracks brand mentions, recommendation position, sentiment, citations, and competitor performance while retaining the underlying AI answers.
Marketing teams can compare mention frequency and citation sources, convert existing SEO keywords into monitoring prompts, and use optimization recommendations to plan AI-ready content. MaxAEO does not automatically publish that content; the team decides which recommendations to implement.
A free AI visibility diagnostic is available on maxaeo.ai using a brand name, website, and competitor information.
Frequently Asked Questions
Should AI search visibility be checked every day?
Daily tracking is useful for fast-moving SaaS categories, launches, reputation risks, and active optimization programs. Stable categories may use weekly runs, but the cadence should remain consistent so periods can be compared fairly.
Can a spreadsheet support this workflow?
Yes. A spreadsheet can store prompts, engines, mentions, positions, citations, competitors, sentiment, and notes. Automation becomes valuable when the panel spans multiple engines, brands, markets, or daily reporting cycles.
Is a brand mention the same as a citation?
No. A mention means the answer names the brand. A citation means the engine links to a page as supporting evidence. Track both because a brand may receive one without the other.
When should a visibility change trigger action?
Act when a commercially important change repeats on consecutive runs, appears across multiple engines, or contains material misinformation. A single low-impact fluctuation should usually remain under observation.
What is the most important daily deliverable?
The most useful deliverable is a short exception queue containing the changed prompt, answer evidence, business impact, assigned owner, and next review date. A dashboard without accountable actions is only a reporting layer.
A disciplined daily AI search tracking workflow turns volatile answers into comparable evidence. Keep prompts stable, preserve raw responses, separate engines, investigate recurring changes, and connect every material finding to a named owner.