By maxaeo.ai | Published 2026-10-03 | Updated 2026-10-03
Weighted AI visibility scoring measures a brand’s exposure across AI engines while accounting for where buyers search, which prompts matter, and how prominently the brand is recommended. Unlike a simple mention rate, it distinguishes a first-place recommendation on a high-value engine from a passing mention on a low-relevance prompt.
What Is Weighted AI Visibility Scoring?
Weighted AI visibility scoring is a normalized method for combining brand mentions, recommendation positions, engine importance, and buyer-intent value into one 0–100 score. A brand earns more credit when it appears prominently in AI answers that are more likely to influence its target market.
A basic mention rate treats every observation equally:
Mention Rate = Answers mentioning the brand ÷ Valid answers × 100
That metric is useful but incomplete. It would treat a brand ranked first in ChatGPT and a brand listed fifth in a less-used engine as equivalent mentions.
A weighted model instead scores each engine-prompt observation, then calculates a normalized average:
Weighted Score = 100 × Σ(Engine Weight × Intent Weight × Observation Score) ÷ Σ(Engine Weight × Intent Weight)
The denominator includes every valid answer, including those where the brand is absent. This prevents weak visibility from being hidden by calculating position only among successful mentions.
Which Components Should the Score Include?
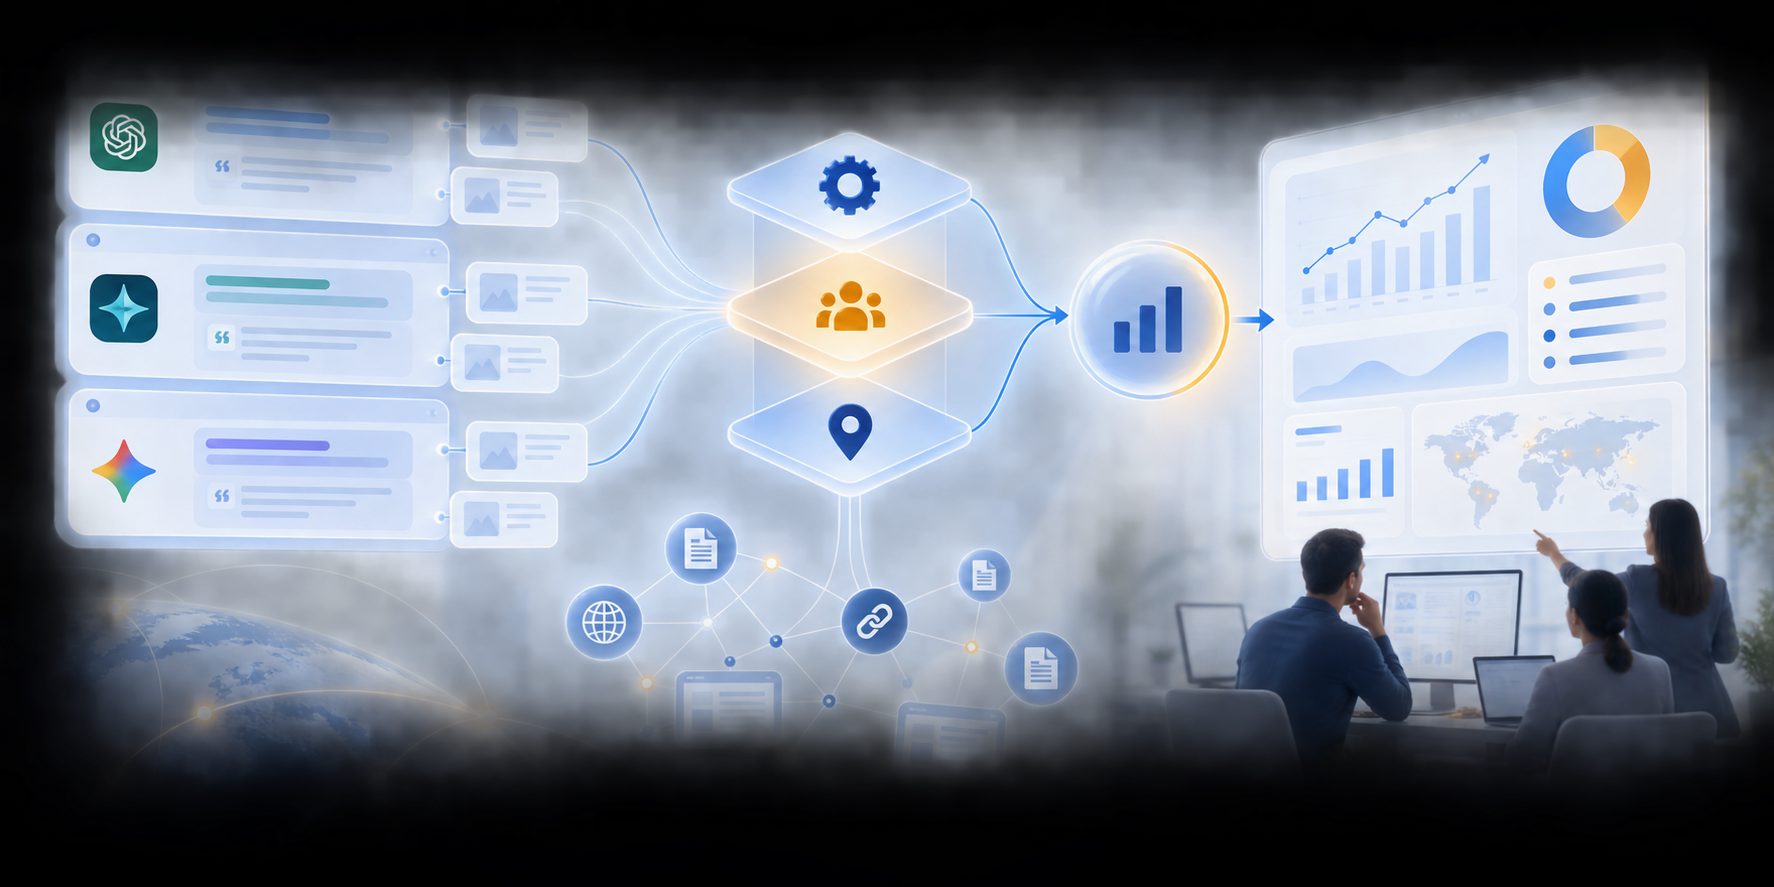
A defensible composite score needs four inputs: engine weight, prompt-intent weight, mention status, and recommendation position. Sentiment and citations should remain supporting diagnostics unless the reporting objective explicitly requires them in the headline metric.
| Component | Purpose | Suggested scale |
|---|---|---|
| Engine weight | Represents the engine’s share of the target audience | Weights total 1.00 |
| Intent weight | Reflects the commercial importance of each prompt | 1–5 or normalized |
| Mention status | Records whether the brand appears | 0 or 1 |
| Position weight | Values prominent recommendations more highly | 0–1 |
| Recommendation strength | Separates incidental mentions from endorsements | 0.6–1.0 |
One practical position schedule is 1.00 for first, 0.70 for second, 0.50 for third, and 0.30 for fourth or lower. For unordered answers, assign a documented default such as 0.50 rather than inventing a precise rank.
Recommendation strength can equal 0.60 for an incidental mention, 0.80 for shortlist inclusion, and 1.00 for an explicit recommendation. The resulting observation score is:
Observation Score = Mention × Position Weight × Recommendation Strength
For broader measurement context, use a separate reproducible framework for measuring brand visibility in LLMs.
How Should AI Engine Weights Be Assigned?
Engine weights should represent usage among your addressable buyers—not global traffic estimates alone. The most accurate inputs come from first-party research, sales conversations, website referrals, customer surveys, and AI-assisted discovery data segmented by market.
A SaaS company might initially allocate:
- ChatGPT: 0.50
- Gemini: 0.30
- Perplexity: 0.20
These are example weights, not universal market-share claims. A developer product could assign more weight to citation-oriented research engines, while a consumer brand might emphasize platforms embedded in broader search journeys.
Review weights quarterly, but do not silently rewrite historical scores. Save an engine-weight version with every reporting period so leadership can distinguish performance changes from methodology changes.
Also publish results by engine. A composite score supports executive reporting, while engine-level results reveal where optimization is actually needed. MaxAEO monitors mentions, recommendation position, sentiment, citations, and competitive visibility across eight AI engines with daily updates.
Worked Example: Why Weighting Changes the Result
Weighting can materially change the interpretation of identical mentions because the engines and positions do not contribute equal exposure. Consider one buyer prompt tested across three engines using the example weights above.
| Engine | Engine weight | Result | Position weight | Recommendation strength | Contribution |
|---|---|---|---|---|---|
| ChatGPT | 0.50 | Ranked first | 1.00 | 1.00 | 0.500 |
| Gemini | 0.30 | Ranked third | 0.50 | 0.80 | 0.120 |
| Perplexity | 0.20 | Not mentioned | 0.00 | 0.00 | 0.000 |
The final score is:
100 × (0.500 + 0.120 + 0.000) = 62
The unweighted mention rate is 66.7% because the brand appeared in two of three answers. The weighted score is 62 because the Gemini mention was less prominent and Perplexity contributed zero.
Here is the original analytical insight: the same observations score 46.7 with equal engine weights, 62 with the example usage weights, and 35 if Perplexity receives half of the total weight. Weight selection is therefore a strategic assumption that should always be disclosed.
How Can the Score Remain Reproducible?
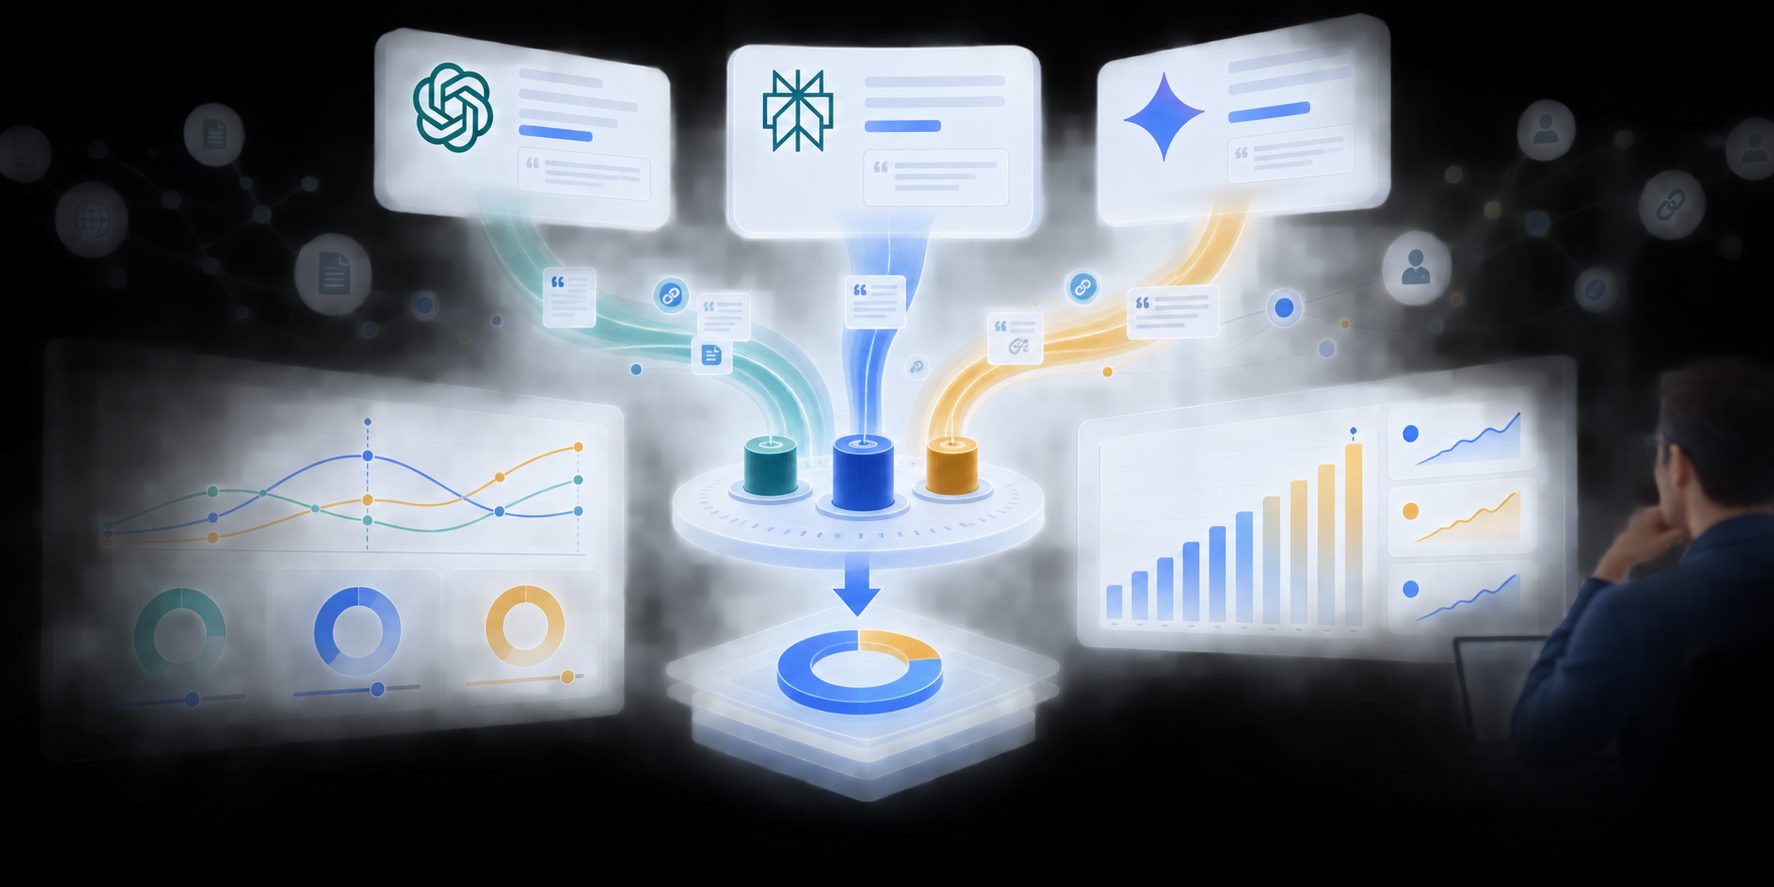
A visibility score is reproducible only when another analyst can reconstruct it from the prompt set, engine list, raw answers, coding rules, and weight table. A polished dashboard cannot compensate for an undocumented denominator or changing prompt sample.
Use this six-step process:
- Freeze the prompt set. Map prompts to discovery, comparison, evaluation, and purchase intent.
- Define valid responses. Record errors, refusals, and unavailable engines separately.
- Run repeated observations. AI answers vary, so score trends rather than isolated outputs.
- Store raw answers. Preserve the sentence containing the brand, its position, and cited sources.
- Version every weight. Track changes to engines, intent values, and ranking rules.
- Report component metrics. Show mention rate, top-three rate, citations, sentiment, and competitive share beside the composite.
A useful prompt structure starts with the B2B buyer journey prompt map and can be benchmarked using a cross-engine share-of-model formula.
What Mistakes Make a Weighted Score Misleading?
The most common scoring errors are biased prompts, arbitrary engine weights, unstable samples, and excessive compression into one headline number. These flaws can produce precise-looking results that do not represent real buyer exposure.
Avoid these practices:
- Including mostly branded prompts, which make mentions almost inevitable
- Removing absent-brand answers from the denominator
- Using global engine popularity as a proxy for your buyers without validation
- Changing prompts and weights during a campaign without version control
- Treating cited, mentioned, and recommended as interchangeable outcomes
- Combining languages or countries before checking market-level differences
- Reporting a movement smaller than the score’s normal run-to-run variation
The composite should guide prioritization, not replace diagnosis. A score can rise because of stronger rankings, broader prompt coverage, or improvement on one heavily weighted engine. Teams still need source-level evidence to choose the right action.
MaxAEO supports this diagnostic layer through competitive mention comparisons, recommendation-position monitoring, sentiment analysis, raw-answer retention, and citation-source tracking. Its free AI visibility report can be generated from a brand name and website without installing code.
Frequently Asked Questions
What is a good weighted AI visibility score?
There is no universal good score because prompt sets, engine weights, categories, and competitive density differ. Benchmark against direct competitors using the same methodology and prioritize sustained gains beyond normal observation variance.
Should sentiment be included in the main score?
Usually, no. Visibility and sentiment answer different questions: whether the brand appears and how it is described. Report sentiment alongside visibility unless reputation quality is an explicit objective of the composite.
How often should engine weights change?
Review them quarterly or after a meaningful shift in buyer behavior. Keep historical weight versions so a methodology update is not mistaken for improved brand performance.
Is weighted AI visibility scoring the same as AI share of voice?
No. Share of voice measures a brand’s portion of competitive mentions. A weighted visibility score can additionally account for engine reach, prompt importance, ranking position, and recommendation strength.
Can one score replace engine-level reporting?
No. Use the composite for trend and executive communication, then use engine, prompt, competitor, and citation breakdowns to diagnose causes. The AI search scorecard for CMO reporting provides a broader reporting structure.