By maxaeo.ai | Published 2026-10-02 | Updated 2026-10-02
B2B buyer journey prompts in AI search are the questions prospects ask ChatGPT, Perplexity, Gemini, and similar engines while defining a problem, discovering software, comparing vendors, validating risk, and choosing a product. Mapping these questions exposes whether your SaaS appears throughout the decision—not merely when someone already knows its name.
A useful prompt strategy therefore begins with buyer intent rather than a list of product keywords.
How Do AI Prompts Change Across the B2B Buyer Journey?
AI prompts become more specific as buyers move toward a purchase. Early questions describe a business problem; middle-stage questions request categories and shortlists; late-stage prompts introduce named vendors, integrations, pricing models, implementation risks, and evidence requirements.
A 2026 analysis of 609 SaaS queries identified a recurring progression from problem framing through category research, tool exploration, comparison, and validation. It also found that branded evaluation queries were longer than informational ones, reflecting the additional constraints buyers introduce near a decision. (position.digital)
For a B2B SaaS company, this creates five practical stages:
- Problem definition: What is going wrong?
- Solution discovery: What approach or software category could help?
- Shortlist creation: Which products fit the situation?
- Evaluation: How do the leading options differ?
- Decision validation: What evidence could confirm or block the purchase?
Monitoring only “best software” questions misses the conversations before and after the shortlist.
What Prompts Should You Track at Each Funnel Stage?
The strongest prompt portfolio combines buyer stage with context. Each question should reveal the buyer’s role, desired outcome, operating environment, constraints, or decision criteria—not simply repeat a category keyword.
| Buyer stage | Buyer’s objective | High-value prompt template | Best supporting asset |
|---|---|---|---|
| Problem definition | Diagnose a costly workflow | “Why does our [process] fail when [condition]?” | Educational guide or original research |
| Solution discovery | Identify possible approaches | “How can a [company type] achieve [outcome] without [constraint]?” | Use-case guide |
| Shortlist creation | Find relevant vendors | “Which [category] tools fit a [team size] using [stack]?” | Category and integration pages |
| Evaluation | Compare trade-offs | “Compare [Vendor A] and [Vendor B] for [specific use case].” | Factual comparison page |
| Validation | Reduce purchase risk | “What are the limitations, implementation requirements, and proof for [vendor]?” | Documentation, security, migration, and proof pages |
Use unbranded prompts to measure discoverability and branded prompts to inspect positioning, sentiment, and factual accuracy. The B2B buyer prompt coverage framework explains how to keep those two groups separate.
How Does the 5×6 Buyer-Prompt Grid Work?
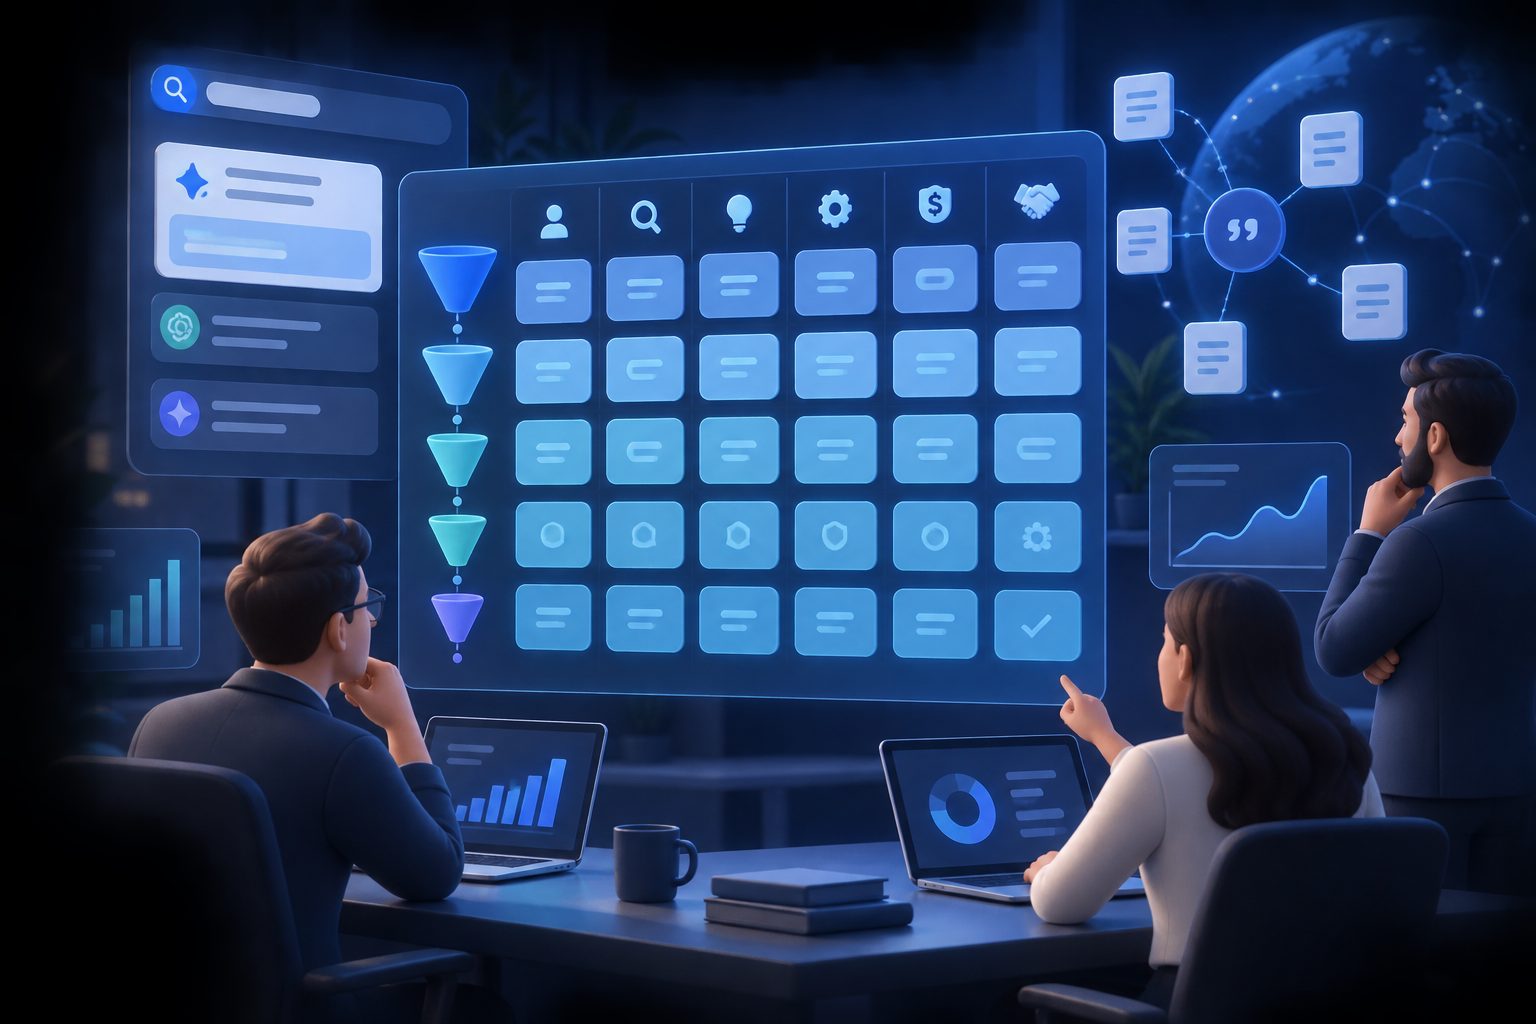
The 5×6 buyer-prompt grid is an original framework for creating a balanced 30-prompt baseline. Start with the five funnel stages above, then write one prompt for each of six decision constraints: persona, company profile, job to be done, existing stack, purchase risk, and required proof.
For example, a generic question such as “What are the best customer support platforms?” becomes more commercially useful when rewritten as:
- Persona: “Which support platforms work best for a customer success leader?”
- Company profile: “What support software fits a 100-person B2B SaaS company?”
- Job: “Which tools reduce first-response time without adding agents?”
- Stack: “What support platforms integrate with Salesforce and Slack?”
- Risk: “Which options minimize migration and data-residency risk?”
- Proof: “Which vendors document implementation time and customer outcomes?”
This grid prevents overinvestment in comparison prompts while problem-aware, integration, procurement, and proof questions remain unmeasured. Teams can expand the baseline only when results reveal a meaningful AI search opportunity gap.
How Should SaaS Teams Prioritize High-Conversion Prompts?
Prioritize prompts by decision proximity, commercial fit, and evidence readiness. A late-stage question is valuable only if it represents your target customer and your company has accurate, accessible evidence that an answer engine can retrieve.
Score each prompt from 1 to 3 on four dimensions:
- Fit: Does the question describe your ideal customer?
- Intent: Is the buyer researching, shortlisting, or validating?
- Differentiation: Can the answer reveal a meaningful product advantage?
- Evidence: Do you have documentation, data, comparisons, or third-party support?
Add the four scores. Prompts scoring 10–12 form the priority monitoring set; scores of 7–9 indicate content or evidence opportunities; lower scores belong in a secondary panel.
This is a planning score, not an industry benchmark. Its purpose is to stop high-volume but weak-fit questions from outranking narrower prompts that resemble real buying decisions.
How Do You Measure Prompt Visibility Across AI Engines?
Measure each fixed prompt using answer-level signals: brand presence, recommendation position, framing accuracy, sentiment, competitors mentioned, and cited sources. Preserve the original response so changes can be reviewed rather than reduced to a single visibility percentage.
A practical workflow is:
- Freeze the prompt wording and associated buyer stage.
- Run it across the AI engines relevant to your market.
- Record whether the brand is mentioned, cited, or recommended.
- Capture recommendation order and the surrounding description.
- Identify the domains and pages supporting the answer.
- Compare results by engine, competitor, and funnel stage.
- Improve the appropriate asset, then rerun the same prompt.
The cited source often reveals the actual gap. A missing brand may require clearer documentation, a comparison asset, original research, or third-party validation—not another generic blog post. Use a repeatable AI search prompt optimization checklist and inspect the sources cited by ChatGPT and Perplexity before selecting a corrective action.
Turning the Prompt Map Into an Operating System
A buyer-journey prompt map becomes useful when marketing, product, sales, and customer teams share it. Sales can contribute objection language, customer success can identify implementation concerns, and product marketing can verify whether AI answers communicate the intended audience and differentiators accurately.
MaxAEO monitors brand mentions, citations, recommendations, sentiment, competitor performance, and average recommendation position across eight AI engines. Monitoring prompts run daily, while stored answers and citation tracking help teams investigate why visibility changes.
Start with the 30-prompt grid, maintain a stable core panel, and review gaps by journey stage rather than relying on one aggregate score. A free AI visibility diagnostic on maxaeo.ai can establish an initial baseline without requiring internal documents, revenue data, or customer lists.
Frequently Asked Questions
How many AI search prompts should a B2B SaaS company track?
Thirty prompts provide a focused starting point when built from five buyer stages and six decision constraints. Add prompts when a new persona, use case, market, competitor, or procurement requirement creates a distinct buying conversation.
Should most prompts contain the brand name?
No. Most should be unbranded questions that test whether the product enters consideration naturally. Branded prompts remain useful for checking factual accuracy, sentiment, comparisons, limitations, and purchase risk.
Are AI prompts the same as SEO keywords?
No. Keywords summarize topics, while prompts express a buyer’s situation, constraints, follow-up questions, and desired decision. Existing SEO keywords can seed the research, but they should be rewritten as natural buyer questions.
Which metrics matter beyond brand mentions?
Track recommendation position, description accuracy, sentiment, cited domains, citation relevance, competitor share of voice, and coverage by funnel stage. A mention with incorrect positioning can be less useful than an accurate, well-supported recommendation.