By maxaeo.ai | Published 2026-09-27 | Updated 2026-09-27
A cross engine AI visibility tracker shows whether AI platforms mention, cite, rank, or recommend your brand when buyers ask relevant questions. Its real value is not combining several dashboards. It is creating a comparable measurement system across ChatGPT, Perplexity, Gemini, and other answer engines.
This guide explains what that system should measure, where blended scores become misleading, and how SaaS teams can evaluate platforms before committing budget.
What Is a Cross-Engine AI Visibility Tracker?
A cross-engine tracker is software that runs a controlled set of prompts across multiple AI engines, records the resulting answers, and converts them into brand-level metrics. These metrics commonly include mention rate, recommendation position, cited sources, sentiment, factual accuracy, and competitor share of voice.
This differs from a traditional rank tracker. AI-generated answers do not provide one stable list of ten links. One engine may recommend a brand, another may cite its documentation without naming it, and a third may omit it entirely.
The tracker must therefore preserve three layers of evidence:
- The prompt: What was asked, for which persona and buying stage?
- The engine response: What did the platform say, and in what order?
- The extracted signal: Was the brand mentioned, cited, recommended, or misrepresented?
A percentage without those underlying records is difficult to audit or act upon.
Why Can a Single Visibility Score Be Misleading?
A combined score is useful for executive reporting, but it can conceal the engine-specific gaps that marketers need to fix. AI platforms use different retrieval systems, source sets, response formats, and citation behavior, so their raw counts should not be treated as interchangeable.
A 2026 study of Perplexity, Google Gemini, and OpenAI SearchGPT found substantial citation variability across repeated samples. It concluded that single-run measurements can appear more precise than they really are and recommended repeated sampling with explicit treatment of uncertainty. (arxiv.org)
For practical reporting, keep the engine-level data visible beneath any blended metric. A sound dashboard should answer:
- Is the brand consistently present or appearing sporadically?
- Is it named but not linked?
- Does it lead the answer or appear near the end?
- Which competitor replaces it when it is absent?
- Which domains influence the answer?
- Did performance change across many prompts or only one response?
Daily trend lines are more useful than isolated screenshots because they distinguish persistent gaps from normal answer variation.
Which Metrics Should Buyers Require?
The best measurement model separates presence, prominence, evidence, and perception. Combining them too early creates an attractive number that may hide why visibility changed.
| Metric | What it measures | Procurement question |
|---|---|---|
| Mention rate | Percentage of tracked answers naming the brand | Can results be filtered by engine, topic, and intent? |
| Recommendation position | Where the brand appears among suggested options | Is position extracted consistently from lists and prose? |
| Citation rate | How often the brand’s domain is cited | Can users inspect the exact cited page and source domain? |
| Competitor share of voice | Brand appearances relative to selected competitors | Are the same prompts and engines used for every brand? |
| Sentiment | Positive, neutral, or negative brand framing | Can the underlying sentence be reviewed? |
| Accuracy | Whether product claims are factually correct | Does the platform preserve the original response? |
| Prompt coverage | Visibility across category, comparison, and purchase prompts | Can existing SEO keywords become natural-language prompts? |
| Trend stability | Direction of performance over repeated runs | How often is each prompt rerun? |
Teams that need a consistent composite metric can use a documented formula rather than a proprietary score with unknown weighting. The LLM visibility score formula provides a reproducible starting point for combining multiple signals.
How Should You Evaluate a Tracker Before Buying?
Use this original 100-point cross-engine procurement scorecard. It emphasizes measurement integrity over dashboard appearance.
1. Engine Coverage and Separation: 25 Points
Award points for the engines your buyers actually use—not the largest logo count. Confirm that each engine is queried separately and that results can be filtered without losing the cross-platform view.
Look for transparent handling of AI search surfaces, model changes, failed runs, missing citations, and answer formats. A platform should never convert missing data into a zero without labeling the difference.
2. Prompt Design and Governance: 20 Points
A tracker is only as useful as its prompt panel. It should support prompts for category discovery, alternatives, comparisons, use cases, objections, integrations, and final recommendations.
Require tagging by persona, geography, language, funnel stage, and topic. Before configuring monitoring, use a prompt coverage gap framework to identify buyer questions that ordinary SEO keyword lists overlook.
3. Evidence and Auditability: 20 Points
The platform should retain raw answers, cited URLs, mention sentences, timestamps, and engine identity. Without this evidence, marketing teams cannot distinguish a genuine competitive change from an extraction error.
Exports also matter. Data should be usable in recurring reports, internal analysis, and content planning rather than trapped inside a summary chart.
4. Competitive Intelligence: 20 Points
Strong competitor analysis shows where, why, and with what evidence another brand wins. It should compare mention frequency, recommendation position, sentiment, and citation sources under equivalent conditions.
A structured competitor GEO audit checklist can help teams turn those differences into testable content and authority-building actions.
5. Actionability and Operating Fit: 15 Points
The final 15 points cover workflow: daily updates, alerts, exports, bilingual tracking, historical retention, and understandable optimization recommendations.
Do not award points merely because a tool generates content. The more important question is whether its recommendations trace back to an observed prompt, missing citation, inaccurate claim, or competitor advantage.
What Does a Reliable Monitoring Workflow Look Like?
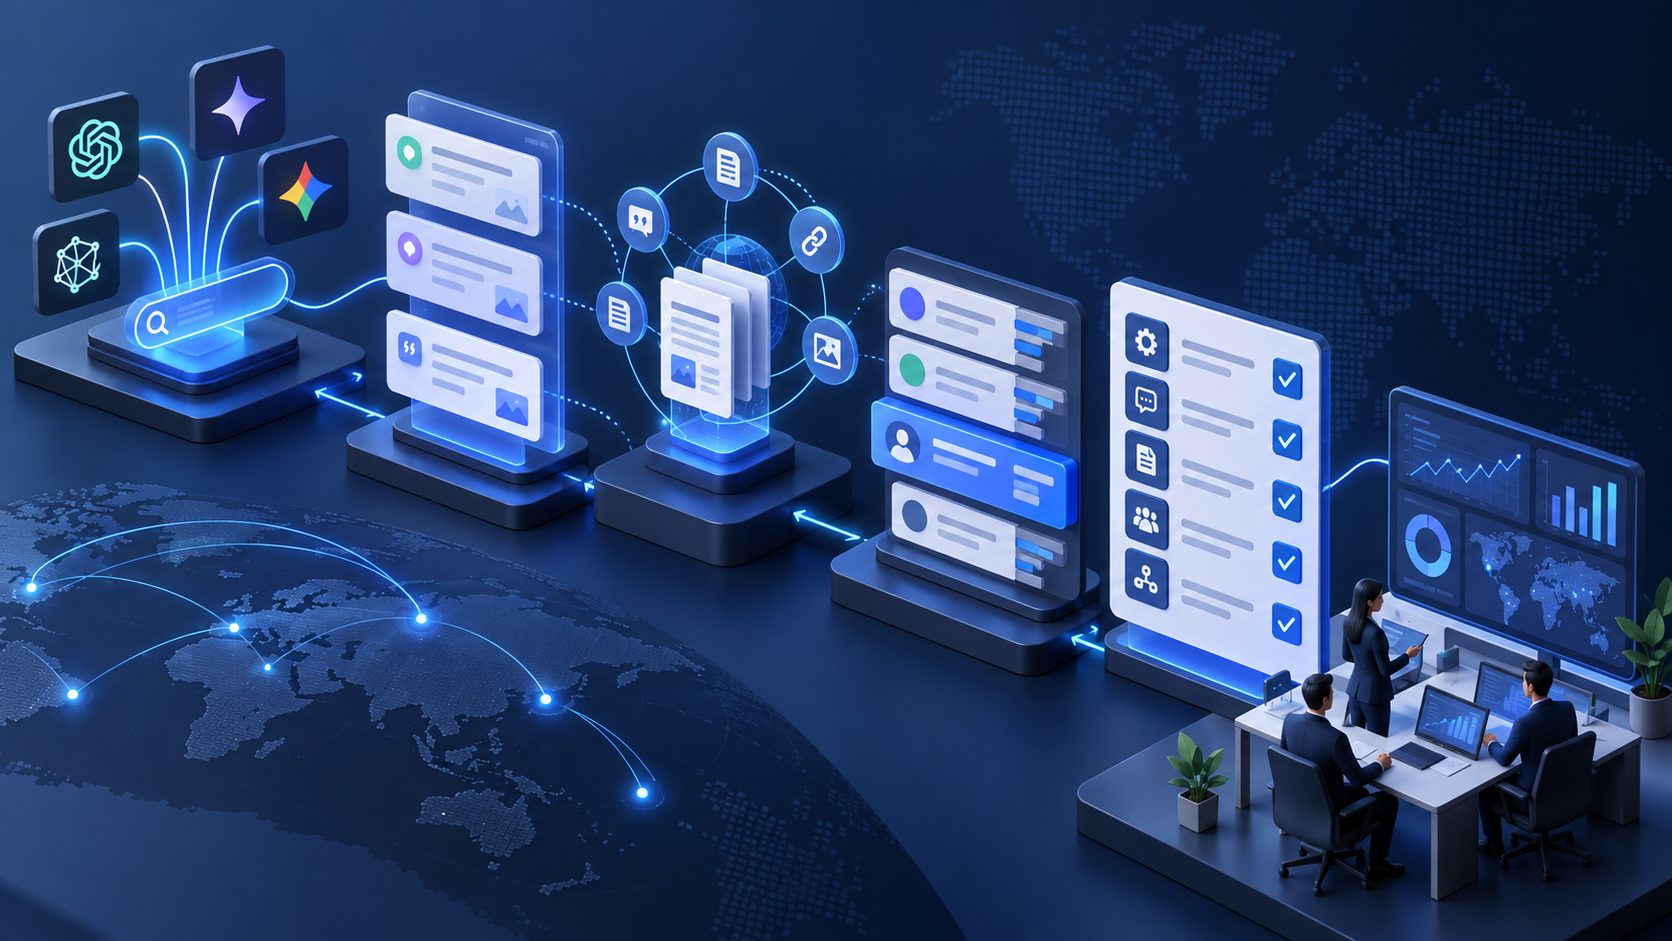
A reliable workflow moves from controlled measurement to prioritized action. It does not respond to every daily fluctuation with an immediate content change.
- Define the market: Select brands, competitors, languages, regions, and buyer personas.
- Build the prompt panel: Include discovery, comparison, objection, and purchase-intent questions.
- Establish a baseline: Run the same panel across each selected engine.
- Separate the signals: Record mentions, recommendation positions, citations, sentiment, and accuracy independently.
- Identify persistent gaps: Prioritize patterns visible across multiple prompts or monitoring periods.
- Inspect cited sources: Determine whether engines rely on documentation, comparison pages, reviews, communities, or other third-party sources.
- Ship targeted improvements: Update inaccurate product information, strengthen missing topic coverage, or create clearer evidence.
- Measure the new baseline: Compare like-for-like prompts instead of relying on anecdotal tests.
For ongoing ownership and reporting cadence, use an AEO reporting workflow for marketing teams.
How Does MaxAEO Support Cross-Engine Monitoring?
MaxAEO is an AI search visibility platform for monitoring brand mentions, citations, recommendations, sentiment, and competitors. It runs monitoring prompts daily and supports eight AI surfaces: ChatGPT, Gemini, Perplexity, Claude, Copilot, Grok, Google AI Mode, and Google AI Overviews.
Teams can compare brand and competitor mention rates, recommendation positions, sentiment, and citation sources. MaxAEO also stores original AI answers for reviewing the sentences behind extracted metrics and provides optimization recommendations based on observed performance gaps.
Monitoring covers English and Chinese markets through maxaeo.ai and maxaeo.cn. No code installation is required: a basic diagnosis starts with a brand name, website, and competitor information.
Organizations can generate a free AI visibility diagnostic report on maxaeo.ai before selecting a paid monitoring configuration.
Frequently Asked Questions
How many AI engines should a tracker cover?
Cover every engine that materially influences your audience, then prioritize measurement quality. Four well-monitored engines with raw evidence and daily trends may be more useful than a longer list with shallow or irregular data.
Should AI mentions and citations share one metric?
No. A brand can be mentioned without its website being cited, while its content can also be cited without a prominent recommendation. Track both separately before creating an aggregate score.
How often should AI visibility be measured?
Daily monitoring provides enough continuity to detect trends while preserving individual responses for investigation. Strategic decisions should rely on repeated patterns rather than one-day movements.
Can traditional SEO software replace an AI visibility tracker?
Not completely. SEO platforms measure rankings, pages, links, and search traffic. AI brand monitoring measures generated answers, recommendations, cited sources, sentiment, and competitor presence. The two datasets are complementary.
What is the first step for evaluating a platform?
Run a representative pilot using the same buyer-intent prompts, competitors, regions, and engines you expect to monitor after purchase. Then verify that every reported metric can be traced to a stored answer.