By maxaeo.ai | Published 2026-09-24 | Updated 2026-09-24
An allow PerplexityBot robots.txt guide should cover more than one directive. You need to configure the crawler, check catch-all rules, review your firewall, and confirm that the live page is accessible. This guide explains the correct syntax, the difference between PerplexityBot and Perplexity-User, and a practical verification method for AI citation visibility.
What is PerplexityBot?
PerplexityBot is Perplexity’s search crawler for discovering and linking websites in Perplexity search results. Perplexity says it is not used to crawl content for AI foundation-model training, and recommends allowing the bot if you want your pages to appear as sources in its search results. (docs.perplexity.ai)
That makes PerplexityBot different from a general-purpose training crawler. Blocking it is primarily a search-discovery decision: your public pages may become less available for retrieval and citation in Perplexity answers.
Perplexity also documents a separate user agent, Perplexity-User. This fetcher may access a page after a user asks a question. Perplexity states that this user-requested fetch generally ignores robots.txt rules, so a robots.txt rule for PerplexityBot should not be treated as a complete access-control system. (docs.perplexity.ai)
How do you allow PerplexityBot in robots.txt?
Add an explicit user-agent group to the root-level /robots.txt file:
User-agent: PerplexityBot
Allow: /
This tells a compliant PerplexityBot crawler that it may request URLs across the site. The exact token matters: use PerplexityBot with the same capitalization shown in Perplexity’s documentation. Its documented full user-agent string includes PerplexityBot/1.0, but robots.txt matching should target the product token rather than the entire browser string. (docs.perplexity.ai)
If your existing file already permits all crawlers, the explicit block may appear redundant. It is still useful as an operational signal because it makes your policy visible to developers, SEO teams, and security tools.
A typical public-site configuration might look like this:
User-agent: PerplexityBot
Allow: /

User-agent: *
Allow: /
Disallow: /admin/
Disallow: /account/
Disallow: /api/
Do not copy this example over your entire file without checking your current Googlebot, sitemap, staging, and private-path rules. Add the PerplexityBot group while preserving directives that serve other parts of your technical SEO setup.
For broader context, compare this configuration with MaxAEO’s guide to robots.txt for LLMs and AI crawlers.
How do you allow only selected sections?
You can allow PerplexityBot to crawl public content while excluding sensitive or low-value paths:
User-agent: PerplexityBot
Allow: /
Disallow: /admin/
Disallow: /account/
Disallow: /checkout/
Disallow: /internal-search/
Disallow: /api/
The goal is to expose pages that can legitimately answer public questions: product documentation, comparison pages, research, pricing explanations, and editorial content. Avoid placing customer records, authenticated dashboards, private support content, or unpublished assets behind a robots.txt assumption.
Google Search Central emphasizes that robots.txt controls crawling, not security. A disallowed URL can still be discovered, and robots.txt should not be used to protect confidential information. Use authentication, authorization, or server-side access controls for private material. (developers.google.com)
There is also an important distinction between crawling and indexing. If a page must not appear in search results, a noindex directive is usually more appropriate—but crawlers must be able to access the page to see that directive. Blocking the same URL in robots.txt can prevent crawlers from discovering the noindex instruction. (developers.google.com)
Why can PerplexityBot still fail after you add Allow?
An Allow: / rule only addresses robots.txt; it does not guarantee that your server, CDN, WAF, or page rendering layer will admit the request. In practice, AI crawler visibility should be checked as a layered access problem.
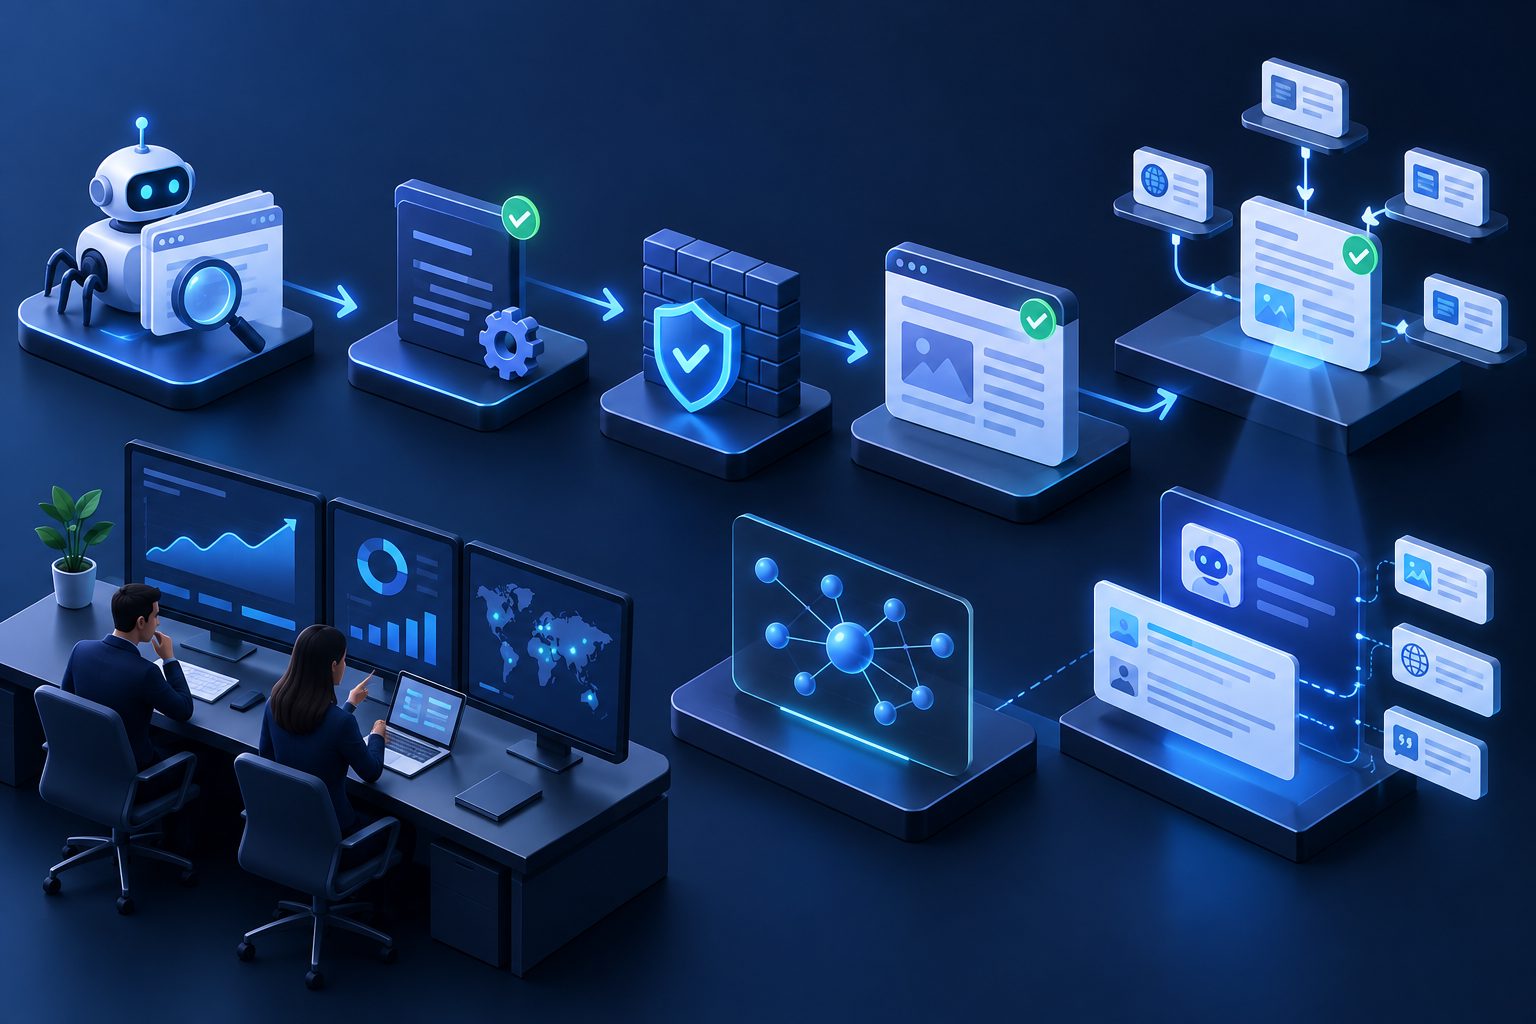
Use this four-layer model:
| Layer | What to check | Typical failure |
|---|---|---|
| Robots policy | /robots.txt returns HTTP 200 and contains the correct token |
A wildcard Disallow: / still applies |
| Network access | CDN, WAF, and rate limits permit the request | Bot challenge or 403 response |
| Origin response | The page returns useful HTML | Empty shell, redirect loop, or 5xx error |
| Content eligibility | The page contains clear, public, indexable information | Thin, duplicated, or blocked content |
Perplexity’s documentation specifically recommends combining user-agent matching with published IP ranges when configuring a WAF. Its guidance for Cloudflare and AWS WAF uses both signals, and says the current IP ranges should come from Perplexity’s official JSON endpoints rather than from a static third-party list. (docs.perplexity.ai)
This is the most commonly missed point in competing setup guides: a permissive robots.txt does not override a firewall rule. If your WAF blocks the request before it reaches the origin, the crawler never gets a chance to read your Allow directive.
How do you verify that Perplexity can access your site?
Use a repeatable verification sequence after publishing the file:
-
Fetch the live robots.txt file.
Openhttps://example.com/robots.txtin a browser or use:curl -i https://example.com/robots.txtConfirm the response is successful, the file is served from the correct hostname, and the content is not being generated differently for regions or user agents.
-
Search for the exact bot token.
Look for:User-agent: PerplexityBotCheck whether a later or broader group contains a conflicting
Disallow: /. Also inspect rules inherited through your CMS or deployment system. -
Request a public page with the documented user agent.
curl -A "PerplexityBot" -I https://example.com/your-public-page/A successful status does not prove that the page is eligible for citation, but a 403, 429, 503, or challenge page identifies an access problem.
-
Inspect server and WAF logs.
Look for the user-agent, response code, requested path, and security action. For stronger verification, compare the request source with Perplexity’s current published IP ranges. Perplexity advises keeping those ranges updated because they can change. (docs.perplexity.ai) -
Test actual citation visibility.
Search Perplexity using buyer questions that should reasonably surface your page. Record whether the page is cited, which passage is used, and whether competitors appear instead. Crawling access is a prerequisite, not a ranking guarantee.
MaxAEO can support this final measurement layer by tracking brand mentions, competitive visibility, citation sources, sentiment, and recommendation position across eight AI engines with daily updates. Its AI citation tracking guide explains how to evaluate whether technical access translates into observable source inclusion.
Should you allow PerplexityBot or block it?
For most public SaaS, publishing, documentation, and ecommerce websites, allowing PerplexityBot is the logical default when AI search discovery is part of the acquisition strategy. It gives Perplexity’s search crawler permission to discover and link eligible pages, while you can still exclude private paths and protect sensitive systems through authentication and firewall controls.
Blocking may be appropriate when you have a deliberate policy against Perplexity search discovery, operate a private or restricted site, or need to reduce crawler traffic during an infrastructure incident. Use:
User-agent: PerplexityBot
Disallow: /
Treat the decision separately from Perplexity-User. Perplexity documents that Perplexity-User handles user-requested page access and generally ignores robots.txt, so access control for sensitive content must come from authentication or network policy—not from a crawler directive alone. (docs.perplexity.ai)
Common questions
Does allowing PerplexityBot guarantee a citation?
No. Allowing the crawler only makes eligible content available for discovery. Citation decisions can depend on relevance, freshness, authority, query intent, page quality, and competing sources.
Is Allow: / required if there is no Disallow rule?
No. An empty or absent restriction can already permit crawling, depending on the rest of the file. An explicit Allow: / is useful for clarity and for sites that maintain an intentional allowlist.
Should PerplexityBot be grouped with Googlebot?
No. Give it its own User-agent group. A rule written only for Googlebot does not automatically create an equivalent policy for PerplexityBot.
Does robots.txt protect private content?
No. Robots.txt is a crawler instruction, not an access-control mechanism. Use login requirements, permissions, and server-side protection for confidential pages.
How long do changes take to appear?
Perplexity says changes to crawler settings may take up to 24 hours to be reflected in its systems. (docs.perplexity.ai) Continue checking logs and citation results after the change rather than judging visibility immediately.