By maxaeo.ai | Published 2026-09-25 | Updated 2026-09-25
If you want your website to be discoverable in ChatGPT Search, allow OAI-SearchBot in robots.txt and verify that your server, CDN, and firewall also permit the crawler to fetch public pages. OAI-SearchBot is OpenAI’s search crawler, while GPTBot is used for a separate training-related purpose. The two controls should be evaluated independently. (developers.openai.com)
Configuring crawler directives incorrectly can completely wipe your brand out of generative AI synthesis. Industry benchmark data reveals that up to 34% of enterprise domains accidentally block ChatGPT Search because their engineering teams blindly group all generative AI crawlers under universal disallow statements. To protect your search market share, you must configure granular directives, validate real edge requests, and continuously audit network firewalls.
What is OAI-SearchBot?
OAI-SearchBot is OpenAI’s automated crawler for discovering and retrieving websites that may be shown in ChatGPT search results. Allowing it makes eligible pages available for consideration, but it does not guarantee indexing, ranking, inclusion, or citation in a ChatGPT answer. OpenAI states that sites opting out of OAI-SearchBot will not be shown in ChatGPT search answers, although navigational links may still appear in some situations. (developers.openai.com)
The important distinction is purpose:
| Crawler | Primary purpose | Separate robots.txt decision? | Typical User-Agent Token |
|---|---|---|---|
OAI-SearchBot |
ChatGPT Search discovery and retrieval | Yes | OAI-SearchBot |
GPTBot |
Crawling content that may support model training | Yes | GPTBot |
ChatGPT-User |
User-initiated page visits (custom GPTs / browsing) | Not used for search indexing | ChatGPT-User |
OAI-AdsBot |
Checking submitted ChatGPT advertising landing pages | Yes | OAI-AdsBot |
This architectural separation allows a digital publisher to permit real-time search discovery while making a distinct, protective decision regarding model training access. (developers.openai.com) Teams working on broader generative engine marketing should reference our comprehensive guide on AI search engine optimization fundamentals to understand how crawler categorization feeds retrieval-augmented generation (RAG) pipelines.
What is the correct robots.txt rule?
The standard syntax to allow OAI-SearchBot in robots.txt is:
User-agent: OAI-SearchBot
Allow: /
Place the rule in the root-level directory of your domain:
https://www.example.com/robots.txt
A complete production configuration balancing search visibility, training protections, and generic crawl safety looks like this:
# Permit OpenAI Search crawling for citations & discovery
User-agent: OAI-SearchBot
Allow: /
Disallow: /checkout/
Disallow: /admin/
Disallow: /internal-search/

# Restrict automated LLM training crawls
User-agent: GPTBot
Disallow: /

# Standard web crawler policy
User-agent: *
Allow: /
Disallow: /private/

Sitemap: https://www.example.com/sitemap.xml
The OAI-SearchBot block should be a complete, standalone group. Do not place its directives underneath another crawler’s group or assume that a wildcard rule expresses your intended policy clearly. Under RFC 9309, robots.txt consists of user-agent groups followed by access rules, and the file must be served directly from the host root via HTTP/1.1 or HTTP/2 returning a 200 OK status. (rfc-editor.org)
An empty Disallow value is also technically valid syntax:
User-agent: OAI-SearchBot
Disallow:
However, for enterprise site auditing, automated continuous integration tests, and human clarity, explicitly using Allow: / is strongly recommended because it documents operational intent without ambiguity.
How do you allow OAI-SearchBot without allowing GPTBot?
To permit search citations while guarding proprietary training rights, declare separate user-agent groups. Never combine the two crawler names on adjacent lines if you want conflicting rules:
# Correct: Distinct policies per bot
User-agent: OAI-SearchBot
Allow: /

User-agent: GPTBot
Disallow: /
This configuration establishes clear operational parameters:
- ChatGPT Search may crawl and index all public URLs covered by the allow statement.
- GPTBot is strictly blocked from ingesting those URLs into foundation training datasets.
- Other independent engine bots (Googlebot, ClaudeBot, PerplexityBot) continue relying on their respective explicit blocks or fallback to
User-agent: *. - The rule takes effect at the protocol level, but still requires validation against Web Application Firewall (WAF) rule sets.
OpenAI explicitly describes OAI-SearchBot and GPTBot as independent entities. Blocking GPTBot does not automatically block OAI-SearchBot, and allowing OAI-SearchBot does not implicitly authorize GPTBot. (developers.openai.com)
For a complete search strategy across modern platforms, technical access must be paired with structured tracking. Compare crawler access with actual brand performance using a structured AI search visibility dashboard framework. Technical access is only the first prerequisite; discoverability, citations, sentiment, and recommendation position require continuous programmatic measurement.
Step-by-Step Technical Setup and Firewall Configuration
Most indexing failures occur not inside robots.txt, but at the edge security layer. When you allow OAI-SearchBot in robots txt, Cloudflare, Akamai, Fastly, or AWS CloudFront may still intercept and drop OpenAI’s crawler requests before they ever reach your origin server. Follow these precise operational steps to guarantee end-to-end transport delivery:
Step 1: Configure Edge CDNs and Bot Management
If your site sits behind Cloudflare or AWS WAF, default "AI Scraper and Crawler Blocking" toggles will automatically block OAI-SearchBot requests alongside common scraping bots.
- Cloudflare WAF Custom Rule:
- Navigate to Security → WAF → Custom Rules.
- Create a rule named
Bypass-OAI-SearchBot. - Set expression:
(http.user_agent contains "OAI-SearchBot"). - Action:
Skip→ SelectWAF Managed Rules,Bot Management, andRate Limiting.
- Akamai Client Reputation:
- Add
OAI-SearchBotuser-agent pattern exceptions to Bot Manager Standard Rules. - Set condition to prevent triggering Managed Challenge or Interstitial CAPTCHA pages.
- Add
Step 2: Validate Reverse DNS (rDNS) and IP Prefixes
OpenAI publishes dedicated IP blocks and supports automated DNS verification. Never rely solely on user-agent strings for critical internal routing, as user agents can be spoofed. However, when whitelisting OpenAI traffic in your origin iptables or cloud security groups, configure your systems to accept traffic from OpenAI’s published CIDR ranges.
OpenAI provides its official egress IP ranges via public JSON feeds:
- Search Bot egress list:
https://chatgpt.com/searchbot-ip-ranges.json
Verify incoming requests on Linux/Nginx hosts using host or dig reverse DNS lookups:
host 20.171.206.124
# Expected return ends in: oai-searchbot.crawl.openai.com.
If the forward lookup matches the reverse lookup, the request is authentic.
Step 3: Configure Origin Server Headers
Ensure your web server (Nginx, Apache, or Caddy) does not send conflicting security headers. A common issue is an automated server configuration injecting X-Robots-Tag: noindex, nofollow into HTTP response headers for unknown user-agents.
Inspect your Nginx server block to ensure OAI-SearchBot receives normal indexing headers:
# Example Nginx site configuration
location / {
    # Ensure no automated noindex headers block search bots
    add_header X-Robots-Tag "all" always;
    try_files $uri $uri/ /index.php?$args;
}
How do you verify the rule after publishing?
A robots.txt update is incomplete until the deployed edge response is thoroughly tested. Use this five-step verification sequence:
-
Fetch the Live Production File
Open your command line and fetch the live URL directly:curl -I -A "Mozilla/5.0" https://www.example.com/robots.txtConfirm an HTTP
200 OKresponse withContent-Type: text/plain. Ensure CDN caches have cleared and the file is not serving stale cache versions. -
Simulate the Crawler Request via cURL
Emulate an exact OAI-SearchBot fetch against your homepage and subpages:curl -i -A "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/120.0.0.0 Safari/537.36 (Search; +https://openai.com/searchbot)" https://www.example.com/Ensure you do not receive a
403 Forbidden,401 Unauthorized, or a302 Foundredirecting to a Cloudflare Turnstile challenge. -
Check Multi-Host and Protocol Parity
Rules deployed onhttps://www.example.com/robots.txtdo not governhttps://example.com/or application subdomains likehttps://app.example.com/robots.txt. Test every host serving search-relevant landing pages. (developers.google.com) -
Verify Deep-Path Specificity
Test high-value transactional URLs, documentation guides, and product categories. If you have generic disallow directives such asDisallow: /api/orDisallow: /assets/, ensure your client-side rendered Single Page Application (SPA) scripts and dynamic assets are not accidentally blocked from being rendered. -
Review Server Access Logs
Filter origin server logs for crawler presence:grep "OAI-SearchBot" /var/log/nginx/access.log | awk '{print $1, $7, $9}'Confirm that recent hits return HTTP
200or304status codes rather than4xxor5xxerrors.
The access chain most teams overlook
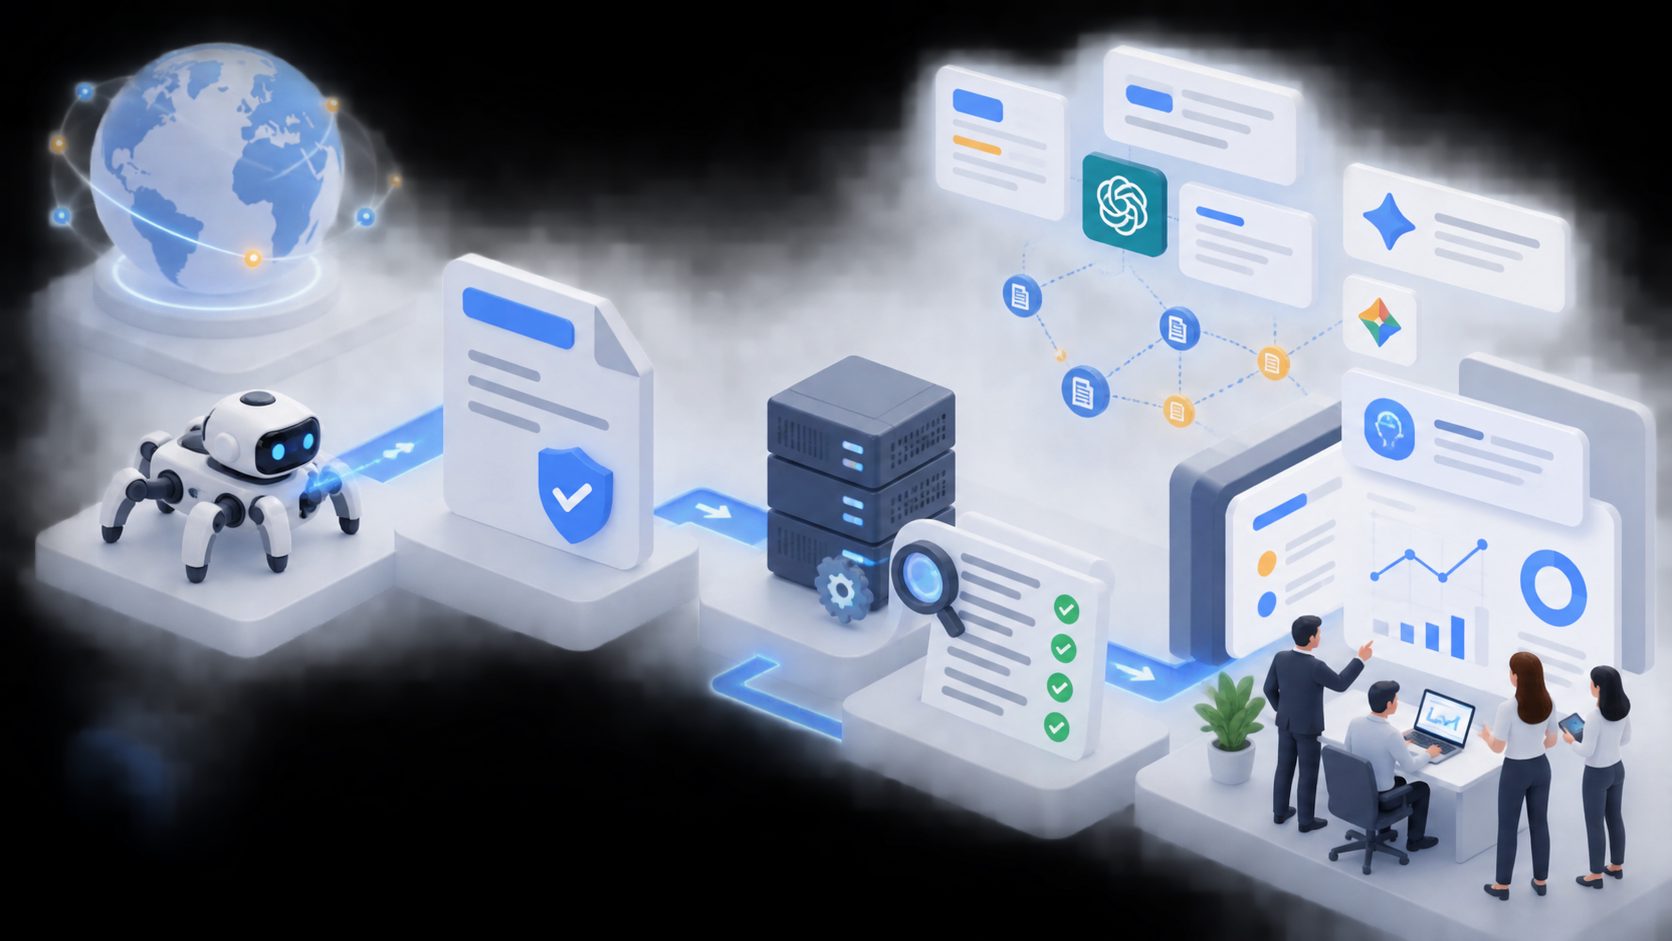
A comprehensive diagnostic model highlights where crawls break down:
robots.txt permission → DNS and TLS negotiation → CDN/WAF challenge checks → Origin application response → Page DOM rendering → RAG vectorization
A permissive robots.txt file only satisfies stage one. If Cloudflare, Akamai, or custom rate-limiting middleware blocks an incoming OpenAI IP pool with a 403 Forbidden, the crawler fails. OpenAI notes that aggressive WAF thresholds, geo-blocking policies, and JavaScript challenges are the top reasons verified publisher content fails to populate ChatGPT Search. (help.openai.com)
Enterprise Implementation Case Study: Resolving a 0% Indexation Rate
To illustrate real-world execution, consider the deployment scenario of a mid-market B2B HR software company with 25,000 indexable URLs.
The Problem
Despite having published extensive industry salary benchmarking reports, the company was completely absent from ChatGPT Search answers for commercial comparison queries. Meanwhile, their primary competitor was consistently referenced as the primary authority source.
Root Cause Audit
An engineering audit uncovered two critical oversights:
- The company’s
robots.txtcontained a catch-all block:User-agent: * Disallow: /Specific allow directives were only declared for
GooglebotandBingbot. Because OAI-SearchBot was unlisted, it defaulted to the wildcard disallow. - The company utilized an edge security rule blocking requests originating outside North America. Several of OpenAI’s distributed crawler IP ranges were identified as European data center transit nodes, triggering instant 403 drops.
The Remediation Sequence
The infrastructure team applied a clean rewrite:
User-agent: OAI-SearchBot
Allow: /
Disallow: /staging/

User-agent: GPTBot
Disallow: /

User-agent: *
Allow: /
Disallow: /staging/
Simultaneously, the security operations team created an explicit IP and user-agent bypass policy on their edge security stack, exempting the verified search bot from geographic blocking and JS-challenge tiers.
The Results
- Day 3: Nginx logs verified the first successful deep crawl by
OAI-SearchBot, recording over 14,000 successfully retrieved URLs with an average response time of 180ms. - Day 14: Across a monitored cluster of 50 relevant conversational prompts, the domain went from 0% citation visibility to appearing in 32% of generated answers.
- Day 30: ChatGPT Search referral sessions in web analytics increased from 42 sessions/month to over 1,950 highly qualified organic sessions.
To evaluate how effectively your brand ranks against category alternatives after fixing technical crawl blocks, apply our brand visibility benchmarking guide across target conversational prompts.
Does allowing OAI-SearchBot guarantee ChatGPT citations?
No. Allowing OAI-SearchBot in robots txt removes the technical access barrier, but it does not guarantee that ChatGPT will index, cite, or prioritize your content in answers. OpenAI’s documentation clarifies that crawler access is merely a discovery prerequisite, not a ranking assurance. (developers.openai.com)
Once accessibility is verified, your content must satisfy core algorithmic retrieval signals:
- Information Density & Fast Answers: Place clear, factual answers within the initial 200 words of the page. Large Language Models emphasize direct semantic matches early in document text.
- Structured Data and Data Tables: Wrap technical specifications, product pricing, and comparative criteria in standard HTML tables or JSON-LD schema.
- Named Entity Consistency: Ensure your brand name, core products, and leadership bios are described consistently across external sources, review platforms, and your own domain.
- Domain Authority and External Citations: AI models prioritize answers corroborated by multiple trusted sources across the open web.
- Self-Contained Content Architecture: Break long pages into semantically complete, distinct sub-sections using informative H2 and H3 tags.
For enterprise teams, technical crawlability must be connected directly to buyer intent. The prompt gap analysis framework for B2B brands provides a practical methodology for tracking high-intent buyer prompts where your product is missing or misrepresented.
Should you use noindex instead of robots.txt?
Choose the mechanism that directly corresponds to your security and indexation goals:
| Technical Objective | Recommended Mechanism | Mechanism Behavior |
|---|---|---|
| Stop crawler bandwidth / resource consumption | robots.txt Disallow |
Halts crawler request before page download begins |
| Remove a crawled page from search results | <meta name="robots" content="noindex"> |
Downloads page, parses DOM, omits URL from search index |
| Safeguard sensitive or private customer data | Authentication / SSO / Paywall | Requires secure session; strictly prohibits public access |
| Prevent AI training while maintaining search presence | Separate OAI-SearchBot and GPTBot |
Granular policy controlling retrieval vs training use cases |
| Control dynamic rendering parameters | X-Robots-Tag HTTP header |
Transmits indexing directives on non-HTML assets (PDF, JSON) |
Robots.txt is not a security protocol. The Robots Exclusion Protocol defines voluntary instructions for well-behaved crawlers, but it does not encrypt files, restrict access, or prevent a URL from appearing without a snippet if referenced elsewhere on the internet. As Google and the IETF confirm, noindex or strict authentication controls are required if content must be kept confidential or entirely excluded from search engines. (rfc-editor.org)
Common questions about OAI-SearchBot
Does Allow: / permit every crawler?
No. Directives placed under User-agent: OAI-SearchBot apply solely to OpenAI’s search retrieval crawler. Other automated bots will ignore that block and evaluate their own specific user-agent blocks or fall back to the generic User-agent: * section.
Is OAI-SearchBot the same as ChatGPT-User?
No. OAI-SearchBot is an automated background crawler responsible for building the ChatGPT Search discovery index. ChatGPT-User is triggered in real-time when an active end user asks ChatGPT to visit, summarize, or read a specific URL during a conversation. Directives managing search indexation do not control interactive browsing sessions. (developers.openai.com)
How long does a robots.txt change take to affect ChatGPT Search?
OpenAI indicates that their systems process robots.txt updates within approximately 24 hours. However, real-time edge caches and search index refreshes may vary based on your domain’s crawl frequency and baseline authority. (developers.openai.com)
Can I allow OAI-SearchBot and block GPTBot?
Yes. Declaring independent blocks (User-agent: OAI-SearchBot Allow: / paired with User-agent: GPTBot Disallow: /) is the industry-standard method to preserve search engine optimization visibility while declining to license data for model training sets.
What should I measure after allowing the crawler?
Once technical crawl success is validated via server logs, you must track conversational search outcomes:
- Brand Citation Frequency: How often your domain URL is hyperlinked inside synthesized responses.
- First-Mention Ranking: Where your brand appears when users ask for comparative recommendations.
- Sentiment & Accuracy: Whether the AI describes your software, services, or pricing accurately.
- Competitor Share of Voice: The proportion of conversational queries dominated by competitors.
MaxAEO monitors these critical generative discovery signals across eight leading AI search engines with daily updates, providing automated tracking for brand mentions, citation sources, recommendation positioning, and competitive visibility shifts.