作者:maxaeo.ai|发布日期:2025-01-15|更新日期:2025-01-15
An AI search share of voice tool measures what percentage of AI-generated answers mention, cite, or recommend your brand versus competitors — across engines like ChatGPT, Perplexity, and Gemini. Unlike traditional SEO share of voice, it captures what AI assistants actually say to buyers, not just where you rank on a results page. This guide breaks down how SOV is calculated in AI search, which dimensions matter most, and a practical framework for choosing the right tool.
What Is Share of Voice in AI Search?
Share of voice (SOV) in AI search is the proportion of relevant AI-generated answers in which your brand is mentioned, cited, or recommended, compared to the total mentions across all tracked brands in your category.
In classic SEO, SOV is a proxy: impressions weighted by ranking position and search volume. In AI search, the output is a synthesized answer, so the calculation shifts to conversational presence:
AI SOV = (answers mentioning your brand ÷ all answers mentioning any tracked brand) × 100
But a single number hides most of the story. A brand mentioned 40% of the time as a dismissive footnote is in a worse position than a brand mentioned 25% of the time as the top recommendation. That’s why serious measurement needs multiple dimensions.
The Four Dimensions That Make AI SOV Meaningful
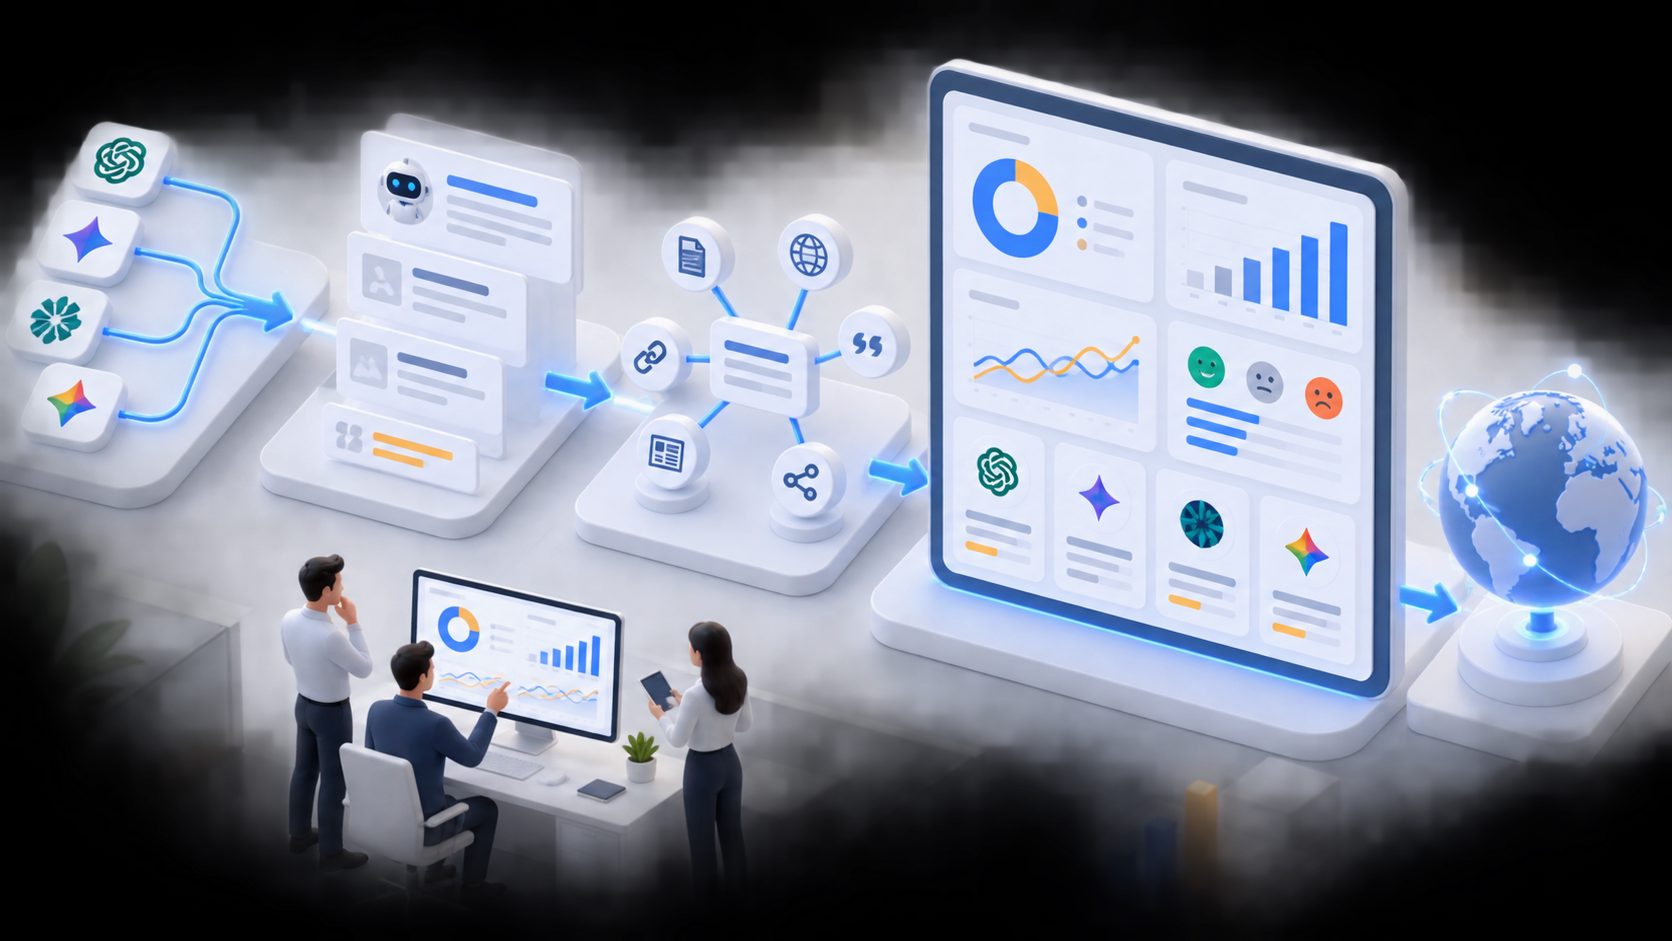
Based on our experience monitoring brand visibility across eight AI engines, raw mention share alone misleads CMOs. A defensible AI SOV framework includes four layers:
1. Mention rate
The baseline: how often your brand appears at all when buyers ask category-relevant prompts. Track it per engine — a brand can hold 35% mention share in ChatGPT and under 5% in Perplexity, because each engine draws on different retrieval sources.
2. Recommendation position
Where in the answer you appear. Being the first product named in "best CRM for startups" carries different weight than the fifth name in a list. Average recommendation position is often a better predictor of downstream traffic than raw mention count.
3. Sentiment and framing
AI engines don’t just mention brands — they characterize them. Sentiment analysis distinguishes "recommended," "mentioned neutrally," and "mentioned with caveats" (e.g., "popular but pricey"). Our AI brand sentiment monitoring framework covers how to act on these signals.
4. Citation source composition
Which domains AI engines cite when they recommend you — review sites, comparison pages, Reddit threads, documentation. This is the most actionable dimension: citations tell you which assets to strengthen to move your SOV.
How AI Search SOV Is Calculated in Practice
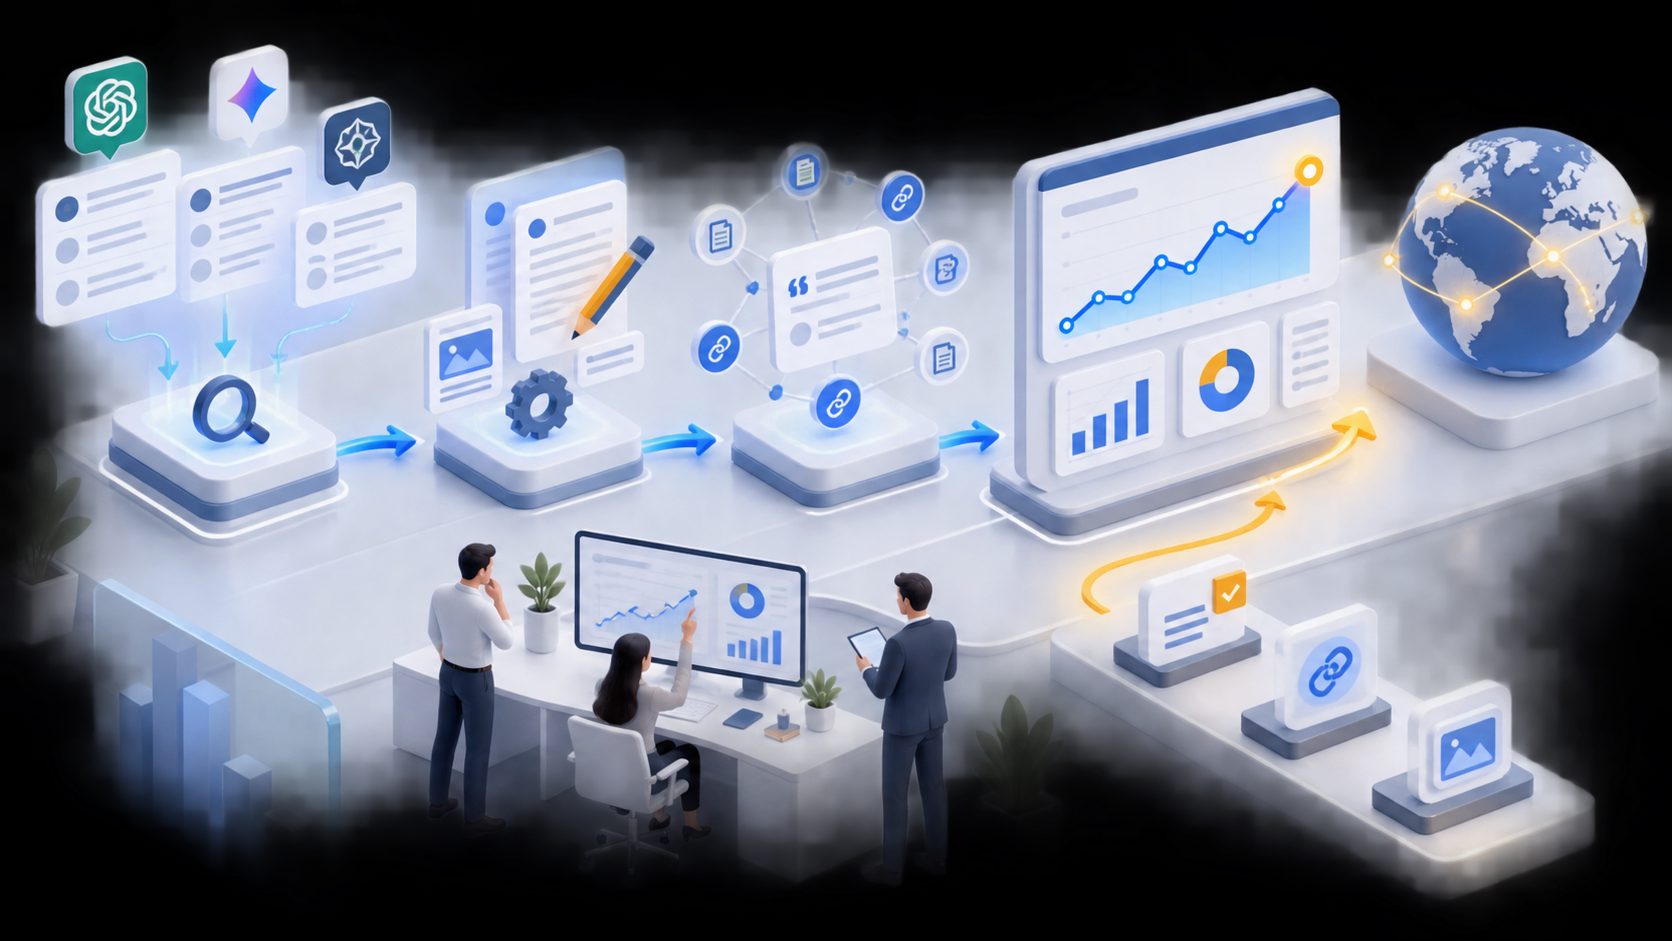
A rigorous AI SOV measurement follows a repeatable method. Any tool you evaluate should make this methodology transparent:
- Define a prompt set. Start with 20–50 buyer-intent prompts ("best tools for X," "X vs Y," "alternatives to Z"). Many teams convert their existing SEO keyword list into conversational prompts.
- Run prompts across multiple engines. Results vary dramatically between ChatGPT, Gemini, Perplexity, Claude, Copilot, and Google AI Overviews. Single-engine monitoring gives a distorted picture.
- Repeat on a fixed cadence. AI answers change as models retrain and retrieval indexes update. Daily runs with trend lines are the standard for decision-grade data; one-off spot checks are noise.
- Extract brand-level metrics. For each answer: which brands appear, in what order, with what sentiment, citing which sources.
- Compute share. Divide your brand’s metrics by the total across you and your tracked competitors, per engine and per prompt cluster.
The output should be a trend line, not a snapshot — and ideally a positioning view showing you versus rivals. Our guide on AI search visibility share of voice tools walks through how leading platforms compute these numbers differently.
Buyer’s Checklist: Evaluating an AI Search Share of Voice Tool
Not every tool marketed as "AI visibility tracking" actually measures share of voice. Use these criteria to separate dashboards from data:
| Criterion | What to look for | Red flag |
|---|---|---|
| Engine coverage | 5+ engines including ChatGPT, Perplexity, Gemini, AI Overviews | ChatGPT only |
| Update frequency | Daily prompt runs with trend lines | Weekly or on-demand only |
| Competitor benchmarking | SOV computed against named rivals, per engine | Your brand in isolation |
| Position tracking | Average recommendation position, not just mention yes/no | Flat mention counts |
| Sentiment | Per-answer sentiment with raw answer storage | Aggregate scores with no source text |
| Citation tracing | Exact domains/URLs cited per answer | "Citation rate" without sources |
| Prompt management | SEO keyword → prompt conversion, intent clustering | Fixed generic prompt lists |
| Method transparency | Stored raw answers you can audit | Black-box "visibility score" |
Two pitfalls we’ve seen repeatedly in tool evaluations:
- Averages that hide variance. A 30% SOV that is 60% on ChatGPT and 0% on Perplexity requires very different action than a flat 30%. Insist on per-engine breakdowns — a cross-platform AI monitoring framework helps structure this.
- No gap diagnosis. Knowing competitors beat you is step one. The useful tools show which prompts rivals win and you don’t, and which sources drive those wins — see how competitor AI mention tracking exposes those gaps.
From Measurement to Action: Closing the SOV Gap
Data without a fix loop is a reporting expense. Once your AI search share of voice tool surfaces a gap, the remediation path is usually one of three plays:
Citation building. If rivals are cited from comparison pages and review sites you’re absent from, that’s a distribution problem, not a content problem. Prioritize presence on the specific domains AI engines already cite in your category.
AI-ready content restructuring. Answers favor content with clear definitions, comparison tables, and verifiable claims. Structured, extractable content gets cited; marketing copy gets ignored.
Accuracy correction. Sometimes low SOV stems from outdated or wrong information the AI repeats. Fixing the underlying source material is faster than publishing new content — our playbook for correcting wrong or missing AI recommendations covers the diagnosis sequence.
Then measure again. SOV movement typically shows in trend lines within weeks of citation and content changes, which is why daily tracking beats quarterly audits.
How MaxAEO Approaches AI Share of Voice
MaxAEO is an AI search visibility platform that computes share of voice across 8 AI engines — including ChatGPT, Gemini, Perplexity, Claude, Copilot, Grok, Google AI Mode, and Google AI Overviews — with daily prompt runs and trend lines. It tracks mention rate, average recommendation position, sentiment, and exact citation sources, benchmarked against your chosen competitors.
You can start with a free diagnostic report: enter your domain at maxaeo.ai and get your mention rate, ranking, sentiment, and competitor comparison in minutes — no code installation or technical integration required. Paid plans start at $19/month for teams that want continuous daily monitoring, and you can convert existing SEO keywords into monitored prompts directly.
Frequently Asked Questions
What is a good share of voice in AI search?
There is no universal benchmark yet because the field is young. A practical target: aim to match or exceed your traditional search market share, and focus on trend direction. Moving from 10% to 20% mention share in your category over a quarter is a stronger signal than any absolute number.
How is AI SOV different from SEO share of voice?
SEO SOV estimates visibility from rankings and search volume. AI SOV measures actual presence inside generated answers — whether you’re named, where, how you’re described, and what sources are cited. The unit of analysis is the answer, not the results page.
Which AI engines should a share of voice tool cover?
At minimum: ChatGPT, Perplexity, Gemini, and Google AI Overviews, since these carry the most buyer research traffic. Coverage of Claude, Copilot, Grok, and DeepSeek matters increasingly. Single-engine tools systematically mislead.
Can I measure AI share of voice manually?
You can run prompts by hand and tally mentions, but it doesn’t scale: answers vary by session, engines update constantly, and you lose trend data. Manual spot checks are useful for validation, not for ongoing measurement.
How often should AI SOV be measured?
Daily is the standard for actionable data, since AI answers shift with model updates and new indexed content. Weekly or monthly sampling smooths out the very movements you need to catch.