By maxaeo.ai | Published 2026-11-08 | Updated 2026-11-08
A GEO platform multi assistant dashboard gives marketing and revenue teams one place to monitor how AI assistants mention, rank, recommend, and cite a brand. Instead of checking ChatGPT, Perplexity, Gemini, and other answer engines manually, teams can compare visibility by prompt, engine, competitor, sentiment, and source.
AI visibility platforms commonly combine prompt tracking, competitor comparisons, source analysis, and trend reporting. However, the key difference is not the number of logos on a dashboard. It is whether the dashboard helps a team explain why visibility differs between assistants and what action to take next.
What is a multi-assistant GEO dashboard?
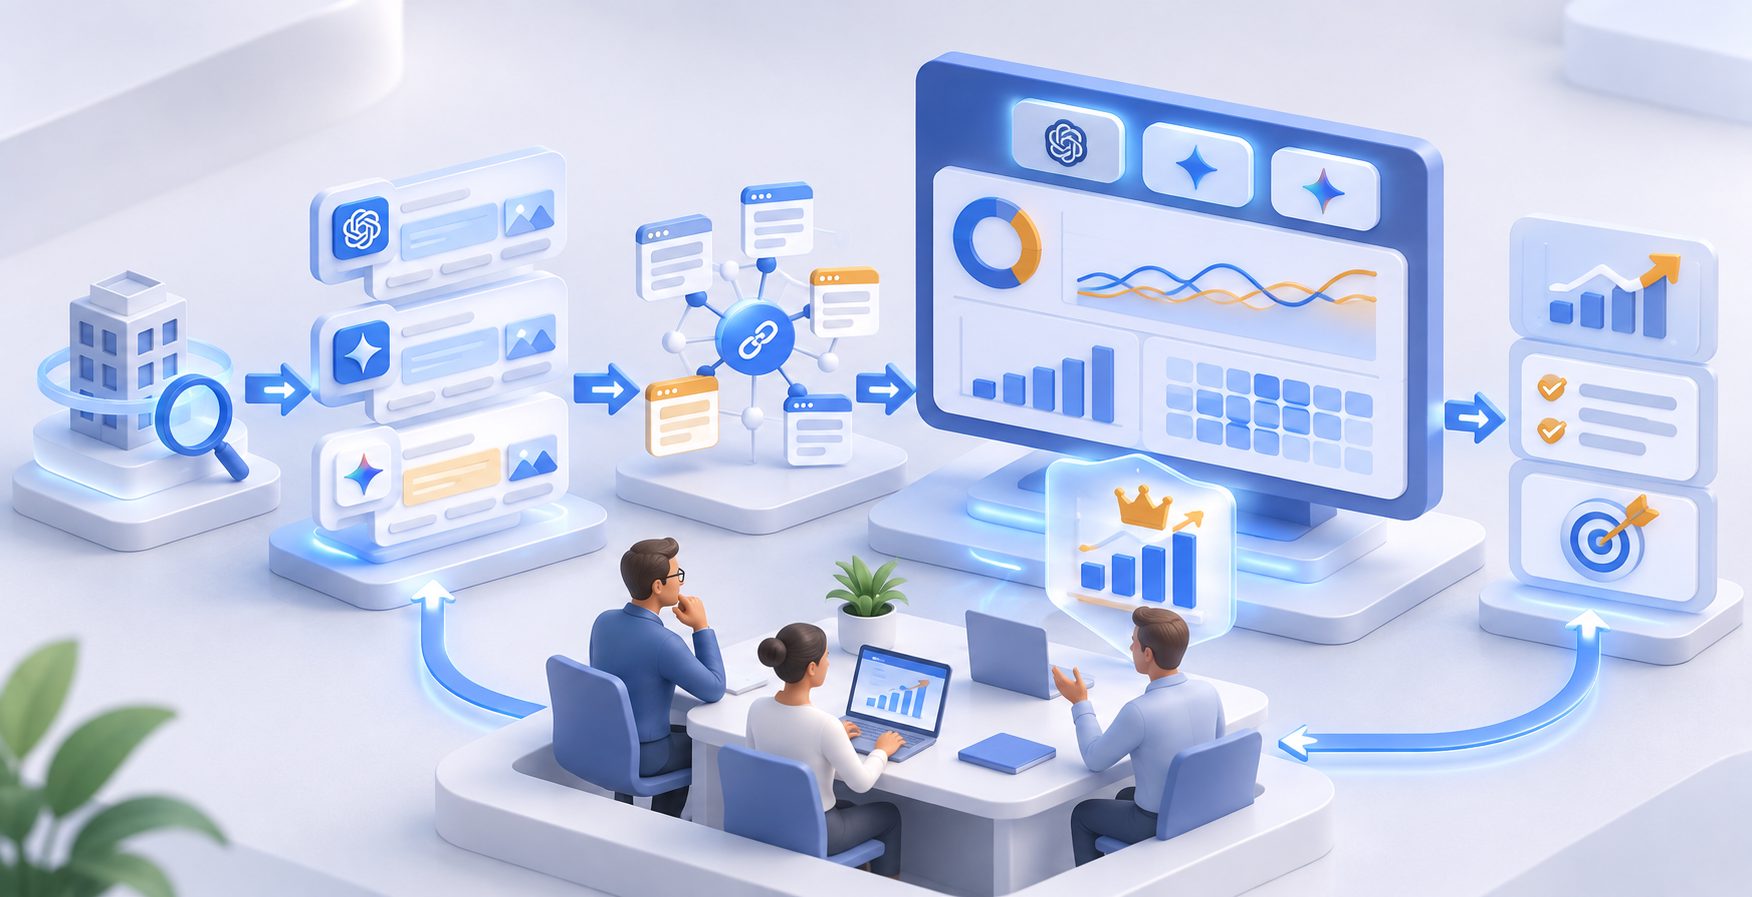
A multi-assistant GEO dashboard is a monitoring workspace that measures brand performance across several generative search and answer platforms. It normally tracks whether a brand appears, where it appears, how it is described, and which sources influence the answer.
The most useful dashboards separate at least five signals:
- Mention rate: How often the brand appears in relevant answers.
- Recommendation position: Where the brand appears in a list or comparison.
- Citation coverage: Which pages or domains are cited.
- Sentiment and positioning: Whether the assistant describes the brand positively, neutrally, or negatively.
- Competitive share of voice: How often competitors appear in the same buyer prompts.
This matters because an answer engine is not simply a traditional search results page. An assistant may recommend a brand without linking to its homepage, cite a third-party review instead of the brand’s website, or describe two competitors differently for the same prompt.
Platforms appearing prominently for this category emphasize unified visibility reporting, competitor analysis, prompt-level answers, and citation discovery. (aeo-rank.ai)
Why one assistant is not enough
ChatGPT, Perplexity, Gemini, Claude, Copilot, and Google AI experiences can produce different answers to the same question. They may retrieve different sources, apply different ranking logic, or summarize the same brand using different language.
A single-assistant report can therefore create a misleading conclusion. A brand may be visible in Perplexity because it is frequently cited by review websites, while Gemini may surface more brand-owned or Google-connected sources. ChatGPT may mention the brand but place it below several competitors.
A cross-assistant dashboard should show these differences rather than compressing everything into one unexplained score.
The three-layer view
A practical way to read multi-model data is to divide it into three layers:
- Consensus: The brand appears across several assistants for the same buyer intent.
- Engine-specific strength: The brand performs well in one assistant but not others.
- Source dependency: Visibility depends heavily on one review site, directory, Reddit thread, comparison page, or technical document.
This framework is an original diagnostic model for interpreting AI visibility. It prevents teams from treating every mention as equal. Consensus suggests broader discoverability; engine-specific strength suggests a platform or source gap; source dependency creates concentration risk.
Which metrics should the dashboard include?
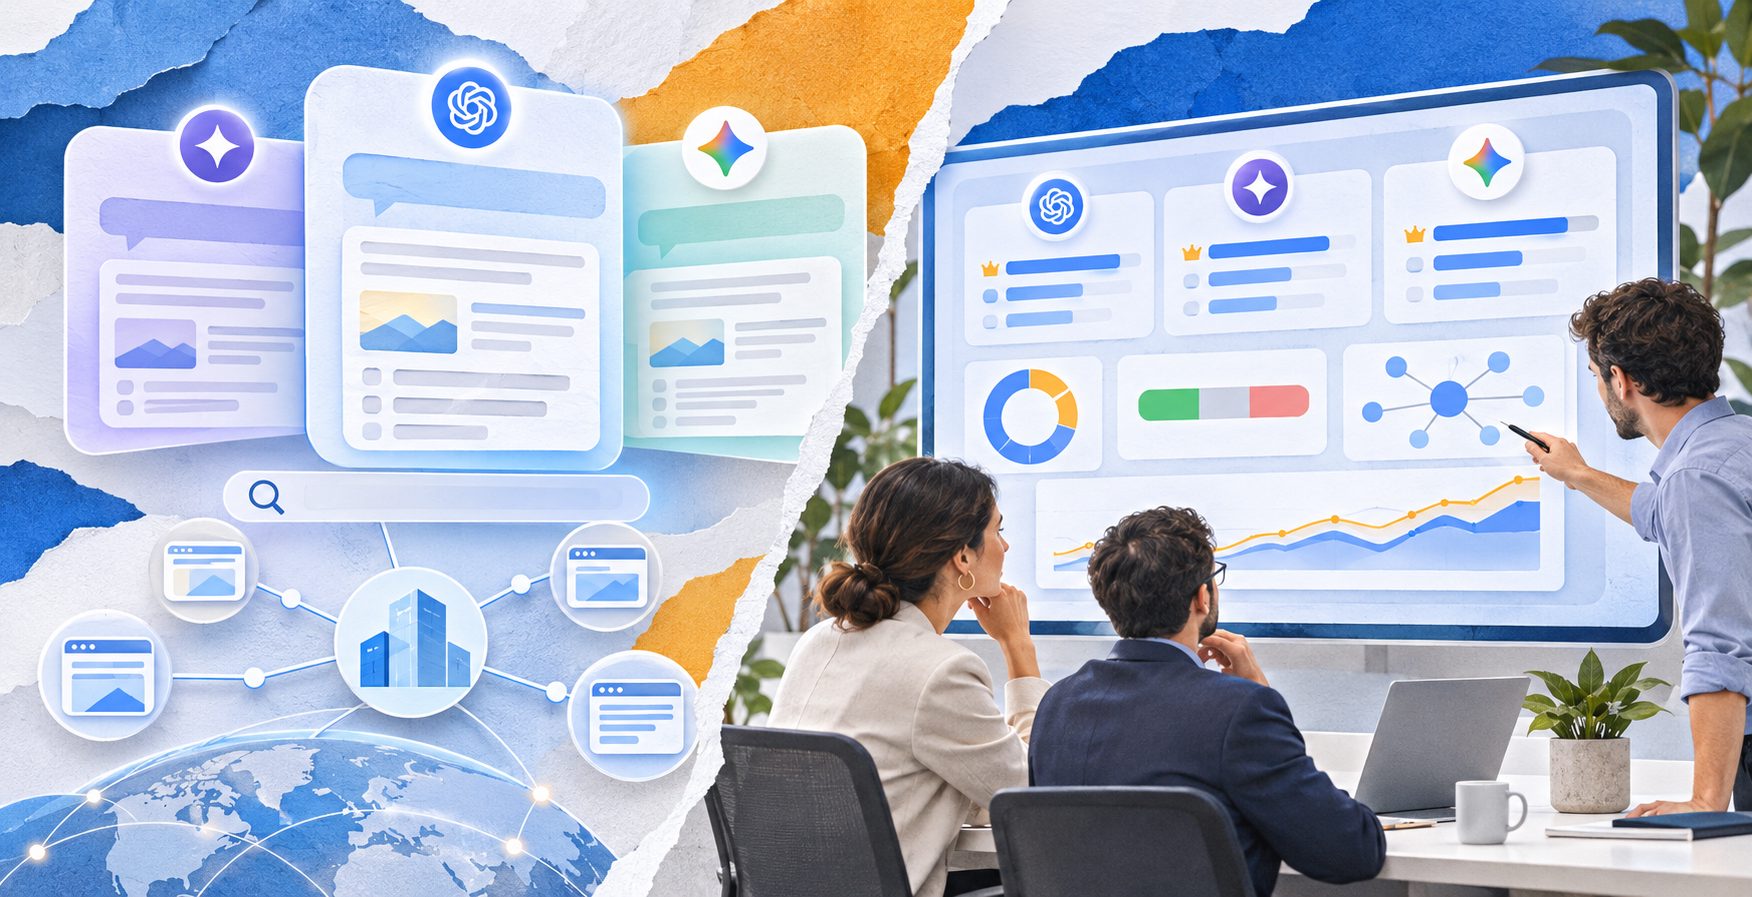
The best dashboard depends on the decisions your team needs to make. For most SaaS and technology brands, the following measurement structure is more useful than a single visibility score.
| Dashboard area | Question it answers | Useful output |
|---|---|---|
| Brand visibility | Does AI mention us for buyer prompts? | Mention rate and trend |
| Recommendation ranking | How prominently are we presented? | Average position and competitor position |
| Citation tracking | What sources support the answer? | Cited domains, pages, and source types |
| Sentiment analysis | How does AI describe us? | Positive, neutral, or negative framing |
| Prompt segmentation | Where are we strong or weak? | Use-case, category, comparison, and solution prompts |
| Engine comparison | Does performance vary by assistant? | Heat map by model |
| Competitor intelligence | Who receives more AI visibility? | Share-of-voice comparison |
| Action planning | What should change next? | Prioritized content and source recommendations |
The dashboard should preserve the original AI answers, not only aggregate them. Without the raw answer, a marketer cannot verify whether a mention was accurate, whether a competitor was preferred, or whether a citation actually supported the claim.
How to evaluate a GEO platform dashboard
Use the following five-part test before selecting a platform.
1. Coverage
Check which assistants are monitored and whether the platform distinguishes them clearly. MaxAEO monitors visibility across eight AI engines, including ChatGPT, Gemini, Perplexity, Claude, Copilot, Grok, Google AI Mode, and Google AI Overviews.
Coverage should also include the markets and languages your buyers use. MaxAEO supports daily monitoring for English and Chinese markets, which is useful for teams operating across regions.
2. Prompt quality
A dashboard is only as useful as the prompts behind it. Include several prompt classes:
- Category discovery: “What are the best tools for…?”
- Problem-solving: “How can a SaaS team improve…?”
- Comparison: “A versus B for…”
- Use-case selection: “Which platform is best for…?”
- Trust and risk: “Is this company reliable for…?”
A strong workflow converts existing SEO keywords into natural buyer questions, then groups them by intent instead of treating every keyword as an isolated measurement.
3. Evidence depth
Prioritize platforms that show the full answer, cited pages, cited domains, and the sentence where the brand appears. A percentage without evidence is difficult to act on.
For example, a low mention rate may result from weak category relevance, poor third-party coverage, inaccurate brand facts, or a competitor owning the most cited comparison pages. These problems require different fixes.
MaxAEO’s AI search visibility benchmarking framework explains why benchmarking should connect visibility metrics with competitors, prompts, and sources.
4. Competitive context
A brand’s absolute visibility is less meaningful without a comparison set. Track competitors in the same prompts and compare:
- Mention frequency
- Average recommendation position
- Sentiment
- Citation sources
- Engine-specific performance
- Changes over time
MaxAEO provides competitor comparisons for mentions, rankings, sentiment, and citation sources, allowing teams to identify where competitors are being discovered or trusted.
5. Operational usefulness
The dashboard should lead to a repeatable workflow:
- Identify prompts where competitors appear and your brand does not.
- Read the actual answers and classify the visibility gap.
- Find the sources repeatedly cited by assistants.
- Improve relevant pages, proof points, documentation, or comparison content.
- Re-run the same prompts and monitor the trend.
A GEO dashboard should support decision-making, not automatically publish content or replace editorial judgment.
How to use the dashboard for weekly reporting
A practical weekly report can fit on one page:
- Overall mention-rate trend
- Top five prompts with improved visibility
- Top five prompts with lost visibility
- Competitor movement
- New or lost citation domains
- Sentiment changes
- Three recommended actions
The most valuable observation is often not “visibility increased.” It is a statement such as: “The brand is mentioned more often, but competitors still occupy higher recommendation positions because comparison pages from two external domains are cited more frequently.”
That explanation connects a metric to an action. It also helps SEO, content, PR, product marketing, and sales teams work from the same evidence.
For a deeper implementation model, see this guide to cross-model AI search optimization.
Common questions
Is a GEO dashboard the same as an SEO rank tracker?
No. An SEO rank tracker measures positions in traditional search results. A GEO dashboard measures how AI assistants describe, recommend, and cite a brand in generated answers. The two systems can inform each other, but they are not interchangeable.
Should teams track prompts or keywords?
Track prompts. Keywords are useful inputs, but buyers ask complete questions that reveal context, alternatives, constraints, and purchase intent. A prompt library produces more actionable AI visibility data.
How often should AI visibility be measured?
Daily monitoring is useful for trend detection, but individual answers can vary. Interpret changes through repeated observations, prompt groups, and engine-level patterns rather than reacting to one answer.
What should a SaaS company monitor first?
Start with category, use-case, alternative, and competitor-comparison prompts. These are closer to vendor selection than branded queries and can reveal whether buyers encounter the company before they know its name.
How can a team start without internal data?
A basic diagnostic can begin with a brand name, website, competitors, and buyer prompts. MaxAEO offers a free AI visibility diagnosis that reports brand mentions, ranking, sentiment, and competitor comparisons without requiring internal revenue data or customer lists. Run a free AI visibility check.
Conclusion
A GEO platform multi assistant dashboard is most valuable when it turns fragmented AI answers into comparable evidence. The essential capabilities are cross-engine coverage, prompt-level monitoring, raw-answer access, competitor benchmarking, citation tracking, sentiment analysis, and clear next steps.
The right goal is not to chase one universal score. It is to understand where AI assistants agree, where they differ, which sources shape their recommendations, and which improvements can strengthen the brand’s presence across buyer questions.