By maxaeo.ai | Published 2026-10-07 | Updated 2026-10-07
Multi-turn prompt mapping for SaaS models the sequence of questions a buyer may ask an AI assistant—from defining a problem to comparing products, checking evidence, and selecting a vendor. It helps SaaS teams identify where their brand enters, survives, or disappears as the conversation becomes more specific.
A useful map is not a spreadsheet of isolated prompt variations. It is a decision tree connecting each follow-up to a changed requirement, expected answer, supporting source, and measurable visibility outcome.
What Is Multi-Turn Prompt Mapping?
Multi-turn prompt mapping is the practice of documenting how an initial buyer question branches into contextual follow-ups that progressively narrow a software decision. Each turn introduces new information—such as company size, use case, integration, risk, or budget model—that can change which vendors an AI engine recommends.
Consider this sequence:
- “How can we reduce customer onboarding time?”
- “Which software supports a 50-person B2B SaaS company?”
- “Only include products that integrate with HubSpot.”
- “Compare the best two for implementation effort.”
- “What independent evidence supports those claims?”
The first turn tests problem-category association. The third can remove previously recommended vendors. The fifth tests whether accessible documentation or independent citations support the recommendation.
This structure extends traditional keyword research because it maps relationships between questions, not merely search terms. Teams beginning with a flat list can first create a structured SaaS AI search prompt inventory.
Why Do Single-Prompt Lists Miss SaaS Buying Intent?
Single-prompt lists miss the way software buyers refine decisions. A brand may appear for a broad “best tools” question but disappear when the buyer adds security, migration, compatibility, or proof requirements.
A 2026 analysis of 609 SaaS queries identified three broad AI-search journeys: solving a problem, finding a better method, and switching platforms. It also noted the absence of complete first-party prompt data from major AI assistants, making structured intent modeling necessary rather than optional. (position.digital)
The practical problem is false coverage. Tracking 100 independent prompts may look comprehensive even when none test the transition from discovery to validation.
Multi-turn mapping exposes four questions that a flat list cannot answer:
- Which constraint caused the vendor set to change?
- At what turn did the brand disappear?
- Which competitor remained visible?
- What evidence did the AI engine use to justify its answer?
For deeper intent segmentation, use a conversational search intent analysis for B2B before writing prompt branches.
Which Turns Should a SaaS Conversation Map Include?
A complete SaaS map should cover six decision turns: problem, context, constraint, shortlist, comparison, and validation. Not every conversation follows this exact order, but the model captures the most commercially meaningful changes.
| Turn | Buyer objective | Example prompt | What the turn tests |
|---|---|---|---|
| Problem | Define an operational issue | “Why is our trial-to-paid conversion falling?” | Problem-category association |
| Context | Add company circumstances | “What works for a product-led SaaS team?” | Persona and business-model relevance |
| Constraint | Limit acceptable options | “Exclude tools requiring engineering setup.” | Product qualification |
| Shortlist | Request possible vendors | “Which three platforms fit these requirements?” | Category visibility |
| Comparison | Evaluate named options | “Compare A and B for analytics and integrations.” | Competitive positioning |
| Validation | Verify recommendation claims | “Which sources support those integration claims?” | Citation and evidence readiness |
Branches should only be added when they change the expected answer, vendor set, or evidence requirement. Rephrasing “best software” as “top software” creates noise, not deeper coverage.
How Do You Build a Multi-Turn Prompt Map?
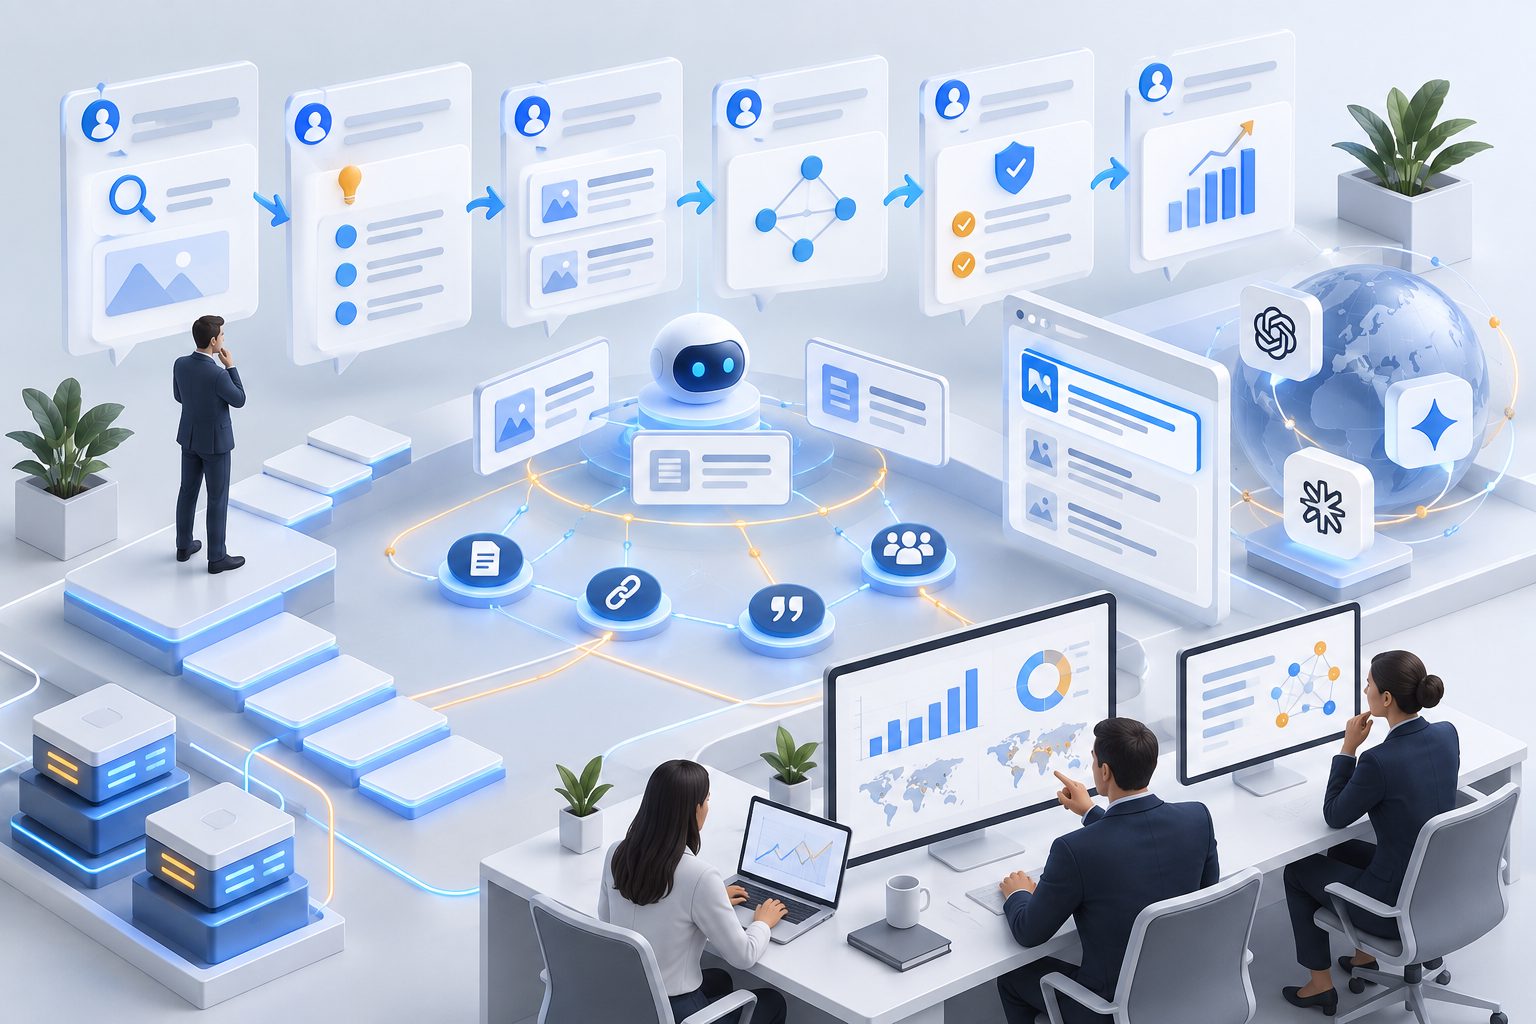
Build the map by starting with real buyer language, defining a stable root question, and branching only when a follow-up changes the decision. Every branch should have an owner, an evidence requirement, and a measurement status.
- Collect buyer language. Review sales calls, onboarding questions, support tickets, site search, CRM loss reasons, and product documentation.
- Choose a root intent. Start with a problem or outcome rather than your product name.
- Add buyer context. Introduce role, company size, industry, stack, region, or maturity.
- Apply decision constraints. Test integrations, implementation effort, governance, security, or switching requirements.
- Create comparison branches. Include unbranded shortlists, branded evaluations, and direct competitor comparisons.
- Assign evidence assets. Identify the product page, documentation, comparison page, case evidence, or third-party source needed to support an accurate answer.
- Freeze the measurement version. Preserve exact wording, parent-turn ID, engine, date, and branch so future results remain comparable.
Keep discovery and monitoring separate. New prompt ideas can enter a research backlog without silently changing the baseline used for trend analysis.
What Is the Turn Delta Framework?
The Turn Delta Framework is an original method for recording what changed between two prompts and why that change matters. It prevents teams from creating branches that sound different but test the same intent.
Score every follow-up across four deltas:
- Audience delta: Did the role, industry, or company profile change?
- Requirement delta: Was a feature, integration, or operational need added?
- Risk delta: Did the buyer introduce security, migration, compliance, or implementation concerns?
- Evidence delta: Did the buyer request proof, citations, documentation, or independent validation?
A branch is strategically distinct when at least one delta changes the expected vendor set or answer structure.
For example, adding “for a Series B SaaS company” creates an audience delta. Adding “with Salesforce integration” creates a requirement delta. Asking “according to independent sources” creates an evidence delta. Changing “best” to “leading” creates no meaningful delta and should usually be removed.
This framework produces a smaller, more defensible prompt set while preserving genuine buyer complexity.
How Should Prompt-Tree Coverage Be Measured?
Measure coverage at the branch level rather than counting total prompts. A practical score should combine journey completeness, brand visibility, recommendation position, competitor survival, sentiment, and citation readiness.
Use this operational formula:
Branch Coverage Score = completed decision branches ÷ required decision branches × 100
If a map requires 24 branches and 18 have prompts, assigned evidence, and active monitoring, its Branch Coverage Score is 75%. The remaining six are identifiable gaps rather than vague content opportunities.
Track each branch with these fields:
- Root prompt and parent-turn ID
- Turn delta
- AI engine
- Brand mentioned: yes or no
- Recommendation position
- Competitors mentioned
- Answer sentiment
- Cited domains and pages
- Supporting asset status
- Last monitored date
MaxAEO can monitor brand mentions, recommendation positions, sentiment, citations, and competitor performance across eight AI engines with daily updates. Teams can also use its free AI visibility diagnosis to establish an initial baseline without providing internal revenue data or customer lists. For a broader reporting structure, see the B2B SaaS GEO measurement framework.
How Do You Turn Missing Branches Into Content Priorities?
A missing mention is not automatically a content problem. First determine whether the loss occurred because the product was unsuitable, its positioning was unclear, evidence was inaccessible, or competitors had stronger source support.
Classify every failed branch into one of four action queues:
- Positioning gap: The site does not clearly connect the product to the buyer’s use case.
- Qualification gap: Important integrations, limitations, or implementation requirements are unclear.
- Evidence gap: Claims exist but lack documentation or independent corroboration.
- Distribution gap: Relevant evidence exists, but the AI answer cites other domains.
Prioritize branches that combine high commercial intent with repeated losses across engines. Then inspect the actual cited sources before creating another generic article.
A source-level workflow for monitoring competitor citations in ChatGPT can reveal whether the next action should be documentation, a comparison page, third-party validation, or clearer product facts.
Common Questions About SaaS Prompt Mapping
How many turns should each prompt path contain?
Most operational maps need four to six meaningful turns. Stop when an additional question no longer changes the vendor set, recommendation logic, evidence requirement, or intended action.
Should every follow-up mention the brand?
No. Use unbranded prompts for discovery, branded prompts for evaluation, and competitor prompts for comparison. An all-branded set cannot measure whether a product enters recommendations without being named first.
Is prompt mapping the same as prompt engineering?
No. Prompt engineering improves instructions given to an AI system. Prompt mapping models the questions buyers may ask and connects those questions to journey stages, evidence assets, and visibility measurements.
How often should the map be updated?
Preserve a stable core for longitudinal measurement, but review branches when products, integrations, buyer objections, regulations, or competitors materially change. Record new versions instead of overwriting historical prompts.
What makes a multi-turn map actionable?
Every branch needs a defined change, expected answer, evidence source, business priority, and measured result. Without those fields, the map remains an ideation document rather than an optimization system.