By maxaeo.ai | Published 2026-10-06 | Updated 2026-10-06
A GEO competitive audit spreadsheet tracks which brands AI engines mention, recommend, and cite for the questions your buyers ask. The template below turns raw answers into comparable metrics, evidence gaps, and prioritized actions—without mistaking a single ChatGPT or Perplexity response for a reliable trend.
What Is a GEO Competitive Audit Spreadsheet?
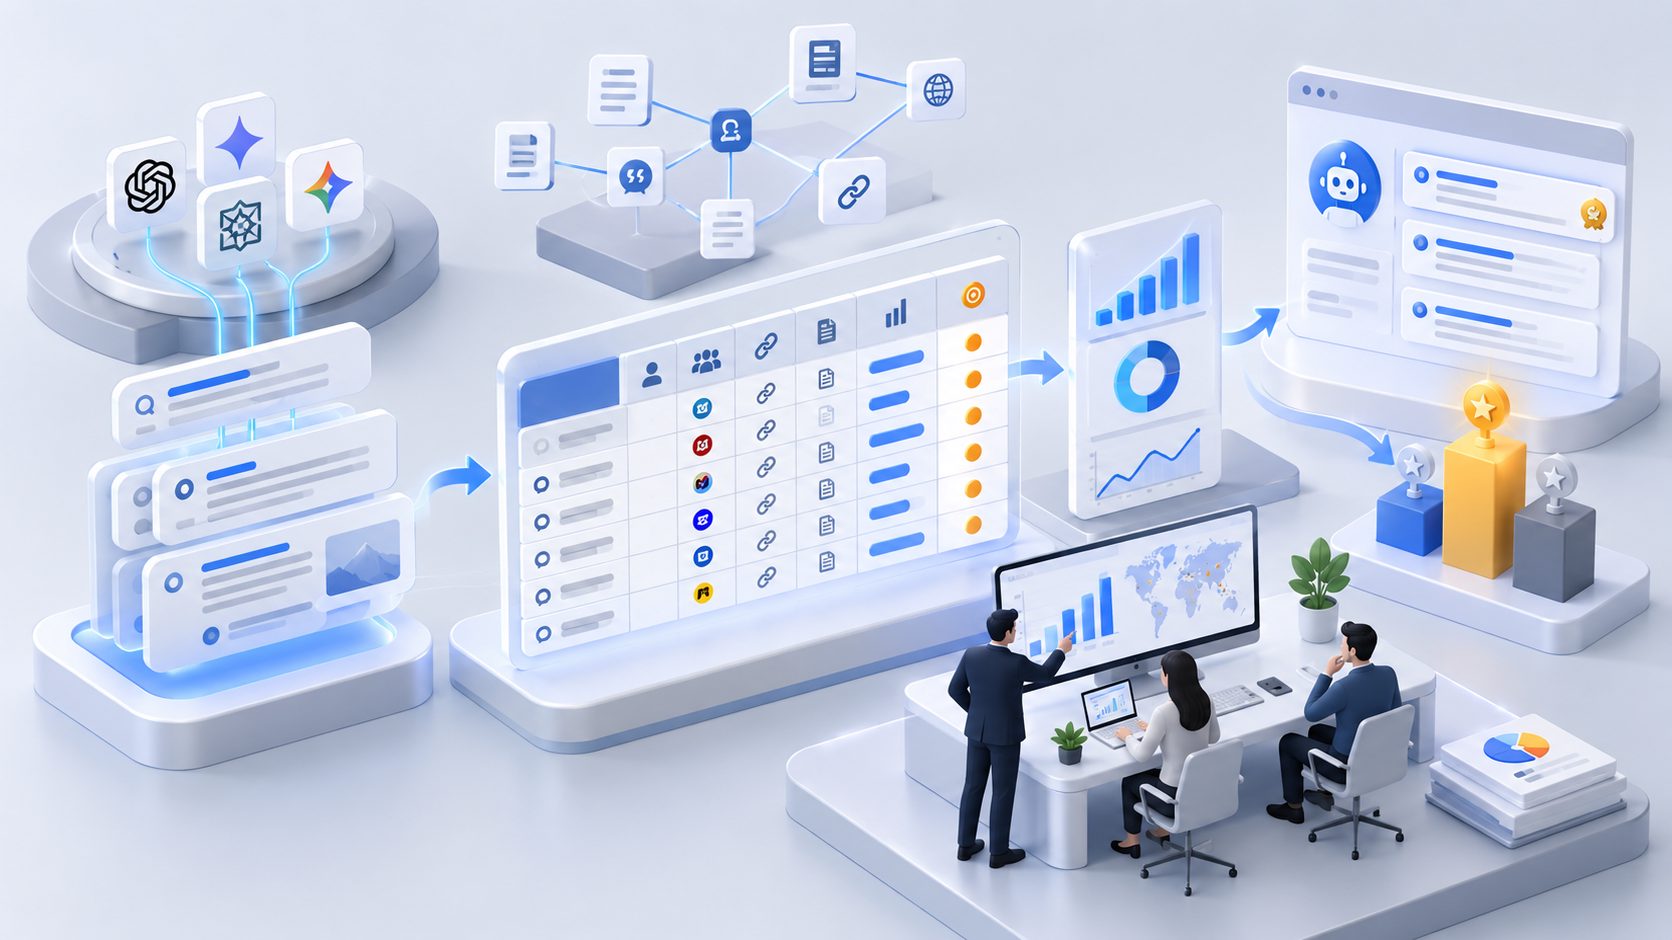
A GEO competitive audit spreadsheet is a structured workbook for comparing brand visibility across generative and answer engines. Unlike a traditional SEO competitor sheet, it records complete AI answers, recommendation positions, cited sources, sentiment, factual accuracy, and changes between repeated runs.
A useful audit answers five questions:
- Which brands appear for high-value buyer prompts?
- How often is each brand mentioned or recommended?
- Which sources support the winning competitors?
- How does each engine describe the brands?
- Which evidence gap should be addressed first?
Repeated testing matters because generated answers can vary by engine, session, and date. Current manual-audit frameworks commonly recommend running a fixed prompt set across at least three engines on multiple days rather than treating one answer as conclusive. (zilwaris.com)
Which Tabs Should the Spreadsheet Include?
The most actionable structure uses six connected tabs. Each tab has one purpose, allowing reviewers to trace every score back to the prompt, answer, and cited page that produced it.
| Tab | Purpose | Essential fields |
|---|---|---|
| Setup | Defines the audit scope | Brand, competitors, market, engines, dates |
| Prompt Inventory | Organizes buyer questions | Prompt ID, intent, funnel stage, importance |
| Answer Log | Preserves each observation | Engine, run, full answer, brands, positions |
| Source Ledger | Maps supporting evidence | Cited domain, URL, source type, supported claim |
| Scorecard | Calculates competitive performance | Mention rate, recommendation rate, share of voice |
| Action Queue | Converts findings into work | Gap, priority score, owner, due date, status |
Begin with 12–24 prompts covering category discovery, use cases, comparisons, alternatives, objections, and purchase validation. The SaaS AI search prompt inventory template provides a broader buyer-journey structure for teams that need to build this list from existing SEO keywords.
What Should You Record for Every AI Answer?
Record one row for every prompt, engine, and run. Combining several answers in one cell makes calculations difficult and prevents reviewers from verifying why a competitor received a score.
Use these columns in the Answer Log:
- Audit date and exact timestamp
- Engine and product surface
- Prompt ID and exact wording
- Buyer stage and business importance
- Run number
- Brand mentioned: yes or no
- Recommendation position
- Competitors mentioned
- Sentiment: positive, neutral, mixed, or negative
- Factual accuracy: accurate, incomplete, outdated, or incorrect
- Cited domains and URLs
- Full raw answer
- Reviewer notes
Keep a citation separate from a recommendation. An engine may cite a company’s documentation while recommending another product. The competitor AI citation audit template explains how to connect each cited page to the feature, price, integration, security claim, or use case it supports.
How Do You Run the Competitive Audit?
A defensible audit uses stable prompts, repeated observations, and consistent scoring. The objective is not to reproduce a personalized user experience perfectly; it is to create a comparable baseline that can be measured again.
- Select three direct competitors and one category leader. Avoid filling the sheet with loosely related companies.
- Freeze the prompt set. Do not rewrite prompts after seeing unfavorable results.
- Test at least three relevant engines. Record the exact surface, such as ChatGPT Search or Google AI Mode.
- Repeat each prompt twice. Run the second test on another day when possible.
- Normalize brand names and domains. Merge spelling variations before calculating totals.
- Separate mentions, citations, and recommendations. They represent different levels of visibility.
- Assign every gap an owner and action. A score without a decision is only a snapshot.
For 24 prompts across four engines with two runs, the workbook should contain 192 answer observations: 24 × 4 × 2. Missing observations must remain blank rather than being converted into zeros.
Which Metrics Belong in the Scorecard?
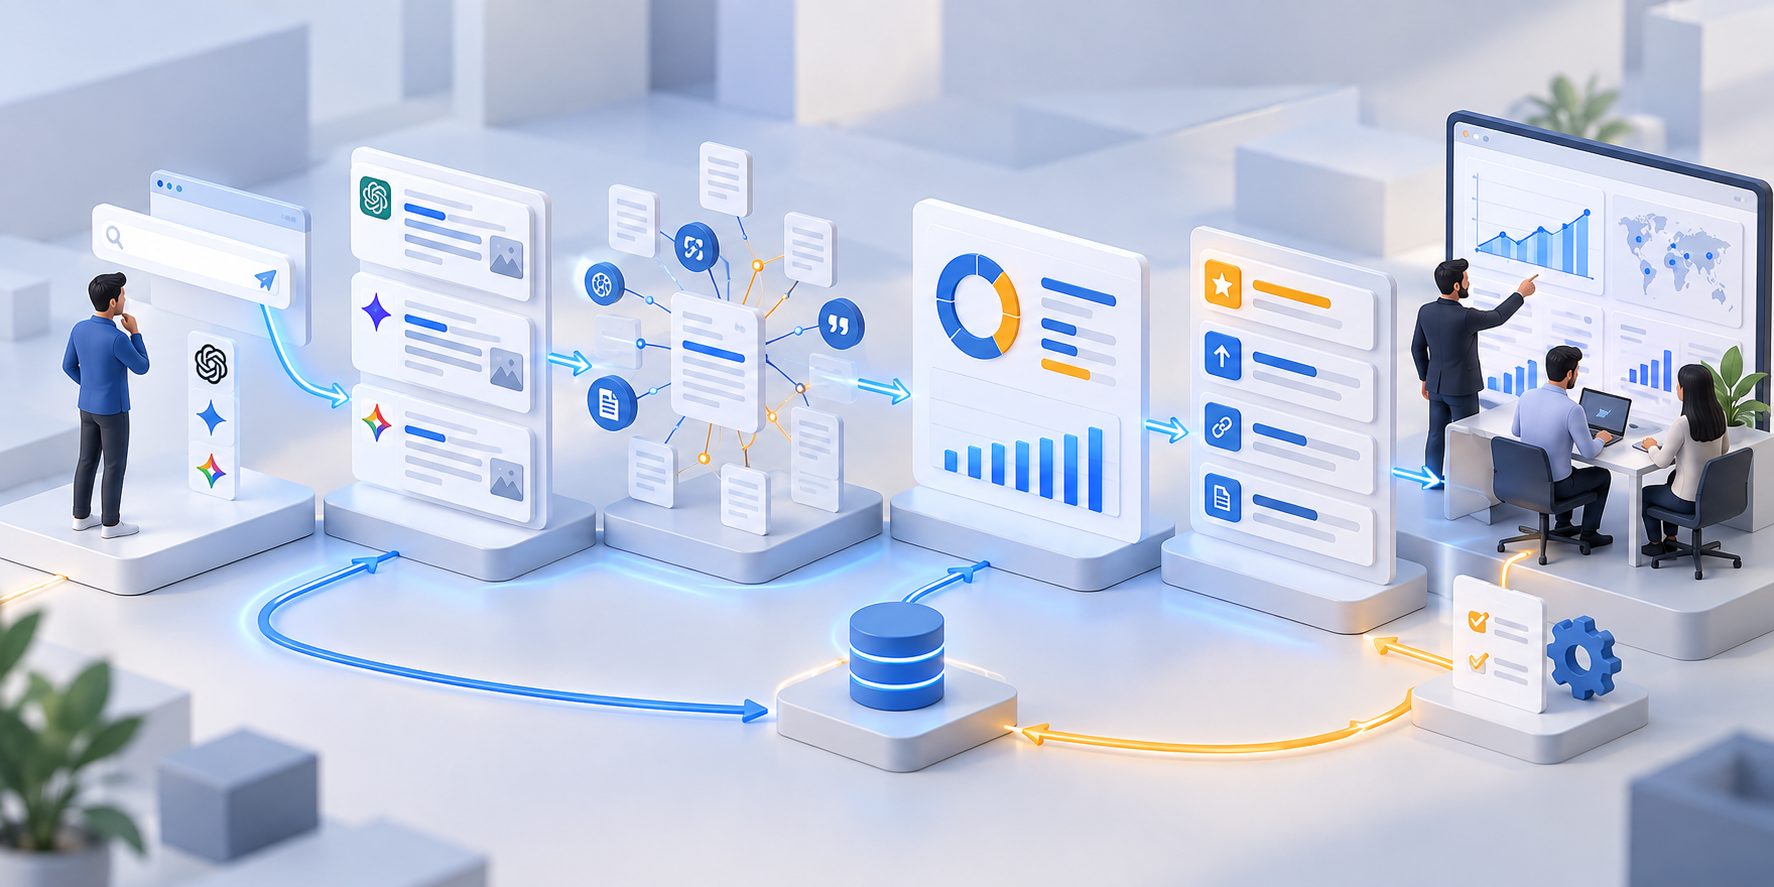
The scorecard should distinguish visibility from preference. Mention rate shows whether a brand enters the answer; recommendation rate shows whether the engine actively presents it as a suitable choice.
| Metric | Formula |
|---|---|
| Mention rate | Answers mentioning brand ÷ completed answers |
| Recommendation rate | Answers recommending brand ÷ completed answers |
| Top-three rate | Answers placing brand in positions 1–3 ÷ completed answers |
| Citation rate | Answers citing a brand-owned source ÷ completed answers |
| Share of voice | Brand mentions ÷ mentions of all tracked brands |
| Source recurrence | Runs containing source ÷ eligible runs |
| Accuracy risk | Inaccurate or outdated mentions ÷ brand mentions |
Use position weighting when first place should count more than an unranked mention. A practical model assigns 1.0 to first place, 0.7 to second, 0.5 to third, and 0.2 to other mentions. For cross-engine reporting, the weighted AI visibility scoring framework provides a more detailed approach.
How Should Competitive Gaps Be Prioritized?
Prioritize gaps by business importance, competitor lead, recurrence, missing evidence, and actionability. Then discount the score when the audit is incomplete. This confidence adjustment prevents teams from prioritizing an apparent loss based on only one or two observations.
Use the following original framework:
Base Opportunity = 1.25 × [(Intent × 4) + (Competitor Lead × 4) + (Recurrence × 3) + (Evidence Gap × 3) + (Actionability × 2)]
Score each factor from 1 to 5. The maximum Base Opportunity is 100.
Confidence-Adjusted Priority = Base Opportunity × (Completed Observations ÷ Planned Observations)
Consider an illustrative, synthetic example: a comparison prompt scores 5 for intent, 4 for competitor lead, 4 for recurrence, 5 for evidence gap, and 4 for actionability. Its Base Opportunity is 89. If only six of eight planned observations are complete, the final priority is 67, signaling a meaningful gap that requires more validation before immediate escalation.
When Should a Spreadsheet Become Automated Monitoring?
A spreadsheet works well for an initial audit or a small, stable prompt set. It becomes difficult to maintain when teams need daily trends, several markets, many competitors, or preserved answers across multiple AI platforms.
MaxAEO monitors mentions, citations, recommendation positions, sentiment, and competitor performance across eight AI engines, with daily data updates. It also preserves source-level evidence and compares brands by engine and prompt.
Teams can use the daily AI engine competitor monitoring framework to establish an ongoing measurement process. A free AI visibility diagnosis is also available on maxaeo.ai by entering a brand website; no code installation or internal customer data is required.
Frequently Asked Questions
How many prompts should the first audit include?
Start with 12–24 prompts. Include discovery, use-case, comparison, alternative, objection, and purchase-validation questions rather than using only branded prompts.
How many competitors should be tracked?
Track three direct competitors and one category leader. This provides a meaningful benchmark without making manual answer classification unnecessarily complex.
How often should the audit be repeated?
Repeat a manual audit monthly using the same core prompts. Daily monitoring is more appropriate when campaigns are active, reputation changes quickly, or several engines and markets must be compared.
What counts as a genuine GEO improvement?
A genuine improvement appears repeatedly across the same prompts and several engines. Look for higher mention and recommendation rates, better positions, stronger sentiment, more relevant citations, and fewer factual inaccuracies—not one favorable response.