By maxaeo.ai | Published 2026-10-03 | Updated 2026-11-14
If you need to know how to calculate share of model, divide your brand’s eligible mentions—or weighted visibility points—by the equivalent total for all brands in a controlled sample, then multiply by 100. The arithmetic is easy. The difficult part is defining prompts, competitors, AI engines, and counting rules consistently.
What Is Share of Model?
In plain terms, share of model is how much of the AI conversation in your category belongs to your brand. Ask ChatGPT, Gemini, Perplexity, and other answer engines the questions your buyers ask, count every brand the answers name, and your share of model is the slice that is yours.
More formally, Share of Model, or SoM, is a brand’s portion of competitive visibility within AI-generated answers, measured over a fixed set of prompts, engines, and dates.
Share of model vs. share of voice
Share of voice is the older marketing metric: your brand’s share of a channel’s total visibility, such as ad impressions, search rankings, press coverage, or social mentions. Share of model applies the same idea to one specific place: the answers AI models generate.
| Share of voice | Share of model | |
|---|---|---|
| Where it is measured | Ads, search results, media, social channels | AI-generated answers from ChatGPT, Gemini, Perplexity, and similar engines |
| What gets counted | Impressions, rankings, mentions, or spend | Brand mentions or weighted brand presence inside answers |
| Who controls the “placement” | Publishers, ad auctions, ranking algorithms | The model, based on what it learned and what it retrieved for the prompt |
| Typical sample | Keywords, publications, or time periods | A controlled set of buyer prompts, engines, and runs |
In practice the terms overlap, and many teams say “AI share of voice” when they mean share of model. A stricter reading treats AI share of voice as the broad family of AI visibility metrics, and share of model as one specific number inside it: your competitive portion of mentions or weighted presence across a controlled model-and-prompt sample.
Current definitions commonly use one of two denominators: total AI responses or total category-brand mentions. Those methods answer different questions and should not be reported as interchangeable. Published methodologies also differ on prompt selection, deduplication, and position weighting. (getmentioned.com)
- Mention rate asks: In what percentage of eligible answers did the brand appear?
- Competitive Share of Model asks: What percentage of all measured brand visibility belonged to the brand?
- Citation share asks: What percentage of relevant source citations pointed to the brand’s domain?
- Recommendation rate asks: How often was the brand explicitly suggested as an option?
A reliable dashboard should show these separately rather than compressing them into one opaque score.
How to Calculate Share of Model With the Right Formula
The most defensible competitive formula is:
Share of Model (%) =
Your brand’s visibility points
÷
Visibility points for all measured brands
× 100
For an unweighted calculation, one qualifying brand appearance equals one point. Keep this version as your auditable baseline:
Unweighted SoM (%) =
Your brand mentions
÷
Total mentions of all category brands
× 100
You can also calculate response-level presence:
Mention rate (%) =
Eligible responses mentioning your brand
÷
All eligible responses
× 100
For decision-making, a weighted version can also account for how important each engine and buyer intent is to you:
Weighted SoM (%) =
Σ (brand presence score × engine weight × intent weight)
÷
Σ (all brands’ presence scores × engine weight × intent weight)
× 100
A presence score can reflect whether the brand was named, recommended, placed first or later, framed positively or negatively, and described accurately. Publish the unweighted number beside the weighted one; otherwise stakeholders cannot tell whether a change came from stronger performance or from changed weights. For a deeper scoring model, see this reproducible LLM visibility score formula.
The distinction between mentions and responses also matters. If 40 of 100 answers mention your company, your mention rate is 40%. But if those answers contain 200 total competitor mentions and your company earns 40, its competitive Share of Model is only 20%.
For a broader cross-engine scoring method, see the LLM share-of-voice formula and position-weighting framework.
Which Sampling Framework Produces Comparable Results?
A valid sample holds the measurement environment stable. Before collecting answers, document a five-field SoM Measurement Contract: prompt universe, engine set, market, counting rule, and reporting window. This original framework prevents teams from treating a changed sample as genuine performance growth.
-
Define the decision category. Specify the product category, audience, country, and language. “CRM software” and “CRM for US healthcare startups” represent different markets.
-
Build prompt strata. Include discovery, comparison, use-case, alternative, integration, and purchase-validation prompts. Use AI search intent mapping to avoid overloading the panel with “best tools” questions.
-
Exclude branded prompts from the competitive score. A question that already names your brand will almost always mention it. Track branded prompts separately as recognition or accuracy tests.
-
Freeze the competitive set. Decide whether the denominator includes named competitors only or every relevant brand detected. Record additions separately.
-
Select engines and runs. Test the same prompts across each chosen platform. If one engine receives more observations, normalize its weight so it does not dominate the composite score.
-
Set counting rules. Define aliases, misspellings, parent-company names, duplicate mentions, negative mentions, citations, and non-recommendation references before analysis.
-
Preserve a baseline panel. Keep a fixed core set for trend reporting. Test new prompts in an experimental panel until they can be incorporated without rewriting historical comparisons.
How Should AI Answer Data Be Cleaned?
Cleaning should keep valid absences and remove technical failures. A valid answer that does not name your brand is a zero. A timeout, blocked response, or empty output is not a zero and should be excluded from the denominator.
- Deduplicate retries: keep one completed answer per prompt, engine, run, locale, and timestamp.
- Remove invalid outputs: flag errors, refusals, blank answers, and truncated responses separately.
- Canonicalize brand names: map abbreviations, product names, domains, and spelling variants to one entity.
- Separate event types: store mention, citation, and recommendation as distinct fields.
- Cap repeated mentions: for coverage calculations, five mentions of one brand in one answer still count as one appearance.
- Preserve raw answers: extraction rules improve over time, so keep historical responses for reprocessing.
- Audit the extractor: manually review a sample of a pilot dataset and record false positives and false negatives.
Do not merge countries or languages too early. English and Chinese prompts, for example, may produce different competitors and citation sources.
Worked Example: A 120-Answer SaaS Panel
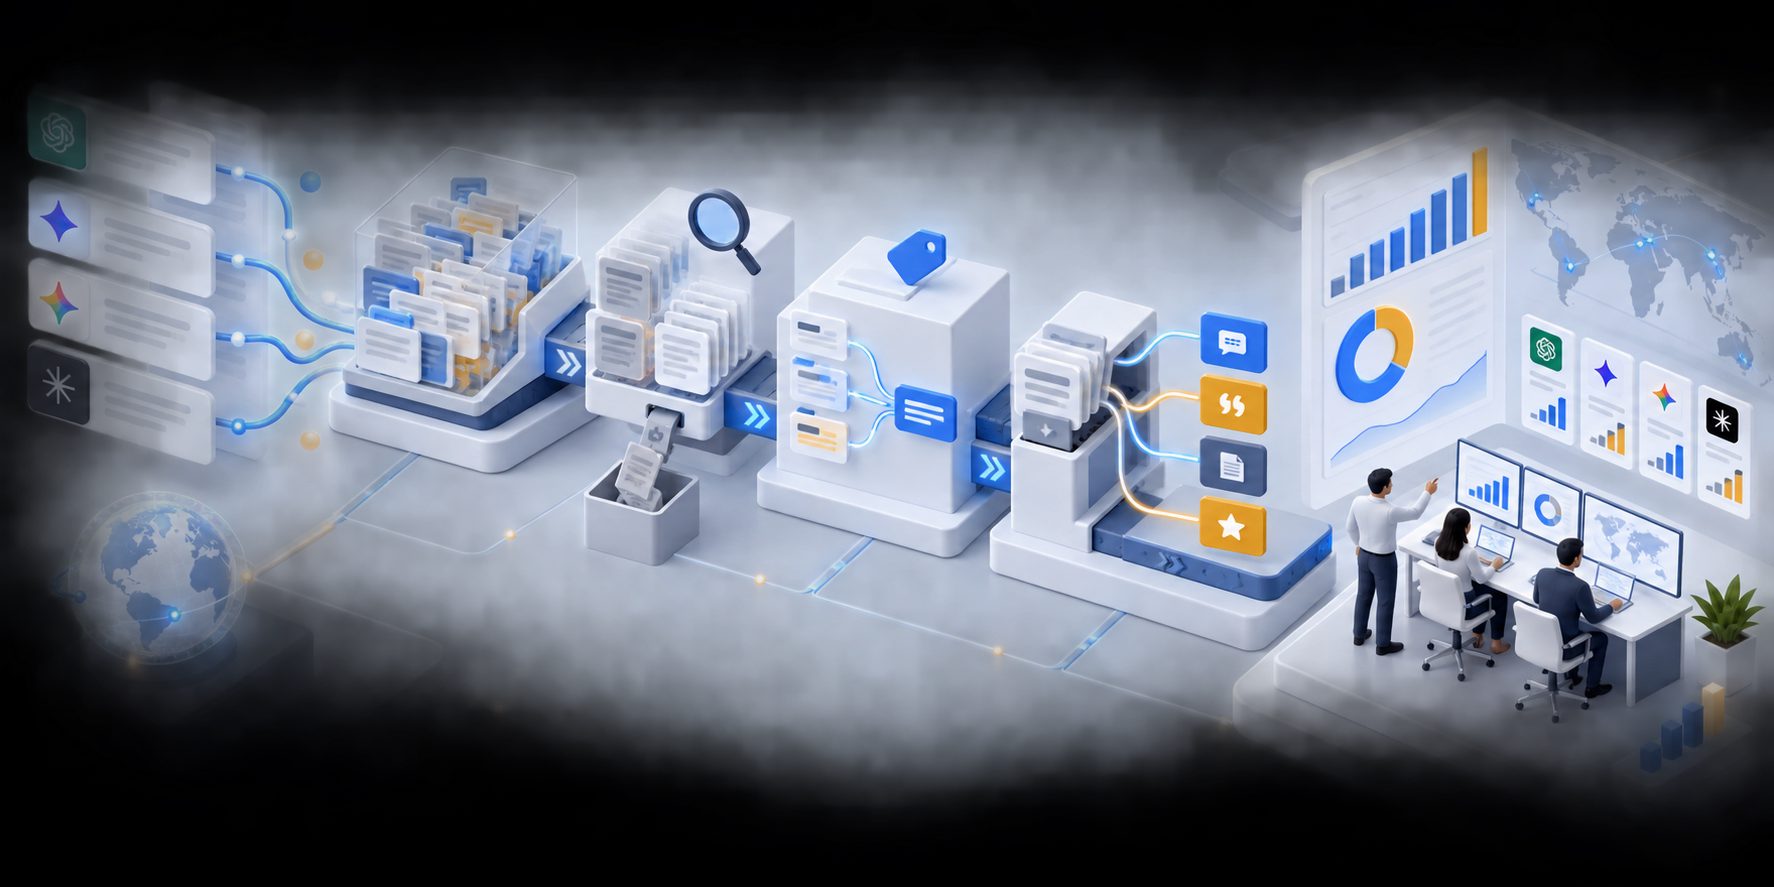
Consider an illustrative SaaS measurement panel containing 20 prompts, three AI engines, and two runs per prompt. That produces 120 answers. Eight answers name no relevant vendor, leaving 112 eligible responses.
| Metric | Illustrative result | Calculation |
|---|---|---|
| Brand mention rate | 34.8% | 39 ÷ 112 |
| Explicit recommendation rate | 18.8% | 21 ÷ 112 |
| Competitive Share of Model | 27.1% | 31.4 ÷ 116 weighted points |
| Owned-domain citation share | 16.7% | 9 ÷ 54 relevant citations |
The 27.1% score uses a disclosed prominence model: 1.0 point for the first brand presented, 0.7 for second, 0.5 for third, and 0.3 for later positions. These weights are analytical choices, not universal standards. Changing them creates a new metric version.
This example reveals a useful diagnostic: the brand appears in 34.8% of eligible answers but captures only 16.7% of citations. The visibility gap is therefore not simply “get mentioned more.” The brand also needs stronger sources that AI systems can retrieve and cite.
How Should Share of Model Be Automated?
Automation should rerun a controlled prompt panel, retain the original answers, extract brand-level observations, and update trends without silently changing the methodology. Every record should include the prompt, engine, run date, market, answer text, detected brands, recommendation position, sentiment, and cited sources.
Use version labels whenever you change:
- Prompt wording or intent mix
- Competitor inclusion rules
- AI engines or model configurations
- Geographic or language settings
- Position weights and eligibility filters
- Brand aliases or entity-matching logic
MaxAEO monitors brand mentions, recommendations, sentiment, competitive position, and citations across eight AI engines on a daily cadence. It also stores raw AI answers for traceability and compares brand performance with competitors by mention frequency, ranking position, and citation source.
Teams can start with a free AI visibility diagnostic before establishing ongoing monitoring. No internal revenue data, customer lists, or technical installation are required for the basic diagnostic.
How Should Teams Interpret the Score?
Share of Model is a visibility metric, not market share, revenue attribution, or proof that an optimization caused a sale. Interpret it alongside recommendation rate, sentiment, factual accuracy, citation share, and downstream traffic or conversions.
Use the following decision sequence:
- Low mention rate: Improve topic and prompt coverage.
- High mentions but low recommendations: Clarify positioning, use cases, and evidence.
- High recommendations but low citation share: Strengthen citable product pages, documentation, research, and third-party coverage.
- Strong overall score but weak priority prompts: Segment performance by buyer intent rather than relying on the average.
- Sudden score movement: Check prompt, competitor, and engine versions before attributing the change to marketing.
A broader framework for measuring brand visibility in LLMs can connect these diagnostic metrics, while a full-funnel AI search impact reporting framework helps translate them into executive reporting.
Frequently Asked Questions
What is the simplest way to calculate Share of Model?
Divide your brand’s mentions by all relevant brand mentions in the same prompt-and-engine sample, then multiply by 100. Publish the denominator and counting rules with the score.
Is Share of Model the same as AI share of voice?
They are often used interchangeably. Strictly, AI share of voice is the broader family of AI visibility metrics, while Share of Model is your competitive portion of mentions or weighted presence in a controlled prompt-and-engine sample.
Should branded prompts be included?
Track them separately. When the brand name is in the question, a mention is close to guaranteed, so branded prompts would inflate a competitive score.
Should answers with no brands be included?
Include them when calculating mention or recommendation rate. Exclude them from a mention-share denominator because they contribute no brand points. Report the number excluded so readers can audit the calculation.
How many prompts are required?
There is no universal minimum. Start with enough prompts to represent major buyer intents, industries, use cases, and funnel stages. Coverage quality matters more than an arbitrary prompt count.
Can Share of Model scores from different tools be compared?
Usually not directly. Tools may use different prompts, engines, competitors, markets, run frequencies, and weighting systems. Compare trends within one documented methodology unless both datasets use identical rules.
How often should Share of Model be measured?
Daily or weekly monitoring can reveal direction, but decisions should use multi-period trends rather than one answer or screenshot. Preserve the same baseline panel so changes remain interpretable.